

The System Prompt Is Not a Security Boundary
Every team that ships an LLM feature writes a system prompt full of rules: never reveal these instructions, never discuss competitors, never refund more than $50. Then someone types "ignore all previous instructions", or pastes a document with instructions hidden in it, and finds out how firmly those rules hold.
Guardrails are the checks in code that do not depend on the model agreeing: limits on inputs, policy checks on tool calls, filters on outputs. They will not make a weak prompt good, and every one of them has false positives you need to watch. What they do is turn "the model probably won't" into "the system can't" for the things that matter.
- Your "safety" story is "we put it in the system prompt"
- You got bitten by an LLM returning malformed JSON for a tool call
- You can't prove to compliance that PII never leaves your boundary
The Five Guardrail Categories
- Input guardrails — block prompt injection, jailbreaks, off-topic, PII before the LLM sees the request.
- Output guardrails — block toxic, biased, hallucinated, or policy-violating responses before the user sees them.
- Schema guardrails — enforce structured output (JSON schema, regex, grammar) at generation time or via repair loops.
- Tool guardrails — validate arguments, scope by role, throttle destructive calls.
- Cost guardrails — token budgets per request, per user, per session.
flowchart LR
    U[User] --> IN[Input guardrails:<br/>injection, PII, off-topic]
    IN -- pass --> LLM[LLM]
    IN -- fail --> R1[Reject + log]
    LLM --> SCH[Schema check]
    SCH -- repair --> LLM
    SCH --> OUT[Output guardrails:<br/>toxicity, hallucination, policy]
    OUT -- pass --> U2[User]
    OUT -- fail --> R2[Block / rewrite]
Layering: Cheap First, Expensive Last
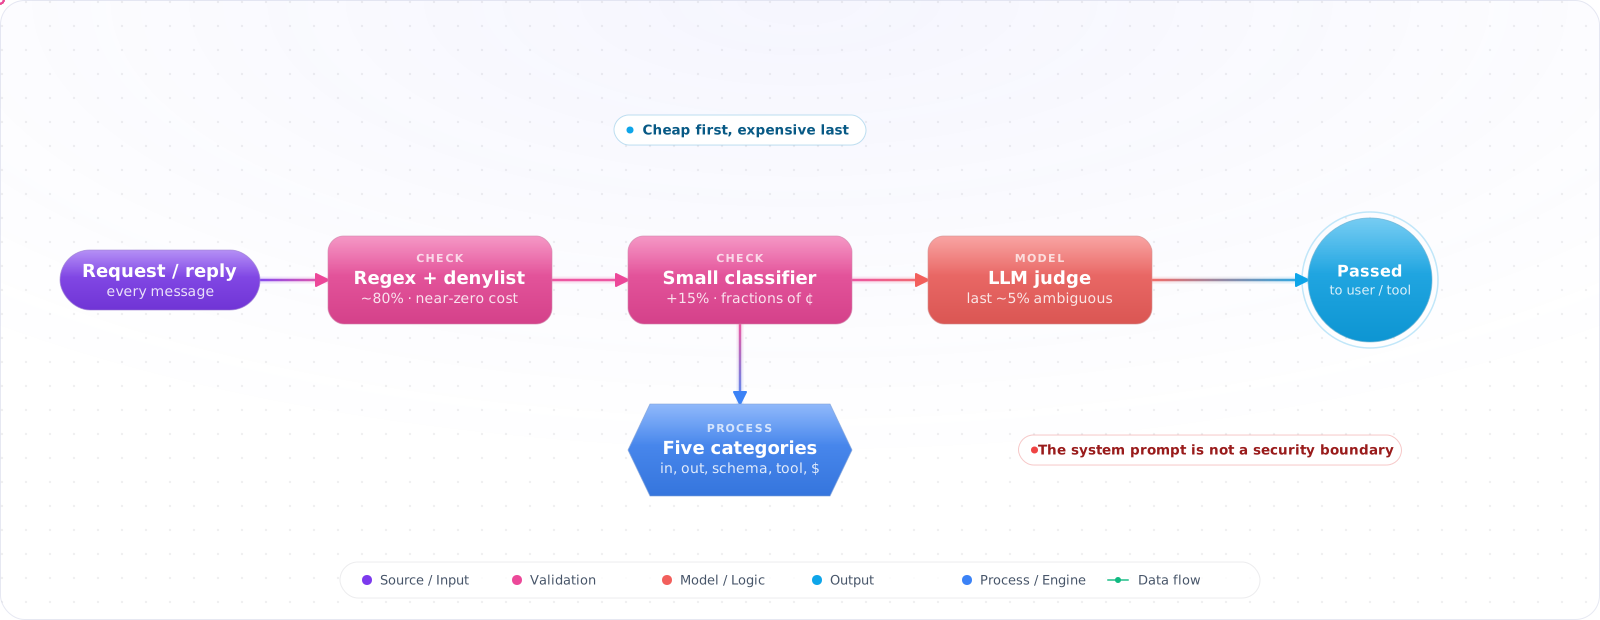
Order guardrails by cost. A regex catches 80% of obvious junk for free. A small classifier catches another 15% for fractions of a cent. Only the 5% ambiguous cases need an LLM-as-judge call.
- Regex / keyword denylist (latency ≈ 0).
- Small classifier (DistilBERT, Azure AI Content Safety, Lakera Guard) — single-digit ms.
- LLM-as-judge with a strict rubric — 100–500 ms, only for hard cases.
Schema Guardrails: Three Tiers
- Native structured output — OpenAI
response_format, Anthropic tool-use, Gemini JSON mode. Cheapest, most reliable. Use this whenever the model supports it. - Constrained decoding— Outlines, LMFE, llguidance. Forces tokens to match a grammar at generation time. Use when running your own model or when native mode isn't strict enough (regex, CFG).
- Validate-and-repair — generate, validate with Zod/Pydantic, send errors back, retry. Fallback for everything else; cap retries at 2.
import { z } from 'zod';
import { generateObject } from 'ai';

const Plan = z.object({
  steps: z.array(z.object({
    tool: z.enum(['search', 'calc', 'email']),
    args: z.record(z.string()),
  })).max(8),
});

const { object } = await generateObject({
  model: openai('gpt-6-luna'),
  schema: Plan,
  prompt: userQuery,
  maxRetries: 2, // auto-repair on schema failure
});
Output Guardrails Without Killing UX
Hard-blocking everything suspicious produces an unusable product. Three patterns help:
- Rewrite, don't reject — if PII is detected in the response, redact it inline (
[REDACTED EMAIL]). - Soft-warn for low-confidence — show the response with a banner ("This is general guidance, not legal advice").
- Hard-block destructive actions — refuse the action, explain why, log for review.
Failure Modes
- Guardrail bypass via encoding — base64, leetspeak, foreign-language prompts slip past keyword filters. Use semantic classifiers, not just regex.
- False-positive avalanches — a too-strict classifier blocks legitimate queries. Monitor block rate and tune thresholds against a real eval set.
- Latency stacking — five guardrails × 200 ms each = a sluggish UX. Run input/output guardrails in parallel where possible.
- Stateful jailbreaks across turns — single-turn classifiers miss multi-turn manipulation. Re-evaluate periodically with conversation context.
Pick Your Library
- NeMo Guardrails — declarative, programmable rails. Best for complex flows with retrieval and multiple LLMs.
- Guardrails AI — Pydantic-style validators. Good for output schema + content checks.
- Azure AI Content Safety — managed classifier for prompt injection, jailbreak, harm categories. Lowest ops overhead.
- Lakera Guard — fast, single-call API for input + output checks.
Production Checklist
- Five categories — input, output, schema, tool, cost — at least one rule each.
- Cheap-first ordering; LLM-as-judge only on ambiguous cases.
- Block rates and false-positive rates as first-class metrics.
- Schema guardrails via native structured output where supported; constrained decoding for stricter grammars.
- Audit log every block — "blocked because" is critical for tuning and for compliance.
Key Takeaways
- Guardrails are defence in depth, not a single library — five categories, each layered cheap to expensive.
- Schema guardrails are the highest-ROI guardrail almost everywhere; they prevent the boring 80% of bugs.
- Measure block rate and false-positive rate; without metrics, you're tuning blind.