

AI Engineering
RAG, multi-agent systems, prompt engineering, token economics, evaluations and guardrails — the production discipline of building with LLMs.
12 articlesin AI Engineering
Agent Design Patterns: Start One Rung Lower
Prompt chaining, routing, orchestrator-workers, ReAct, plan-and-execute, reflection and tree search: what each costs, what the research shows, and when to climb to the next one.
Model Serving With vLLM: The KV Cache Decides Your Capacity
KV cache arithmetic, PagedAttention, continuous batching, prefix caching, FP8 and speculative decoding, the vLLM flags that matter, and the five metrics that show which limit you hit.
Voice Agents: A Real-Time Problem With a Model Inside
Speech-to-speech or a pipeline, a latency budget for every stage, interruptions that really work, prompts written for the ear, and what a call actually costs.
Guardrails: Input/Output Safety in Production
Input, output, schema, tool, and cost guardrails — the layered defence system that catches LLM failures before they reach a user or downstream system.
Embeddings: From Theory to Production Choice
Convert text, images, and code into dense vectors that capture semantic meaning — the foundational primitive of modern AI systems, and the choice that dominates RAG quality.
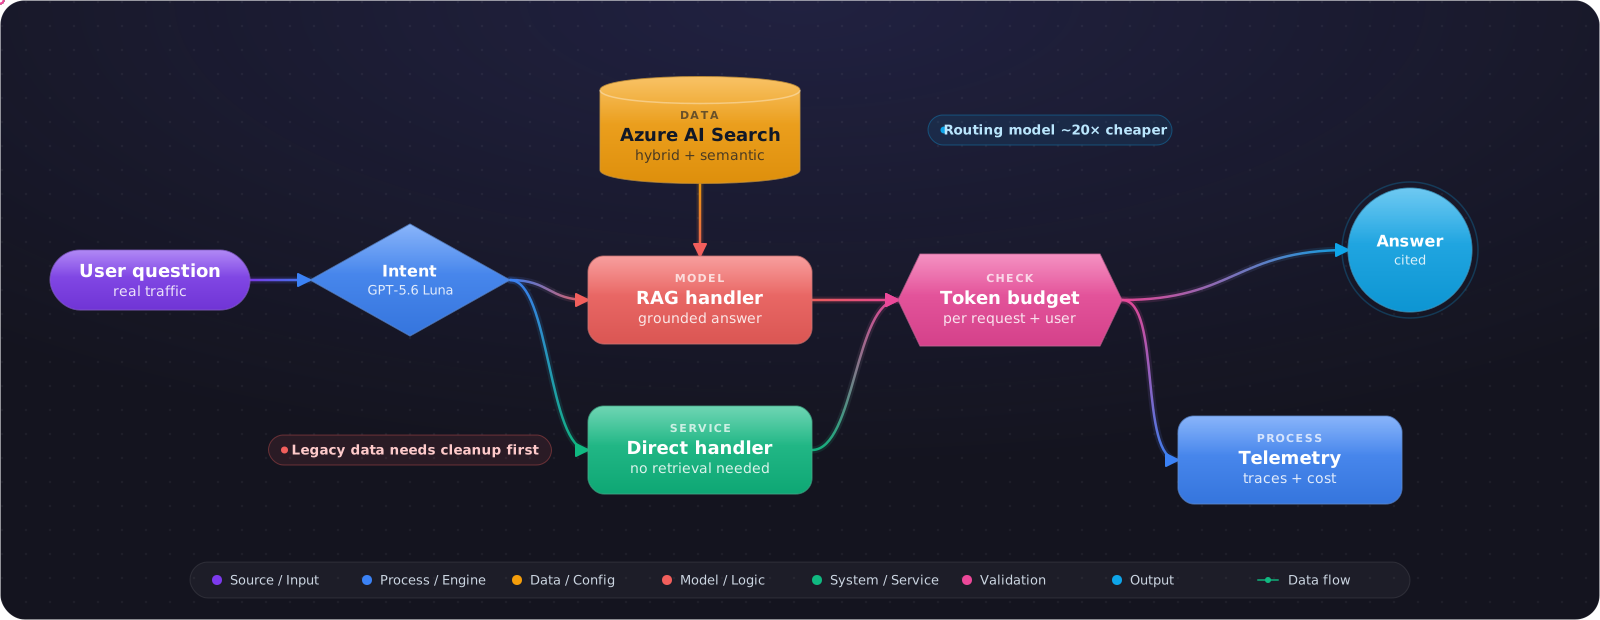
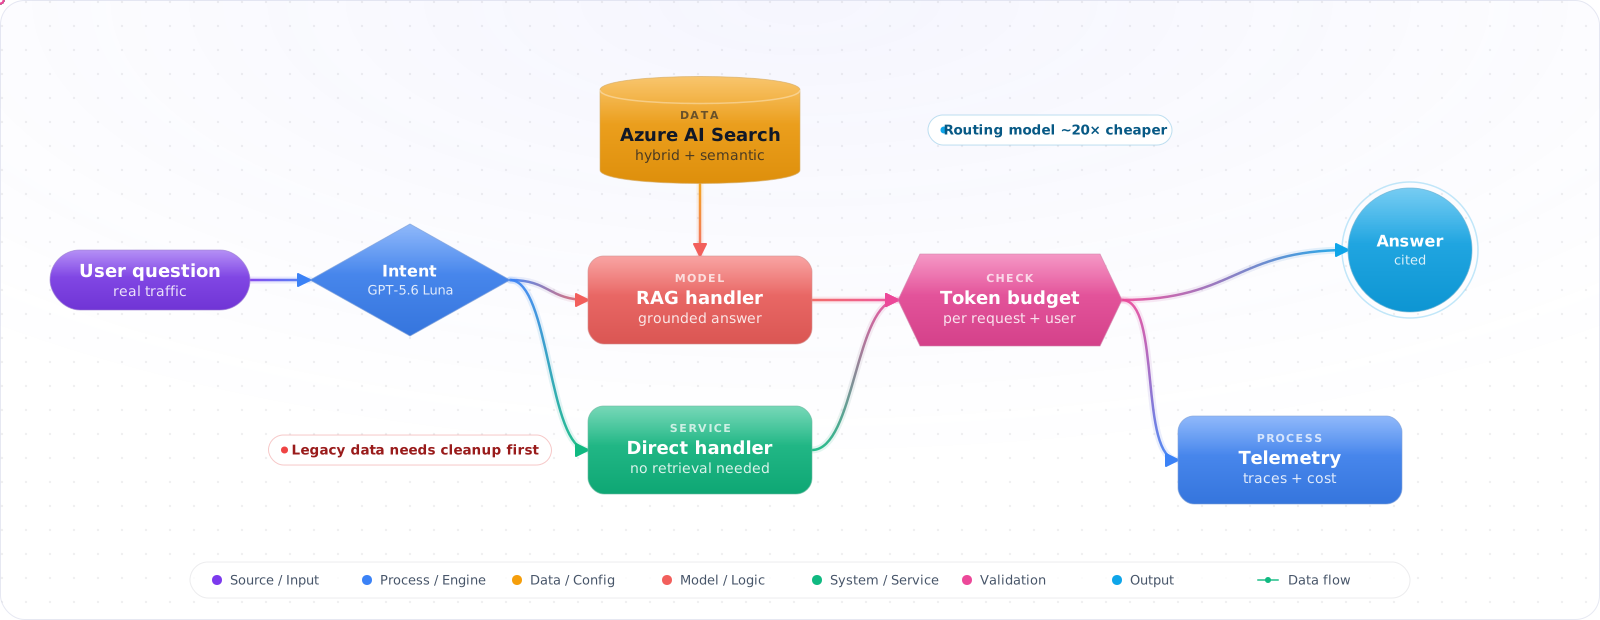
How to Build a Production-Ready AI System (Azure OpenAI + AI Search — Real Architecture)
Azure OpenAI + AI Search + embeddings — real-world architecture for production AI systems, including legacy data, orchestration, hybrid retrieval, cost control, and failure modes.
Token Economics: Understanding and Optimizing LLM Costs
A practical guide to understanding token pricing, measuring real costs, and implementing optimization strategies — caching, prompt compression, model routing.
Building Reliable AI Agents with Semantic Kernel
Plugin architecture, memory, planners, and error handling patterns for building production AI agents in .NET with Semantic Kernel.
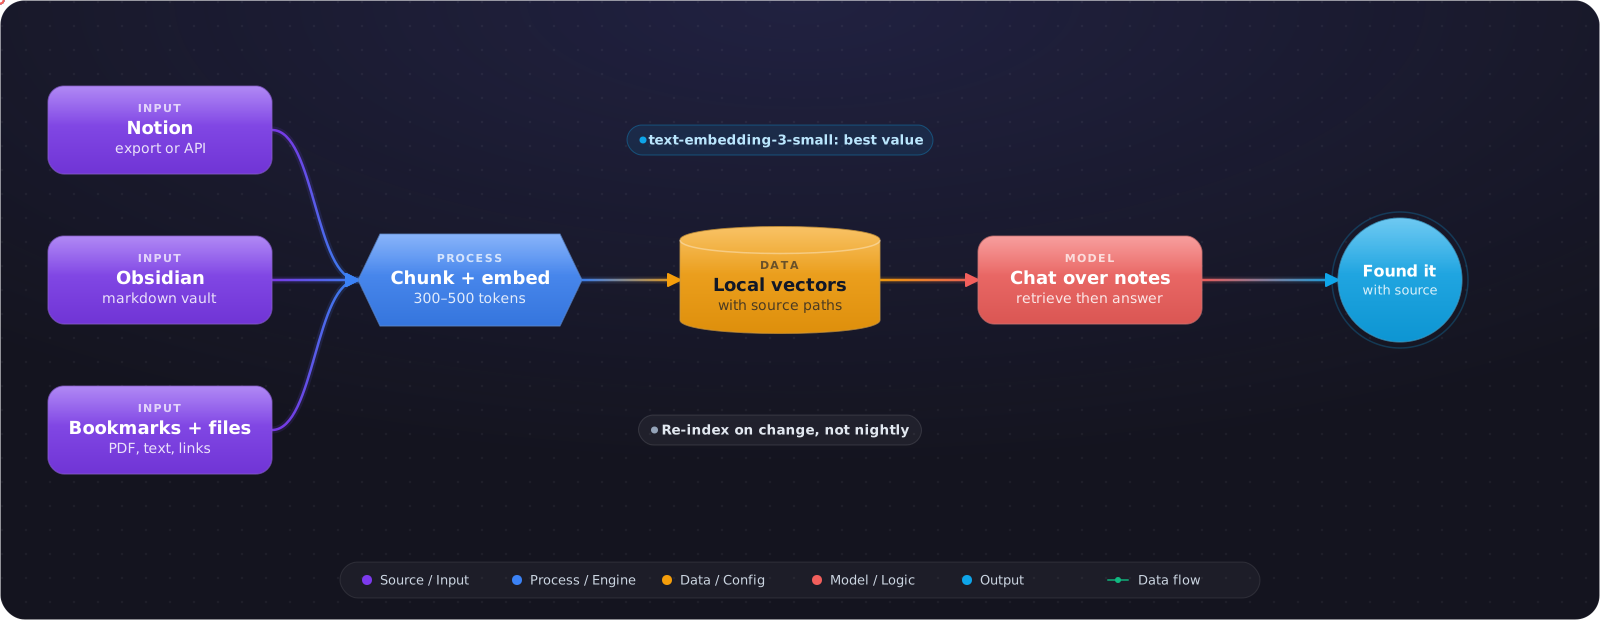
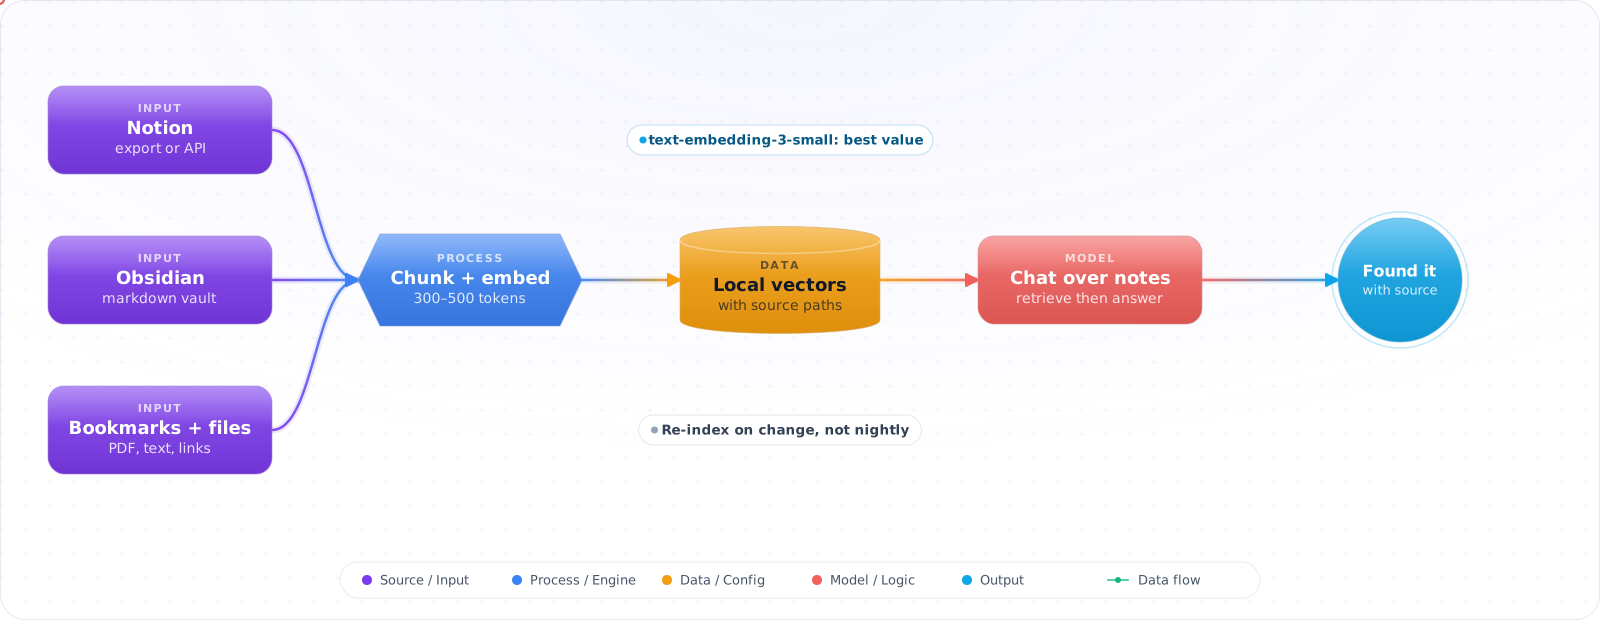
Building a Personal AI Knowledge Base
How to build a personal RAG system over your notes, bookmarks, and documents — using embeddings, vector search, and a conversational interface.
When to Fine-Tune vs Few-Shot vs RAG
A decision framework for choosing between fine-tuning, few-shot prompting, and RAG for production LLM applications.
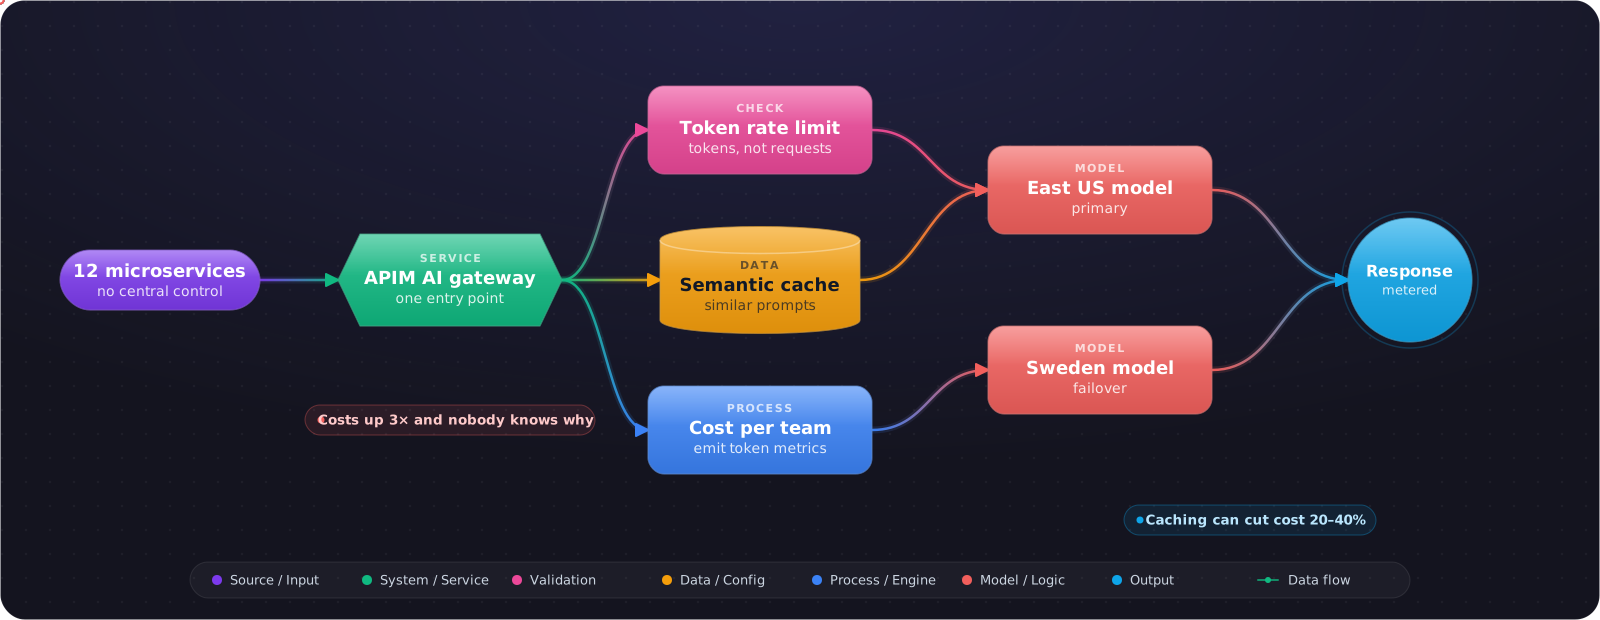
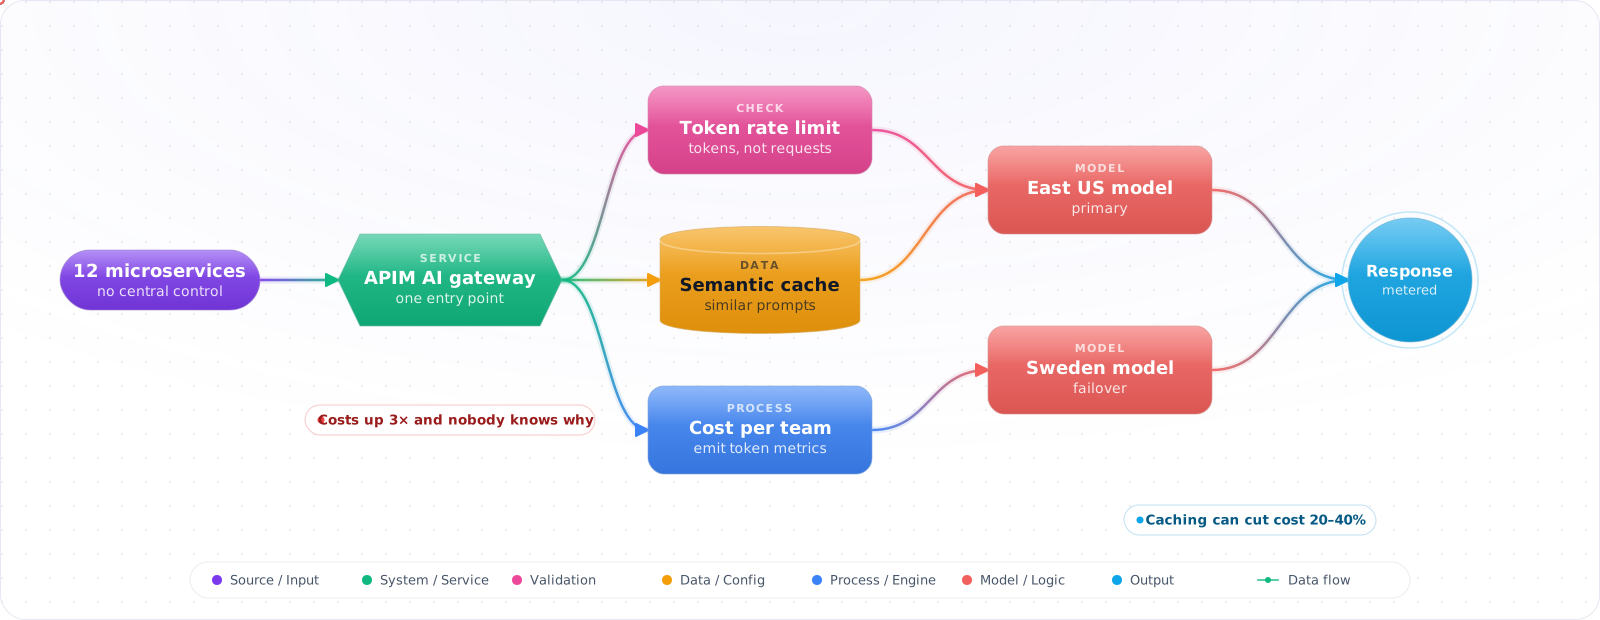
The AI Gateway Pattern: Why Every Production LLM Needs One
API Management, rate limiting, semantic caching, and cost control with Azure APIM as an AI Gateway.
Designing RAG Systems That Actually Scale
Chunking strategies, embedding pipelines, retrieval patterns, and when RAG breaks down in production systems.