


The Shape of the Tree Decides the Cost
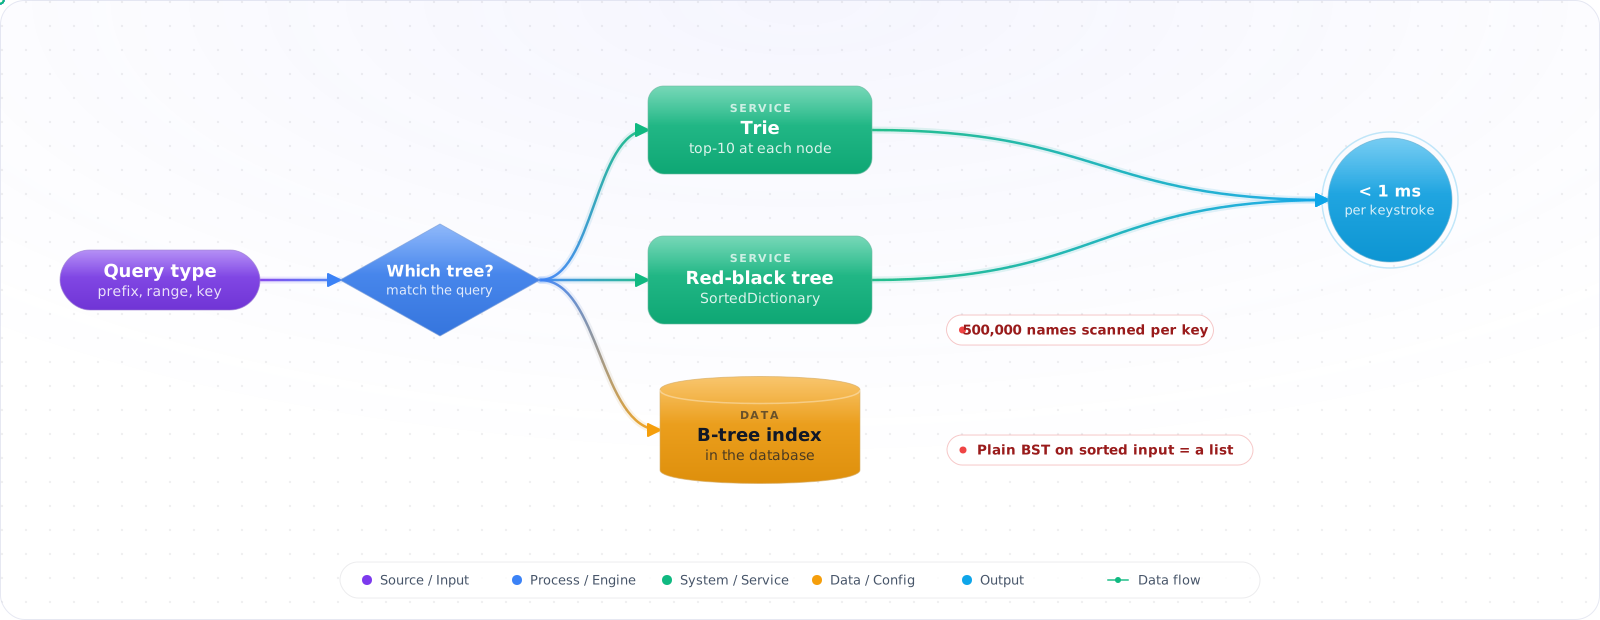
Take a typical case, made up for illustration. A search box suggested product names by scanning half a million names on every keystroke. The first fix was a hand-written binary search tree, loaded from a file that happened to be sorted. Every node got only a right child, and the “tree” became a linked list that was slower than the scan it replaced.
Trees are everywhere: file systems, the DOM, every database index, every parsed document. Their cost depends almost entirely on shape. Balanced trees give logarithmic operations; unbalanced ones can degrade to linear. Below is which tree to use for which question, what your standard library already gives you, and when a trie or the database's B-tree is the better answer.
- You can't explain why
SortedDictionaryis O(log n) butDictionaryis O(1) - You wrote a recursive tree traversal that overflows on 100,000 nodes
- You don't know the difference between BST, AVL, red-black, and B-tree
- You've never used a heap when a heap was the right answer
BSTs, Balanced Trees, Heaps and Tries
Five families cover almost every real-world need:
- Binary Search Tree (BST) — left < node < right. O(log n) when balanced, O(n) when not. Don't use a plain BST in production.
- Self-balancing BST (Red-Black, AVL) — guaranteed O(log n) operations.
SortedDictionary<K,V>andSortedSet<T>in .NET are red-black. - B-tree / B+tree — high fan-out (hundreds of children per node), tuned for disk/SSD pages. The default index type in relational databases such as PostgreSQL.
- Heap — partially ordered tree (parent ≤ children for min-heap). O(log n) push/pop, O(1) peek. .NET 6 ships
PriorityQueue<TElement, TPriority>as a min-heap. - Trie / Prefix tree — one node per character; great for autocomplete, IP routing, dictionary-based string matching.
flowchart LR
P["Need a tree?"] --> Q1{"Need ordered<br/>iteration / range?"}
Q1 -->|no| H{"Need top-K /<br/>priority?"}
H -->|yes| HEAP["PriorityQueue<T,P><br/>(min-heap)"]
H -->|no| HASH["Dictionary<K,V><br/>(hash, not a tree)"]
Q1 -->|yes| Q2{"Prefix queries?"}
Q2 -->|yes| TRIE["Trie<br/>(roll your own)"]
Q2 -->|no| Q3{"On disk /<br/>huge dataset?"}
Q3 -->|yes| BTREE["B-tree<br/>(use a real DB index)"]
Q3 -->|no| RB["SortedDictionary / SortedSet<br/>(red-black, in BCL)"]
style RB fill:#16a34a,color:#fff,stroke:#15803d
style HEAP fill:#0078D4,color:#fff,stroke:#005a9e
Using and Walking Trees in Real Code
Step 1: 90% of the time — use the BCL
// Self-balancing ordered map: O(log n) for all ops, ordered iteration
var byTime = new SortedDictionary<DateTime, Order>();
byTime.Add(DateTime.UtcNow, order);
// SortedDictionary has no seek: this LINQ query walks from the smallest key, O(n)
var firstAfter = byTime.First(kv => kv.Key > cutoff);

// Min-heap (since .NET 6)
var pq = new PriorityQueue<Job, int>();
pq.Enqueue(job, priority: 5);
pq.Enqueue(other, priority: 2);
var next = pq.Dequeue();              // pops job with smallest priority

// Range views (without copying)
var sortedSet = new SortedSet<int>(numbers);
var range = sortedSet.GetViewBetween(10, 20);   // O(log n) + O(k)
Step 2: A real BST node — when you need full control
public class Node<T> where T : IComparable<T>
{
    public T Value;
    public Node<T>? Left, Right;
    public Node(T v) => Value = v;
}

public class BST<T> where T : IComparable<T>
{
    private Node<T>? _root;

    public void Insert(T v) => _root = Insert(_root, v);
    private static Node<T> Insert(Node<T>? n, T v)
    {
        if (n is null) return new Node<T>(v);
        int c = v.CompareTo(n.Value);
        if      (c < 0) n.Left  = Insert(n.Left,  v);
        else if (c > 0) n.Right = Insert(n.Right, v);
        return n;
    }

    public bool Contains(T v)
    {
        var n = _root;
        while (n is not null)
        {
            int c = v.CompareTo(n.Value);
            if (c == 0) return true;
            n = c < 0 ? n.Left : n.Right;
        }
        return false;
    }
}
Step 3: Iterative in-order traversal (no stack overflow)
public static IEnumerable<T> InOrder<T>(Node<T>? root) where T : IComparable<T>
{
    var stack = new Stack<Node<T>>();
    var n = root;
    while (n is not null || stack.Count > 0)
    {
        while (n is not null) { stack.Push(n); n = n.Left; }
        n = stack.Pop();
        yield return n.Value;
        n = n.Right;
    }
}
Step 4: Heap from scratch (when you need a custom comparer)
public class MinHeap<T>
{
    private readonly List<T> _h = new();
    private readonly IComparer<T> _cmp;
    public MinHeap(IComparer<T>? cmp = null) => _cmp = cmp ?? Comparer<T>.Default;
    public int Count => _h.Count;

    public void Push(T v)
    {
        _h.Add(v);
        for (int i = _h.Count - 1; i > 0;)
        {
            int p = (i - 1) / 2;
            if (_cmp.Compare(_h[i], _h[p]) >= 0) break;
            (_h[i], _h[p]) = (_h[p], _h[i]); i = p;
        }
    }

    public T Pop()
    {
        var top = _h[0];
        _h[0] = _h[^1]; _h.RemoveAt(_h.Count - 1);
        for (int i = 0; ;)
        {
            int l = 2*i + 1, r = 2*i + 2, s = i;
            if (l < _h.Count && _cmp.Compare(_h[l], _h[s]) < 0) s = l;
            if (r < _h.Count && _cmp.Compare(_h[r], _h[s]) < 0) s = r;
            if (s == i) break;
            (_h[i], _h[s]) = (_h[s], _h[i]); i = s;
        }
        return top;
    }
}
Step 5: Trie for autocomplete
public class Trie
{
    private class Node
    {
        public Dictionary<char, Node> Next = new();
        public bool IsWord;
    }
    private readonly Node _root = new();

    public void Insert(string s)
    {
        var n = _root;
        foreach (var c in s)
        {
            if (!n.Next.TryGetValue(c, out var nx)) n.Next[c] = nx = new Node();
            n = nx;
        }
        n.IsWord = true;
    }

    public IEnumerable<string> WithPrefix(string prefix)
    {
        var n = _root;
        foreach (var c in prefix)
            if (!n.Next.TryGetValue(c, out n!)) yield break;
        foreach (var w in Collect(n, prefix)) yield return w;
    }

    private static IEnumerable<string> Collect(Node n, string path)
    {
        if (n.IsWord) yield return path;
        foreach (var (c, child) in n.Next)
            foreach (var w in Collect(child, path + c)) yield return w;
    }
}
Step 6: Lowest common ancestor — the canonical interview problem
public static Node<T>? LCA<T>(Node<T>? root, T a, T b) where T : IComparable<T>
{
    var n = root;
    while (n is not null)
    {
        int ca = a.CompareTo(n.Value), cb = b.CompareTo(n.Value);
        if      (ca < 0 && cb < 0) n = n.Left;
        else if (ca > 0 && cb > 0) n = n.Right;
        else return n;     // values split → this is the LCA
    }
    return null;   // assumes both a and b are in the tree; otherwise the result is meaningless
}
How Trees Go Wrong
1. Plain BST in production. Sorted-input insertion degrades to O(n) per op. Always use a self-balancing tree (SortedDictionary, SortedSet, or implement red-black/AVL).
2. Recursive traversal on adversarial input. A skewed tree of 100k nodes blows the 1MB default stack. Use the iterative Stack<T> traversal for any tree built from untrusted data.
3. Hand-writing a B-tree in app code. B-trees started as a disk-page optimization, and they also help in RAM because each node is one contiguous array, which is why Rust's standard BTreeMap uses one. They are much harder to write correctly than to use, so take a library or let the database handle it.
4. SortedDictionary when you wanted Dictionary. If you don't need ordered iteration or range queries, a hash dictionary is dramatically faster. SortedDictionary trades O(1) lookup for O(log n) ordered operations.
5. PriorityQueue updates aren't supported. .NET's PriorityQueue has no "decrease-priority" operation. For Dijkstra/A*, the standard trick is to push the new entry and discard stale ones on dequeue (mark-as-visited).
6. Trie memory blowup. A trie with one node per character, each holding its own dictionary, gets large fast over millions of words. Measure it, and use compressed/radix tries (Patricia trie) or just put the dictionary in HashSet<string> if prefix queries aren't the bottleneck.
Which Tree I Would Pick
- Default to
SortedDictionary/SortedSet(red-black) andPriorityQueue(heap). Roll your own only when you need a custom invariant. - Use iterative traversal with
Stack<T>for trees built from untrusted input. - Heaps are O(log n) push/pop, O(1) peek. Use them for top-K, scheduling, Dijkstra/A*.
- Tries shine for prefix queries (autocomplete, IP routing). For pure membership use a hash set.
- Don't hand-write a B-tree. Use the database's, or a library one.
- For Dijkstra-style updates with PriorityQueue, push new entries and skip stale ones — don't try to mutate the heap.
- Always benchmark: red-black tree vs hash dictionary vs sorted array can swap places depending on n and access pattern.
Trees You Already Depend On
You rarely write a balanced tree yourself, but you depend on them all day, and knowing how they behave explains a lot of production performance.
A B-tree is the structure behind nearly every database index. Each node holds hundreds of keys, so a table with a billion rows needs only about four levels. That's why an indexed lookup takes a few page reads. It also explains the leftmost-prefix rule for composite indexes, and why inserting random UUIDs causes page splits, which is what makes UUIDv7 a better primary key.
LSM trees take a different approach. RocksDB, Cassandra and similar stores buffer writes in memory and flush sorted files, merging them in the background. Writes are fast, and reads may need to check several files, with Bloom filters to skip the ones that can't contain the key. If your workload is write-heavy, this is often why those stores win.
Merkle trees hash the data at the leaves and combine hashes upward. Git uses one for commits, and systems use them to find exactly what differs between two replicas without comparing everything. Comparing root hashes tells you immediately if two copies are the same.
Trees in AI systems
HNSW, an index used by many vector databases, is a layered graph rather than a tree, though it borrows the idea of narrowing down in stages. Tree-based models such as gradient-boosted trees remain a strong baseline for a lot of tabular data, and they're far cheaper than an LLM. Some tokenisers use a trie to find the longest match, and so do many software routers for longest-prefix match, which is why a route table with thousands of entries still resolves quickly.
Practical warnings
Trees built from sorted input can degrade into linked lists unless they rebalance, so be careful with a hand-rolled BST. Deep trees bring stack limits if you walk them recursively, so use an explicit stack for user-supplied data. In-memory, pointer-heavy trees also have poor cache locality. For read-heavy work, a sorted array with binary search often beats a tree in practice, even though the big-O looks the same. Measure before you build something clever, because most of the time the right tree is the one your standard library already provides.