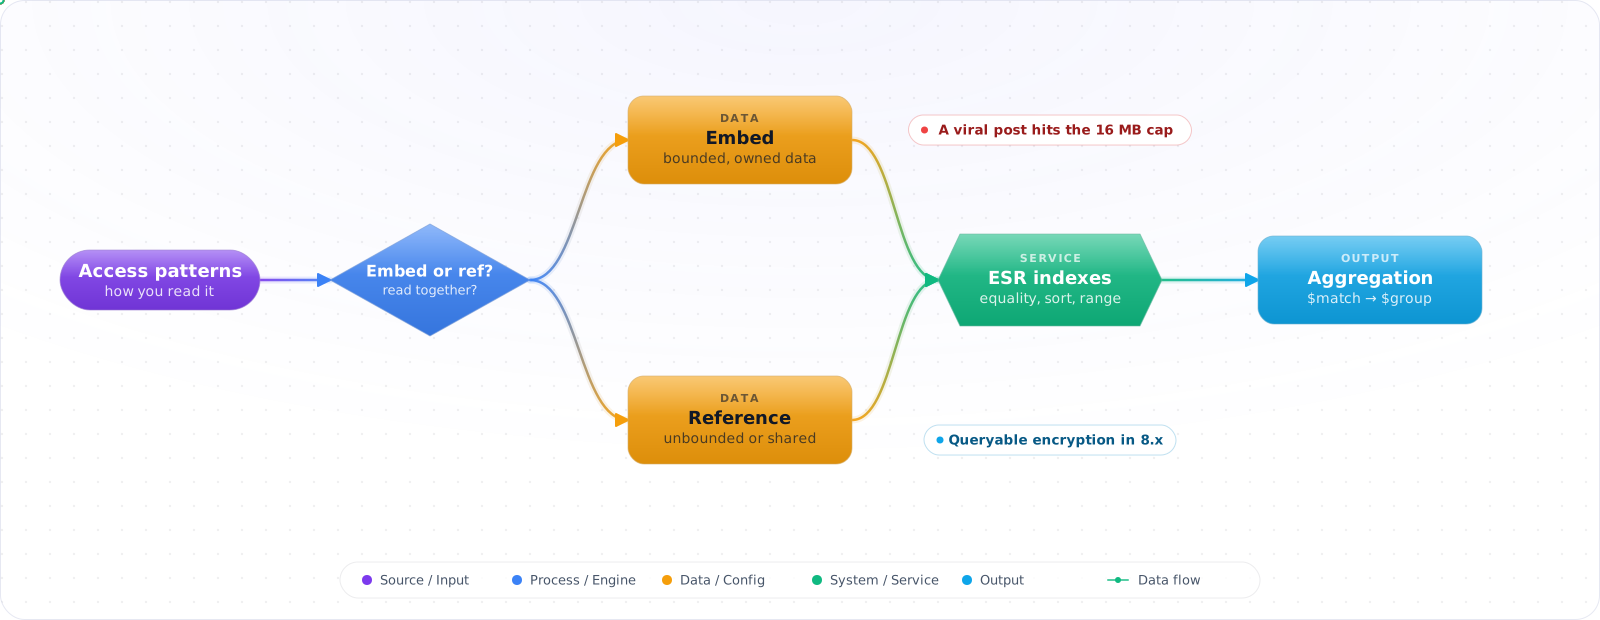
Start With What Fits the Data
If your data is read in many unrelated combinations, a relational database is the better fit, and you can stop here. MongoDB earns its place when records vary a lot in shape and are usually read whole, such as a product catalogue where each category has its own attributes.
MongoDB makes the first version easy: no migrations, just save the object. A year later the same collection has three spellings of the same field, a string where a number should be, and documents carrying ten thousand embedded reviews that make the most popular pages the slowest.
None of that is MongoDB’s fault. It is what happens when “schemaless” is taken literally. The database itself has kept improving, with version 8 adding range queries to Queryable Encryption. Below is how to model documents around the way they are read, when to embed and when to reference, and how to keep the data consistent with validation and the right indexes.
- You modeled deeply nested arrays and now updates are atomic-on-paper but expensive in practice
- You don't know when to embed and when to reference
- You learned
find()but never wrote an aggregation pipeline - You discovered that MongoDB has multi-document transactions but they're slow — and you're not sure why
Documents, Embedding and Indexes
MongoDB stores BSON documents (binary JSON with extra types — Date, Decimal128, ObjectId) inside collections. You can enforce a structure on inserts and updates with JSON Schema validators, which are optional but recommended. Two design decisions dominate:
- Embed vs reference — embed when read together and bounded; reference when entities have independent lifecycles or unbounded growth (a user's comments, an order's line items vs a product's reviews).
- Indexes — same B-tree story as SQL, plus compound, partial, TTL, text, geospatial, and wildcard indexes. Atlas Search adds a Lucene index alongside.
flowchart LR
    M["$match<br/>(filter early)"] --> P["$project<br/>(reshape)"]
    P --> L["$lookup<br/>(left join)"]
    L --> G["$group<br/>(aggregate)"]
    G --> S["$sort + $limit<br/>(top N)"]
    S --> O["$out / $merge<br/>(materialize)"]

    style M fill:#0078D4,color:#fff,stroke:#005a9e
    style O fill:#16a34a,color:#fff,stroke:#15803d
Modelling and Querying a Real Collection
Step 1: Connect from C# (MongoDB.Driver 3.x)
// MongoDB.Driver 3.x. By default, a property is stored under its C# name, such as Status.
var client = new MongoClient(connStr);
var db     = client.GetDatabase("shop");
var orders = db.GetCollection<Order>("orders");

public class Order
{
    [BsonId] public ObjectId Id { get; set; }
    public string CustomerId { get; set; } = "";
    public List<LineItem> Items { get; set; } = new();
    public decimal TotalCents { get; set; }
    public string Status { get; set; } = "open";
    public DateTime CreatedAt { get; set; }
}
Step 2: Embed bounded children, reference unbounded ones
// GOOD: order has a small, bounded list of line items → embed
var order = new Order {
    CustomerId = "c1",
    Items = new() {
        new LineItem { Sku = "ABC", Qty = 2, PriceCents = 999 }
    },
    TotalCents = 1998,
    CreatedAt  = DateTime.UtcNow
};
await orders.InsertOneAsync(order);

// BAD: a user's comments are unbounded → reference instead
// Store { _id, userId, postId, body } in its own 'comments' collection
// and index on postId.Check it: For each array in a document, ask what its largest realistic size is. If the honest answer is that it has no limit, it should be a separate collection.
Step 3: Indexes for your actual queries
// Compound index — order matters! Equality, then sort, then range.
await orders.Indexes.CreateOneAsync(
    new CreateIndexModel<Order>(
        Builders<Order>.IndexKeys
            .Ascending(o => o.CustomerId)
            .Descending(o => o.CreatedAt)));

// Partial index — only the rows you filter on
await orders.Indexes.CreateOneAsync(
    new CreateIndexModel<Order>(
        Builders<Order>.IndexKeys.Ascending(o => o.Status),
        new CreateIndexOptions<Order> {
            PartialFilterExpression = Builders<Order>.Filter.Eq(o => o.Status, "open")
        }));

// TTL index — auto-delete sessions after 24h
await sessions.Indexes.CreateOneAsync(
    new CreateIndexModel<Session>(
        Builders<Session>.IndexKeys.Ascending(s => s.CreatedAt),
new CreateIndexOptions { ExpireAfter = TimeSpan.FromHours(24) }));Check it: Run explain with execution statistics on your most frequent query. The documents examined should be close to the documents returned. A COLLSCAN means there's no usable index.
Step 4: Aggregation pipeline (the real query language)
// Top 5 customers by spend in the last 30 days
var since = DateTime.UtcNow.AddDays(-30);

var top = await orders.Aggregate()
    .Match(o => o.CreatedAt >= since)
    .Group(
        o => o.CustomerId,
        g => new { CustomerId = g.Key,
                   Spend = g.Sum(o => o.TotalCents),
                   Orders = g.Count() })
    .SortByDescending(x => x.Spend)
    .Limit(5)
.ToListAsync();Check it: Move the $match stage to the start of a pipeline and compare the time. Filtering first means every later stage handles fewer documents.
Step 5: Atomic updates (no transactions needed)
// Atomic: increment quantity if SKU exists in array
var filter  = Builders<Order>.Filter.And(
    Builders<Order>.Filter.Eq(o => o.Id, orderId),
    Builders<Order>.Filter.Eq("Items.Sku", "ABC"));
var update = Builders<Order>.Update.Inc("Items.$.Qty", 1);
await orders.UpdateOneAsync(filter, update);

// findOneAndUpdate for read-modify-write in one round trip
var updated = await orders.FindOneAndUpdateAsync(
    o => o.Id == orderId,
    Builders<Order>.Update.Set(o => o.Status, "shipped"),
    new FindOneAndUpdateOptions<Order> {
        ReturnDocument = ReturnDocument.After
});Check it: Run the same increment from two clients at once, many times over. The final count should be exact, with no transaction involved.
Step 6: Multi-document transactions (only when you must)
using var session = await client.StartSessionAsync();
session.StartTransaction();
try
{
    await orders.UpdateOneAsync(session, o => o.Id == oid,
        Builders<Order>.Update.Set(o => o.Status, "paid"));
    await ledger.InsertOneAsync(session, new Ledger { OrderId = oid });
    await session.CommitTransactionAsync();
}
catch
{
    await session.AbortTransactionAsync();
    throw;
}
// Transactions need a replica set and add overhead. Most "transactional" needs in
// MongoDB are solved by remodeling so the atom is one document.
Mistakes That Hurt Later
- Modeling like SQL. Three normalized collections joined with
$lookupon every read = slow MongoDB and an unhappy team. Either embed or pick a relational engine. - Unbounded arrays. Embedding a comments array on a viral post hits the 16 MB document cap and rewrites the entire doc on every push. Reference instead.
- Missing indexes. Default queries do a COLLSCAN. Run
db.coll.find(...).explain("executionStats")and add covering compound indexes. - Wrong write concern. Default
w:majorityis durable but slower.w:1can lose data on primary failure. Pick deliberately per workload. - Read-your-write surprise. Reading from a secondary right after a primary write can return stale data. Use
readPreference=primary, or a causally consistent session with majority read and write concerns, when you need read-your-write. - Schema drift. Without a JSON Schema validator, fields silently morph types across releases. Add validators and migrate explicitly.
Try It on Your Own System This Week
Three checks on a MongoDB collection you already run, about an hour in total:
- Find your largest document. Check how close it is to the 16 MB limit, and which array is making it grow.
- Sample a hundred documents from one collection. Count the distinct shapes. More than you expected means you need a validator.
- Count your multi-document transactions. If most writes need one, the model is fighting the database.
How I Would Use It
- Document modeling is a design skill: embed when read together and bounded; reference otherwise.
- Atomic single-document updates are MongoDB's superpower — use
$inc,$push, positional$, andfindOneAndUpdate. - Aggregation pipelines are the real query language. Filter (
$match) early, project late. - Compound indexes follow ESR: Equality, Sort, Range — in that order.
- Multi-document transactions exist but add overhead; remodel to a single document if you can.
- Use Atlas Search when you need full-text or vector search instead of bolting on Elasticsearch.
- Run
explain()on every important query before you ship it.
Modelling Decisions That Age Well
Flexible schema is a feature for your first month, and a liability for your third year, unless you enforce some structure. MongoDB supports JSON Schema validation on collections, and I'd turn it on from day one. Start with validationLevel: "moderate" and validationAction: "warn" on an existing collection, watch the logs, and tighten it once the data is clean.
Keep a schemaVersion field on documents as well. When the shape changes, your code can read both versions and upgrade documents lazily, or a background job can migrate them. Without this, you end up with code full of if (doc.foo) guards for shapes nobody remembers.
Embed or reference?
The rule I use: embed what you always read together and what's bounded in size, and reference what's unbounded or shared. Order lines belong inside an order. Comments on a popular post don't, because a document has a 16 MB limit, and rewriting a large document on every new comment gets slow long before that. Watch for arrays that grow forever. They're the most common modelling mistake in MongoDB, and the fix gets harder the longer you wait.
Indexes and the ESR rule
Compound indexes should follow Equality, Sort, Range order: fields you match exactly go first, then the sort field, then range filters. Getting this wrong is why a query with an index can still sort in memory. Use explain("executionStats"), and compare totalDocsExamined with nReturned. If you examine 50,000 documents to return 20, the index isn't doing its job.
Transactions and write concern
Multi-document transactions exist, and if you need them all the time, your model may be wrong, because a single-document write is already atomic. Check your write concern as well. w: "majority" protects against losing a write on failover. Use readConcern: "majority" if you need to read only durable data.
Vector search
MongoDB Atlas offers vector search alongside your documents, which removes a sync job if your data already lives there. It's a similar trade-off to pgvector: convenient and consistent, though with less tuning than a dedicated engine. Measure recall on your own data before you decide. If you're starting fresh and your data is relational, ask whether you need MongoDB at all, since Postgres with jsonb covers a lot of the same ground.