

The Decisions You Live With for Years
Schemas outlive the code around them. The framework gets replaced, the team changes, and the tables are still there, holding years of data. A shortcut taken in week one, such as an order line that points at the live product price, can quietly rewrite last year’s receipts when a sale starts.
Good schema design is mostly about recording what actually happened, letting the database reject bad data, and indexing for the queries you know you will run. Below is how to approach it for a real product, including money, history and constraints, and how to leave room for the features you do not know about yet.
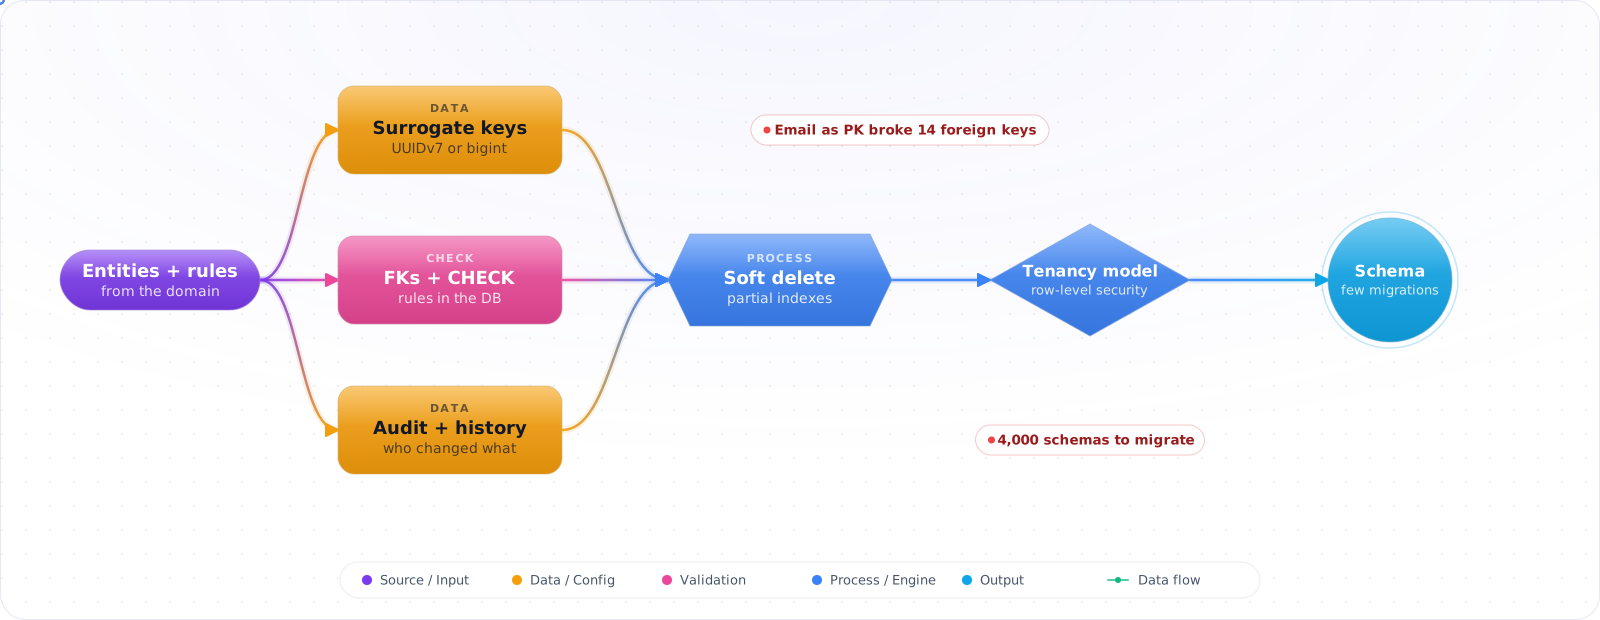
- You used
emailas the primary key and now you can't change it without breaking 14 foreign keys - You added
is_deletedto one table and forgot it on the joined ones - You can't answer "who changed this row and when?" without grep
- You picked schema-per-tenant and now have 4,000 schemas to migrate
Modelling Entities, Events and Rules
Schema design boils down to four decisions you make per table:
- Keys — surrogate (auto-generated, opaque) vs natural (meaningful but mutable). Surrogate wins by default.
- Relationships — 1:1, 1:N, N:N (junction table), polymorphic (avoid).
- Audit — created_at / updated_at / created_by / updated_by + history table or temporal range.
- Tenancy — shared schema (
tenant_idcolumn), schema-per-tenant, or database-per-tenant.
flowchart LR
    R["Requirements"] --> E["Entities & relationships"]
    E --> K["Keys<br/>(surrogate UUIDv7 / bigint)"]
    K --> N["Normalize 3NF"]
    N --> D["Denormalize for hot reads"]
    D --> A["Audit + soft-delete + tenancy"]
    A --> M["Migration plan<br/>(forward + backward)"]

    style E fill:#0078D4,color:#fff,stroke:#005a9e
    style M fill:#16a34a,color:#fff,stroke:#15803d
Designing a Real Schema
Step 1: Surrogate keys with UUIDv7 (or bigint identity)
-- UUIDv7 is time-ordered (Dec 2024 RFC) — index-friendly, globally unique
CREATE TABLE customers (
    id          uuid PRIMARY KEY DEFAULT uuidv7(),
    email       citext NOT NULL UNIQUE,
    display_name text  NOT NULL,
    created_at  timestamptz NOT NULL DEFAULT now(),
    updated_at  timestamptz NOT NULL DEFAULT now()
);
-- bigint IDENTITY is fine when you don't need globally-unique IDs.
-- Avoid email/username/SKU as PK: they change.
Step 2: Foreign keys are not optional
CREATE TABLE orders (
    id          uuid PRIMARY KEY DEFAULT uuidv7(),
    tenant_id   uuid NOT NULL,
    customer_id uuid NOT NULL REFERENCES customers(id) ON DELETE RESTRICT,
    status      text NOT NULL CHECK (status IN ('pending','paid','shipped','cancelled')),
    total_cents bigint NOT NULL CHECK (total_cents >= 0),
    created_at  timestamptz NOT NULL DEFAULT now(),
    updated_at  timestamptz NOT NULL DEFAULT now()
);
CREATE INDEX idx_orders_tenant_customer ON orders (tenant_id, customer_id);
CREATE INDEX idx_orders_tenant_status   ON orders (tenant_id, status);
-- ON DELETE: RESTRICT (default), CASCADE (sparingly), SET NULL (only when intentional)
Step 3: Audit columns + history table
-- Trigger that bumps updated_at and writes a history row
CREATE OR REPLACE FUNCTION track_history() RETURNS trigger AS $$
BEGIN
    NEW.updated_at := now();
    INSERT INTO orders_history(order_id, snapshot, changed_at, changed_by)
    VALUES (NEW.id, to_jsonb(NEW), now(), current_setting('app.user_id', true));
    RETURN NEW;
END $$ LANGUAGE plpgsql;

CREATE TRIGGER trg_orders_history
BEFORE UPDATE ON orders
FOR EACH ROW EXECUTE FUNCTION track_history();
Step 4: Soft delete (only where you need history)
ALTER TABLE customers ADD COLUMN deleted_at timestamptz;

-- Partial index keeps queries on live rows fast
CREATE UNIQUE INDEX idx_customers_email_live
ON customers (lower(email))
WHERE deleted_at IS NULL;

-- A view enforces the filter so devs don't forget
CREATE VIEW v_customers AS
SELECT * FROM customers WHERE deleted_at IS NULL;
Step 5: Multi-tenancy — pick one and stick with it
-- Pattern A (most common): shared schema with tenant_id everywhere
-- Pros: simple ops, easy joins, cheap. Cons: noisy-neighbor, harder per-tenant restore.

-- Use Postgres Row-Level Security to enforce isolation in DB, not just app
ALTER TABLE orders ENABLE ROW LEVEL SECURITY;
CREATE POLICY tenant_isolation ON orders
    USING (tenant_id = current_setting('app.tenant_id')::uuid);

-- Pattern B: schema-per-tenant — strong isolation, painful migrations > 100 tenants
-- Pattern C: database-per-tenant — best isolation, highest cost. Reserve for regulated tiers.
Step 6: Many-to-many through a junction table (with metadata)
CREATE TABLE order_tags (
    order_id  uuid NOT NULL REFERENCES orders(id) ON DELETE CASCADE,
    tag_id    uuid NOT NULL REFERENCES tags(id)   ON DELETE CASCADE,
    added_at  timestamptz NOT NULL DEFAULT now(),
    added_by  uuid NOT NULL,
    PRIMARY KEY (order_id, tag_id)
);
CREATE INDEX idx_order_tags_tag ON order_tags (tag_id);
-- Composite PK = natural unique constraint + the index you'd add anyway.
Changing the Schema While the App Is Running
A schema is easy to design and hard to change, because the moment it ships, running code depends on it. Renamingcustomers.phone to phone_number in one migration breaks every instance still running the old code during a rolling deploy. The safe pattern is expand and contract, spread over several deploys:
- Expand: add the new column, nullable, with no rewrite of existing rows.
- Dual write: deploy code that writes both columns and still reads the old one.
- Backfill: copy old values into the new column in small batches, not one giant
UPDATE. - Switch reads: deploy code that reads the new column.
- Contract: stop writing the old column, then drop it in a later release.
In Postgres, a few details decide whether each step takes milliseconds or locks the table:
SET lock_timeout = '3s';   -- fail fast instead of queueing every query behind the DDL

-- Adding a column with a constant default is metadata-only (Postgres 11+), no table rewrite
ALTER TABLE customers ADD COLUMN phone_number text;

-- Indexes on a live table: build without blocking writes
CREATE INDEX CONCURRENTLY idx_customers_phone_number ON customers (phone_number);

-- NOT NULL on a big table: check new rows now, validate old rows without a long lock
ALTER TABLE customers ADD CONSTRAINT phone_number_present
  CHECK (phone_number IS NOT NULL) NOT VALID;
ALTER TABLE customers VALIDATE CONSTRAINT phone_number_present;
The lock_timeout line matters more than it looks. An ALTER TABLE waiting for a lock blocks every query that arrives after it, so a migration stuck behind one long-running report can take the whole application down. A short timeout makes the migration fail instead, and you retry it at a quieter moment.
Status Values: CHECK, Enum Type or Lookup Table
Once a set of booleans becomes a status column, you still have to decide how to restrict its values. Three options, each with a different cost of change:
- A text column with a CHECK constraint. Easy to read, and changing the allowed values is a quick constraint swap. My default for most status fields.
- A Postgres enum type. Compact and self-documenting, and adding a value is simple. Removing or renaming a value is not: it means creating a new type and migrating every column that uses it. Use it for sets you are confident will only grow.
- A lookup table with a foreign key. Right when values carry their own data (a display label, a sort order, whether the status counts as open) or when administrators manage them without a deploy.
Mistakes That Become Migrations
- Natural primary keys. Email, SKU, ISBN — they all change. Use a surrogate, put a unique constraint on the natural key, and keep your options open.
- Polymorphic associations.
commentable_type + commentable_idcan't be a foreign key. Either model the relationships explicitly (post_comments,video_comments) or accept the integrity loss with eyes open. - EAV (entity-attribute-value)."User-defined fields" in a key/value table is the classic anti-pattern. Use JSONB columns instead — typed, indexable, and faster.
- Booleans where enums belong.
is_active,is_archived,is_pending— three booleans collapse into onestatuscolumn with a CHECK constraint and you stop having impossible states. - No
tenant_idon indexes. Every multi-tenant index should start withtenant_id. Otherwise you scan the world to find one tenant's rows. - Soft delete everywhere. Soft delete adds a
WHERE deleted_at IS NULLtax to every query. Use it where you genuinely need recovery / audit; otherwise hard-delete and rely on backups.
How I Would Start
- Surrogate keys (UUIDv7 or bigint) by default, with unique constraints on natural keys.
- Foreign keys + CHECK constraints + NOT NULL — let the DB enforce what you can't see in code reviews.
- Every table gets
created_at,updated_at, and a tenant column where applicable. - Pick one tenancy pattern per system. Mixing them is operational debt.
- Use Row-Level Security as a defense-in-depth on tenant_id, not as your only line.
- Avoid polymorphic associations and EAV. Use JSONB for genuinely flexible fields.
- Treat schema migrations as code: forward + backward + tested in CI.