Start Without One
A new system doesn't need a cache. The database answers every read with room to spare, and a cache added at this point is one more copy of the data to keep correct, with nothing to show for it. That changes as people arrive. The code is the same, but the same few queries now run thousands of times, and the database spends most of its day answering questions it has already answered.
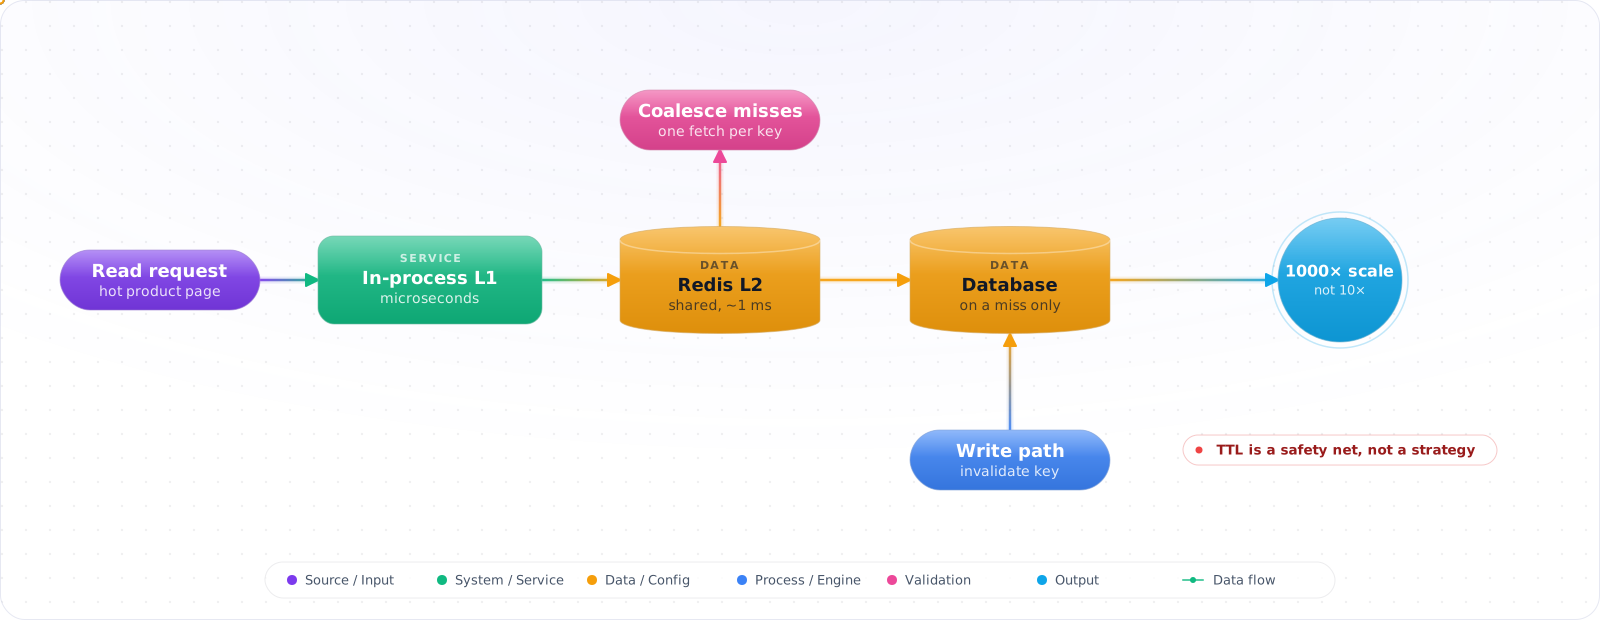
So caching isn't one decision. It's a series of small ones, each made when a specific signal shows up: reads outgrow the database, users see an old value, one popular entry expires at the worst moment. The table above lists those signals in the order a growing system meets them. This article builds the answer to each one, and tells you how to check it worked.
- You added Redis "to make it faster" without measuring what to cache
- Your cache and your DB disagree and nobody knows who's right
- Your Redis went down and the DB followed five minutes later
- You can't explain the difference between cache-aside, write-through, and write-behind
This is the caching mental model that survives a real incident — placement, strategies, invalidation, and the common classes of cache failure.
Where a Cache Can Sit
Caches live at five layers, and the cheapest cache is the one closest to the user:
- Browser / CDN edge — milliseconds. Best for immutable assets and short-TTL HTML.
- Reverse proxy (nginx, Front Door) — milliseconds. Cache full HTTP responses keyed by URL + Vary headers.
- Application memory (in-process LRU, MemoryCache) — the fastest layer. No network hop, but doesn't survive restarts and isn't shared.
- Distributed cache (Redis, Memcached) — one network round trip. Shared across instances, and it outlives your app restarts. Whether it survives its own restart depends on configuration (Redis persistence, Memcached warm restart), so your app still has to tolerate losing it.
- Database query/result cache — last resort. The DB already has buffer pools; reach for this only when you can't move logic.
flowchart LR
    U["User"] --> CDN["CDN / Edge<br/>cache: assets, HTML"]
    CDN --> LB["Reverse Proxy<br/>cache: GET /api/popular"]
    LB --> APP["App<br/>L1: in-process LRU"]
    APP -->|miss| R["Redis<br/>L2: shared cache"]
    R -->|miss| DB["Database<br/>buffer pool"]

    DB -.->|fill| R
    R -.->|fill| APP

    style R fill:#dc2626,color:#fff,stroke:#b91c1c
    style DB fill:#0078D4,color:#fff,stroke:#005a9e
The Steps, One Signal at a Time
Each step answers one row of the table above, and fixes one thing the step before it left broken. The examples follow one system: the product page of an online store whose traffic keeps growing. Stop at the step your own system has reached. You can come back for the next one when its signal appears.
Step 1: When the same read keeps hitting the database, use cache-aside
Start with the simplest thing that takes reads off the database. The app looks in the cache first, and only on a miss does it read the database and store the result. The database stays the source of truth, and if the cache is empty the app still works.
// Cache-aside (lazy-loading): app owns the cache; DB is the source of truth.
public async Task<Product?> GetProductAsync(int id)
{
    var key = $"product:{id}";
    var cached = await cache.GetStringAsync(key);
    if (cached is not null)
        return JsonSerializer.Deserialize<Product>(cached);

    var product = await db.Products.FindAsync(id);
    if (product is not null)
    {
        await cache.SetStringAsync(key, JsonSerializer.Serialize(product),
            new DistributedCacheEntryOptions { AbsoluteExpirationRelativeToNow = TimeSpan.FromMinutes(10) });
    }
    return product;
}
The other strategies in one paragraph each: Write-through writes to cache + DB synchronously — fresher reads, slower writes. Write-behind writes to cache, async-flushes to DB — fastest writes, risk of data loss on crash. Read-through hides the cache from app code behind a loader — clean abstraction but you give up control over what gets cached.
Check it: Redis counts this for you. INFO stats returns keyspace_hits and keyspace_misses, and the hit rate is hits divided by hits plus misses. In the store example, a 95% hit rate turns 12,000 reads a second into about 600 database reads. What's still broken: change a price and the old one is served for up to ten minutes. That's Step 2.
Step 2: When users see old values after an update, invalidate on write
The cache doesn't know the price changed. The code that changes the price does, so that code has to remove the cached copy, along with every other cached value built from it.
public async Task UpdatePriceAsync(int productId, int categoryId, decimal newPrice)
{
    await db.Products.Where(p => p.Id == productId)
        .ExecuteUpdateAsync(s => s.SetProperty(p => p.Price, newPrice));

    // Invalidate every key that depended on this product
    await cache.RemoveAsync($"product:{productId}");
    await cache.RemoveAsync($"category:{categoryId}:top10"); // derived view
}
TTL is your safety net, not your invalidation strategy. Use tag-based invalidation (RemoveByTagAsync in HybridCache) when one write should bust many keys. It doesn't clear L1 on other servers, so keep the local expiry short.
Check it: Update a price, then read the product straight away. You should get the new price on the first read. If the old price hangs on until the TTL runs out, some write path isn't invalidating. Search the codebase for every place that writes the table, not only the one you just fixed: admin tools, imports and background jobs are the usual misses.
Step 3: When an invalidation gets missed, let the expiry time catch it
Invalidation will miss a write one day. The TTL decides how long that mistake stays visible, so set it by how wrong the data is allowed to be, not by one number for everything.
Volatile data (prices, stock):       30s – 2 min
Profile / catalog (semi-static):     5 – 30 min
Reference data (zip codes, lookups): hours – days  (or refresh on deploy)

Add 10–20% jitter to TTLs to avoid synchronized expiration ("herd").
The jitter matters more than it looks. Entries cached in the same second with the same TTL also expire in the same second, and the database gets all of those misses at once.
Step 4: When every read still crosses the network, add an in-process layer
Every read now costs a network round trip to Redis, and Redis has become something the site can't run without. A small in-process cache in front of it removes the hop for the hottest products. Its short expiry puts a limit on how stale those can get.
// Program.cs — single API for L1 (in-memory) + L2 (Redis), with stampede protection
builder.Services.AddStackExchangeRedisCache(o =>
    o.Configuration = builder.Configuration.GetConnectionString("Redis"));

builder.Services.AddHybridCache(options =>
{
    options.DefaultEntryOptions = new HybridCacheEntryOptions
    {
        Expiration      = TimeSpan.FromMinutes(10),  // L2 (Redis) absolute
        LocalCacheExpiration = TimeSpan.FromMinutes(1) // L1 (in-process)
    };
});

// Usage — single GetOrCreateAsync; HybridCache deduplicates concurrent misses
public ValueTask<Product?> GetAsync(int id, CancellationToken ct) =>
    cache.GetOrCreateAsync(
        key: $"product:{id}",
        factory: async ct => await db.Products.FindAsync([id], ct),
cancellationToken: ct);Check it: Read the same product twice within a minute and watch the commands arriving at Redis (MONITOR in a test environment). The second read shouldn't reach Redis at all. Then accept what you just bought: after a price change, another server can keep serving its local copy for up to a minute. If that's too long for prices, shorten the local expiry for that entry.
Step 5: When a popular entry expires at peak, let one request reload it
The sale's featured product is the hottest key in the system. When its entry expires at peak, every request in flight misses at the same moment and they all run the same query. The fix is to let one request reload the value while the others wait for it.
// Without coalescing, 1000 concurrent requests on a cold key → 1000 DB queries.
// HybridCache coalesces per instance, not across servers. Manual pattern with SemaphoreSlim:
private static readonly ConcurrentDictionary<string, SemaphoreSlim> _locks = new();

public async Task<T> GetOrLoadAsync<T>(string key, Func<Task<T>> loader)
{
    if (await TryGet<T>(key) is { } hit) return hit;

    var sem = _locks.GetOrAdd(key, _ => new SemaphoreSlim(1, 1));
    await sem.WaitAsync();
    try
    {
        if (await TryGet<T>(key) is { } afterWait) return afterWait;  // double-check
        var value = await loader();
        await Set(key, value);
        return value;
    }
    finally
    {
        sem.Release();
    }
}Check it: In a load test, delete a hot key and send a few hundred concurrent requests for it. Count the database queries. You want one per app instance, not one per request. Early refresh (reload at 80% of the TTL, not at 100%) and the jitter from Step 3 make the same burst less likely in the first place.
Step 6: When the response is the same for everyone, cache it over HTTP
The cheapest read is the one that never reaches your servers. For responses that are the same for every user, let the browser and the CDN keep a copy.
Cache-Control: public, max-age=300, stale-while-revalidate=60
ETag: "v=42"
Vary: Accept-Encoding, Accept-Language

# stale-while-revalidate lets the CDN serve stale for 60s while it
# refetches in the background, if the CDN supports the directive (RFC 5861).Check it: Run curl -I against the endpoint and read the headers that actually come back. A proxy or a framework default often rewrites what you set. Send the request again with If-None-Match and the ETag value, and you should get a 304 with no body.
How Caches Go Wrong
The steps above already dealt with the two most common failures: stale data after a write (Step 2) and the stampede on a hot key (Step 5). These are the four that still catch teams afterwards.
1. Cache penetration — the "not found" flood. A bot probes for non-existent product IDs; every request misses, every request hits DB. Cache the negative result with a short TTL (cache.Set(key, null, 30s)) or use a Bloom filter.
2. The cache is now load-bearing. When Redis goes down, the DB takes the full traffic and can fall over. Add a circuit breaker and an L1 in-process cache so a Redis outage degrades, doesn't cascade.
3. Caching personalised data behind a shared key. GET /api/recommendations served from a CDN with Cache-Control: public and noVary: Authorization ships user A's recs to user B. Either don't cache, or include the user id in the key.
4. Keys without a versioning strategy. You change the shape of the cached object and old entries deserialize to null / crash. Prefix keys with a schema version (product:v2:42) and bump on shape changes.
What I Would Cache First
- Default to cache-aside. Switch only when you have a specific reason.
- L1 (in-memory) + L2 (Redis) via HybridCache is a good .NET default — one API, with stampede protection per instance.
- Invalidate on the write path. TTL is the safety net, not the strategy.
- Add jitter to TTLs (10–20%) to avoid synchronized expiration.
- Cache the "not found" result with a short TTL to defeat penetration probes.
- Always have a fallback for the cache being down — circuit breaker + in-memory L1.
- Version your keys. The day you change the DTO shape you'll be glad you did.
Try It on Your Own System This Week
You don't need the whole design to get value from it. Three checks, about an hour in total:
- Find your most-run read query. Your database's query statistics will show it. If the data behind it changes far less often than it's read, that's your first cache-aside candidate.
- Measure the hit rate you already have. If you run Redis, read
keyspace_hitsandkeyspace_missesfromINFO stats. A low number usually means TTLs are too short or the keys carry something that changes on every request. - List every write path for one cached entity. For each one, find the line that invalidates the cache. The path without that line is where your next stale-data bug will come from.
Caching for LLM Applications
LLM apps have several cache layers, and each has different trade-offs.
Provider prompt caching is the first to turn on. It reuses the processed prefix of your prompt, so cached input costs a fraction of the normal price, and it's safe, since the model still generates a fresh answer. Your only job is to keep the prefix stable. On Claude Sonnet 5.5, a read costs $0.10 per million tokens, against $2 for fresh input.
Exact-match response caching stores the full answer for an identical request. It's completely safe for deterministic, non-personal requests, and it often catches more than you'd expect, such as repeated evals and popular questions.
Semantic caching matches similar questions, and it's the risky one. "Cancel my order" and "don't cancel my order" can look alike to an embedding. Set a conservative threshold, include the user or tenant in the key, and avoid it for anything personalised. Measure false hits, not only hit rate.
Tool results are worth caching within a session too, as agents often repeat the same lookup. Set a short TTL, and don't cache anything with side effects. Keep tenants apart in every cache key: a cache that serves one customer's answer to another is a data breach.