


Problem Context
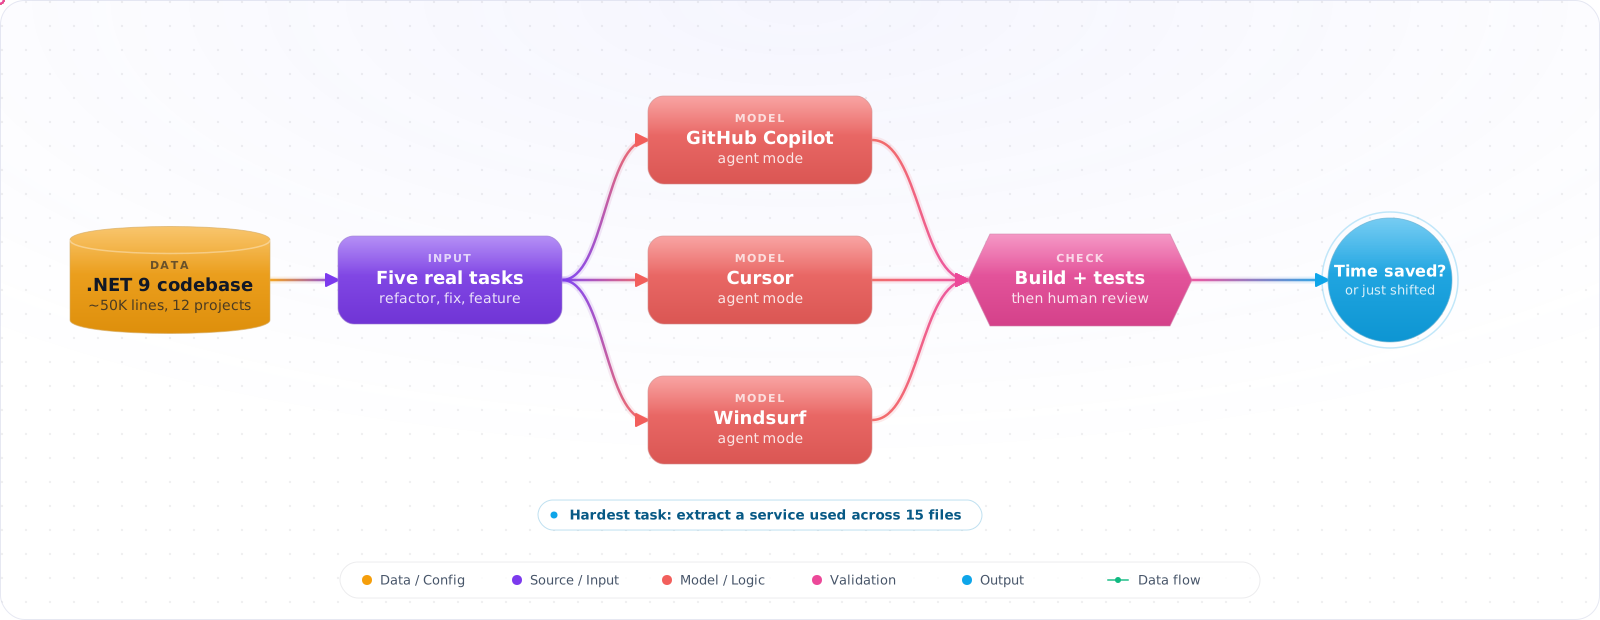
Autonomous coding agents promise to go beyond autocomplete — they can read your codebase, plan multi-step changes, run tests, and iterate. GitHub Copilot, Cursor, Claude Code, Gemini CLI, and others all claim to handle complex engineering tasks end-to-end. But how well do they actually work on real projects?
Marketing demos show agents building todo apps from scratch. Real engineering is different: you're refactoring a service with 200 files, fixing a race condition in async code, or adding a feature that touches five layers of your architecture. This experiment tests agents on those real tasks.
- You've tried AI coding agents but aren't sure if they're genuinely saving time or just shifting the work
- Your team is debating which tool to standardize on, and opinions are based on vibes, not data
- You want to know which types of tasks agents handle well and where they waste time
- You're interested in AI agents but don't trust the vendor benchmarks
This article shows how to compare agents on five realistic engineering tasks. The tables use anonymised, illustrative numbers to show the format. They are not a benchmark of any product. What matters is the method, and what works and what doesn't.
Concept Explanation
Autonomous coding agents work in a loop: read context → plan changes → edit files → run verification → iterate if needed. The quality of each step matters, but the critical differentiator is context gathering — how well the agent understands your codebase before it starts writing code.
      flowchart LR
          A["User Task"] --> B["Context Gathering\n(read files, search)"]
          B --> C["Plan\n(multi-step strategy)"]
          C --> D["Edit Files\n(code changes)"]
          D --> E["Verify\n(run tests, check errors)"]
          E -->|"Failures"| C
          E -->|"Success"| F["Complete"]

          style A fill:#4f46e5,color:#fff,stroke:#4338ca
          style B fill:#dc2626,color:#fff,stroke:#b91c1c
          style C fill:#059669,color:#fff,stroke:#047857
          style E fill:#7c3aed,color:#fff,stroke:#6d28d9
Experiment Setup
Five tasks on an example .NET web application (PostgreSQL + Redis):
- Multi-file refactoring: Extract a service class used across 15 files into a separate project
- Bug fix: Race condition in a distributed cache invalidation handler
- Feature implementation: Add pagination with cursor-based navigation to an existing API endpoint
- Test generation: Generate integration tests for an existing payment processing service
- Migration: Upgrade from
HttpClientdirect usage toIHttpClientFactorypattern across the solution
Implementation
Task 1: Multi-File Refactoring (Illustrative)
Extracting NotificationService into its own project with proper dependency updates across 15 consuming files.
Agent               | Completed? | Files Correct | Time   | Manual Fixes
--------------------|------------|---------------|--------|-------------
Agent A             | Yes        | 14/15         | 6 min  | 1 csproj reference fix
Agent B             | Yes        | 15/15         | 8 min  | 1 namespace adjustment
Agent C             | Yes        | 15/15         | 7 min  | None
Agent D             | Partial    | 13/15         | 5 min  | 2 files missed DI registration
What to look for: Whether the agent handled the full refactoring, including project files. Agents can still miss downstream project references.
Task 2: Race Condition Bug Fix
A distributed cache invalidation handler could process stale data when two updates arrived out of order.
Agent               | Found Bug? | Fix Correct? | Time   | Notes
--------------------|------------|--------------|--------|------
Agent A             | Yes        | Yes          | 4 min  | Used optimistic concurrency correctly
Agent B             | Yes        | Yes          | 5 min  | Implemented version check with retry
Agent C             | Yes        | Yes          | 3 min  | Cleanest fix, added test coverage
Agent D             | Yes        | Mostly       | 4 min  | Used lock instead of version check
Task 3: Cursor-Based Pagination
// What the agent needed to produce:
      // 1. Add cursor parameter to controller
      // 2. Implement cursor encoding/decoding
      // 3. Modify repository query to use cursor
      // 4. Add pagination metadata to response
      // 5. Update OpenAPI documentation

      // Implementations can all work and still differ in quality.
      // Check edge cases, such as paging in both directions:

      // A response shape that covers them:
      public record PagedResponse<T>(
          IReadOnlyList<T> Items,
          string? NextCursor,
          string? PreviousCursor,
          bool HasMore);
Task 4: Test Generation Quality
Agent               | Tests Generated | Pass Rate | Coverage Added | Meaningful?
--------------------|-----------------|-----------|----------------|------------
Agent A             | 14              | 13/14     | +22%           | 11/14 tested real behavior
Agent B             | 16              | 14/16     | +25%           | 13/16 tested real behavior
Agent C             | 18              | 17/18     | +28%           | 16/18 tested real behavior
Agent D             | 12              | 11/12     | +18%           | 9/12 tested real behavior
Task 5: HttpClient Migration
Agent               | Files Modified | Correct? | DI Registration | Time
--------------------|---------------|----------|-----------------|------
Agent A             | 11/11         | Yes      | Correct         | 7 min
Agent B             | 11/11         | Yes      | Correct         | 9 min
Agent C             | 11/11         | Yes      | Correct         | 6 min
Agent D             | 10/11         | Mostly   | Correct         | 5 min
Pitfalls
1. Trusting agent output without verification
Agents can produce code that compiles but is subtly wrong. Always run tests, review changes, and verify behavior. Agents are junior developers with perfect syntax and questionable judgment.
2. Starting with vague prompts
"Refactor the notification service" produces mediocre results. "Extract NotificationService into a new Contoso.Notifications project, update all 15 references, register in DI, and ensure existing tests pass" gives the agent far more to work with. Be specific.
3. Not pointing the agent to relevant files
Agents explore your codebase, but they don't always find the right files. Explicitly mentioning key files ("See PaymentProcessor.cs and its interface IPaymentProcessor.cs") helps it start in the right place.
4. Using agents for tasks that need design decisions
Agents execute well on clearly specified tasks. They're poor at making architectural decisions — "should this be an event or a direct call?" Make the design decisions yourself, then let the agent implement.
Running Your Own Evaluation
Published comparisons of coding agents age within months, and they rarely resemble your repository. The numbers in this article are illustrative, so treat them as a way to think about the differences, not as a ranking. A more useful thing to take away is the method. You can run a small version of this yourself in an afternoon.
Pick five to ten tasks from your own recent history, ideally closed tickets where you know what a good result looks like. Mix the types: a bug fix with a clear reproduction, a small feature, a refactor across several files, and one task that needs a judgment call. For each, freeze the repository at the commit before the fix, and write down how you will decide whether the result is acceptable.
Run each tool on each task from a clean checkout, with the same instructions file. Then score what actually matters to you:
- Did the tests pass, and were they meaningful, or did the agent change them to get there?
- How much of the diff would you keep?
- Did it stay inside the task, or wander into unrelated code?
- How many times did you need to step in?
- How long did it take, and what did it cost?
Run each task more than once if you can. Agents vary between runs, and one lucky result proves little. If a tool succeeds three times out of three on your refactor, that means far more than a benchmark score.
Don't trust the agent's own report
The single most useful rule in this kind of test: never accept "all tests pass" from the agent. Run the checks yourself from a clean environment. Agents can run the wrong subset, mock the thing under test, or quietly edit an assertion. The harness has to be the judge, which is the core idea in harness engineering.
What changed in 2026
Three shifts make older comparisons less useful. Agents now run long sessions rather than single prompts, so sustained work on large tasks matters more than one-shot quality. Tools have converged on shared conventions: AGENTS.md is widely read, and skills and MCP servers work across clients, so switching costs have fallen. And the bottleneck has moved. Generating code stopped being the limit, and review capacity took its place. A tool that writes a little less but produces small, reviewable changes may be worth more to your team than one that tops a benchmark.
Repeat your evaluation each quarter, since the models under these tools change quickly. Keep the task set, and the comparison takes an hour.
Practical Takeaways
- Agents work best on well-specified, bounded tasks. "Add cursor pagination to the Orders endpoint" beats "improve the API." Clear scope, clear success criteria.
- Context gathering is the differentiator. An agent that understands the code before editing has a better chance. Help it by pointing to relevant code.
- Test generation is a good place to begin. It's low risk, as long as you check that the tests assert real behaviour — start here.
- Review everything. Even the best results had subtle issues — wrong exception types, missing edge cases, incomplete DI registration. Agent output is a first draft, not a final commit.
- Choose on evidence from your own repository. Results vary by task, and the tools change quickly. Pick based on your workflow priorities.