


Elegant Until the Data Disagrees
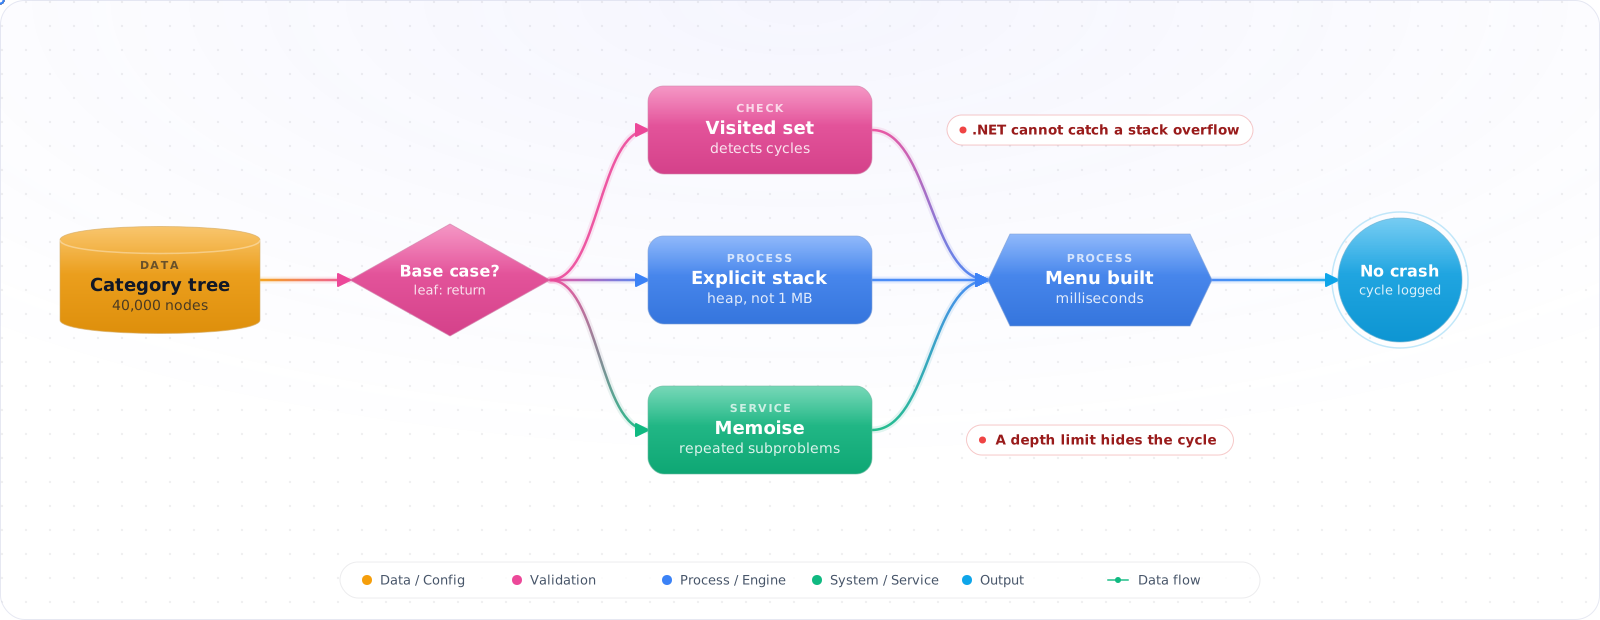
Take a typical case, made up for illustration. A catalogue service built category menus with a six-line recursive function. It worked for years, until a supplier import made “Outdoor Lighting” the parent of “Garden”, which was already its ancestor. The walk went round the loop until the stack overflowed, and because .NET cannot catch a stack overflow, the process died, restarted, and died again on the next menu request.
Recursion is the clearest way to express nested problems, and it quietly trusts the data to be shallow and acyclic. The skill is knowing when that trust holds. Below is how to write recursive functions that stop, when to switch to an explicit stack, how memoisation turns exponential work into linear, and why a depth limit is not a fix for a cycle.
- You wrote a recursive Fibonacci and it crawled at n = 40
- Your tree traversal works on test data but stack-overflows in production
- You can't explain when to use recursion vs explicit stack vs iteration
- You've never converted a tail-recursive function to a loop and don't know why .NET doesn't do it for you
Base Cases, Progress and the Call Stack
Every recursive function is three things:
- Base case — the smallest input where the answer is direct.
- Recursive case — reduce the problem to smaller subproblems.
- Combine — assemble the subproblem answers into the answer for this call.
If you can't articulate all three in one sentence each, you don't understand the recursion yet. Add memoization when subproblems overlap; convert to iteration when depth is unbounded.
flowchart LR
P["Recursive problem?"] --> B{"Base case clear?"}
B -->|no| FIX["Define base case<br/>(empty / size 1)"]
B -->|yes| O{"Subproblems overlap?"}
O -->|yes| M["Add memoization<br/>(or convert to DP)"]
O -->|no| D{"Depth bounded by O(log n)?"}
D -->|yes| R["Recursion is safe"]
D -->|no| S["Convert to iteration<br/>+ explicit Stack<T>"]
style R fill:#16a34a,color:#fff,stroke:#15803d
style S fill:#dc2626,color:#fff,stroke:#b91c1c
Recursion, Explicit Stacks and Memoisation
Step 1: The textbook example — and what makes it slow
// O(2^n) — recomputes Fib(n-2), Fib(n-3) ... exponentially many times
static long FibSlow(int n) =>
    n < 2 ? n : FibSlow(n - 1) + FibSlow(n - 2);

// FibSlow(40) makes 331,160,281 calls
// FibSlow(50) makes 40,730,022,147 calls, 123x more  ← exponential blow-up
Step 2: Memoization — turn exponential into linear
static readonly Dictionary<int, long> _memo = new();

static long FibMemo(int n)
{
    if (n < 2) return n;
    if (_memo.TryGetValue(n, out var v)) return v;
    return _memo[n] = FibMemo(n - 1) + FibMemo(n - 2);
}
// FibMemo(50) → instant. Recursion depth is still n, so a large enough n
// overflows the stack (and long itself overflows past n = 92).
Step 3: Bottom-up iteration — no stack risk, no allocations
static long Fib(int n)
{
    if (n < 2) return n;
    long a = 0, b = 1;
    for (int i = 2; i <= n; i++) (a, b) = (b, a + b);
    return b;
}
// O(n) time, O(1) space, no recursion at all
Step 4: Recursion that's actually appropriate — divide & conquer
// Tree traversal: depth = O(log n) for a balanced tree → safe to recurse
public record Node(int Value, Node? Left = null, Node? Right = null);

public static int Sum(Node? n) =>
    n is null ? 0 : n.Value + Sum(n.Left) + Sum(n.Right);

// Mergesort: depth = O(log n) → safe
public static int[] MergeSort(int[] a)
{
    if (a.Length <= 1) return a;
    int mid = a.Length / 2;
    return Merge(MergeSort(a[..mid]), MergeSort(a[mid..]));
}
Step 5: Convert to iteration with an explicit stack
// Same logic, but the stack lives on the heap → no StackOverflowException
public static int Sum(Node? root)
{
    if (root is null) return 0;
    var stack = new Stack<Node>();
    stack.Push(root);
    int sum = 0;
    while (stack.Count > 0)
    {
        var n = stack.Pop();
        sum += n.Value;
        if (n.Right is not null) stack.Push(n.Right);
        if (n.Left  is not null) stack.Push(n.Left);
    }
    return sum;
}
// Now safe for trees with millions of nodes, even degenerate (linked-list-like)
Step 6: Tail recursion — and why .NET won't save you
// Tail-recursive: the recursive call is the LAST thing the function does
static long FactTail(int n, long acc = 1) =>
    n <= 1 ? acc : FactTail(n - 1, acc * n);

// F# emits the .tail IL prefix by default (--tailcalls+), and Scala turns
// self-recursive tail calls into loops. The C# compiler never emits .tail. RyuJIT may optimize
// some tail calls but it's not guaranteed. For depth > ~10k you must
// manually convert:

static long Fact(int n)
{
    long acc = 1;
    while (n > 1) { acc *= n; n--; }
    return acc;
}
How Recursive Code Fails
1. Missing or wrong base case. Off-by-one in the base case sends you to StackOverflowException via infinite recursion. Always test with the smallest possible input (empty, single element, depth 1).
2. Overlapping subproblems without memoization. Naive Fibonacci, naive coin-change, naive edit-distance — all are exponential without memoization, O(n) or O(n·m) with it. If the same recursive call happens twice, memoize.
3. Recursing on unbounded depth. Linked lists, file-system trees, JSON from untrusted sources, deeply nested expression trees. All can be adversarial. Use an explicit Stack<T>.
4. Assuming C# does tail-call optimization. It doesn't reliably. StackOverflowException from a tail-recursive function will surprise you in production. Convert to a loop.
5. Cannot catch StackOverflowException. Since .NET 2.0 it terminates the process. You can't wrap recursion in try/catch as a safety net. Either bound the depth or don't recurse.
6. Mutable state captured by recursive closures. Recursive lambdas that capture a mutable variable cause races in parallel code and intermittent bugs in sequential code. Pass state as parameters.
When I Use Recursion
- Use recursion when depth is provably O(log n) — balanced trees, divide & conquer, expression evaluators with bounded depth.
- Use iteration +
Stack<T>when depth could be O(n) — linked lists, untrusted JSON, file system walks. - Add memoization the moment you see the same subproblem twice. Often this means converting to bottom-up DP.
- Never assume tail-call optimization in C#. Manually convert tail-recursive functions to loops if depth could be large.
- Test recursion with empty input, single-element input, and a degenerate (worst-case-depth) input.
- For tree algorithms exposed to user input, increase thread stack with
new Thread(work, maxStackSize: 16_000_000)or convert to iteration. - Document the maximum supported depth in any public recursive API. "Works on small inputs" is a CVE waiting to happen.
Recursion on Real Data
Recursive code is clean on small examples, and it fails on real input in ways that are easy to miss. The most common failure is depth. Python's default limit is 1,000 frames. A .NET stack overflow can't be caught at all, and it kills the process. So any recursion over user-controlled data, such as nested JSON, a comment thread or a folder tree, is a denial-of-service risk. Someone sends you JSON nested 100,000 levels deep, and your parser takes down the server. Most serious parsers have a depth limit for this reason, so make sure yours is set, and set one in your own code too.
Tail call optimisation won't save you in most mainstream languages. The .NET JIT can do it in limited cases, but C# doesn't guarantee it. Python deliberately doesn't do it, and JavaScript engines mostly never shipped it. Don't rely on it unless your language promises it, as Scala does with @tailrec or Kotlin with tailrec.
Converting to an explicit stack
Any recursion can become a loop with a stack you manage yourself. Your stack then lives on the heap, so its limit is memory rather than a thread's stack, and you can add a depth check or a cancellation token:
def walk(root: dict, max_depth: int = 1000) -> list[str]:
    found, stack = [], [(root, 0)]
    while stack:
        node, depth = stack.pop()
        if depth > max_depth:
            raise ValueError("tree too deep")
        found.append(node["name"])
        for child in reversed(node.get("children", [])):
            stack.append((child, depth + 1))
    return found
Recursion in SQL and in agents
The same risks appear elsewhere. A recursive CTE on data with a cycle can run forever without a depth limit. Agents that call sub-agents are also recursive in a sense, and they need the same discipline: a maximum depth, a budget, and a clear base case. A recursive agent with no limit is an infinite loop that costs real money with each step.
Whenever you write something recursive, ask three questions. What is the base case? Does each call definitely move towards it? And how deep can real input go? If you can't answer the third question, add a limit. For overlapping subproblems, memoise, or the runtime can become exponential, as with naive Fibonacci.