

When One Screen Needs Five Requests
GraphQL solves two real problems REST is bad at: over-fetching (mobile downloads 12 fields, uses 3) and under-fetching (one screen needs 5 round trips). The trade is operational complexity — N+1 query risk, harder caching, harder rate limiting. In 2026 the ecosystem has matured around Apollo Federation v2.x for subgraph composition, persisted queries for bandwidth + security, and HotChocolate 15 on .NET (with built-in DataLoader, projection, and federation support).
The right question in 2026 is no longer "REST or GraphQL?" but "where does each fit?" — GraphQL for product/aggregation graphs (BFFs, mobile, partner APIs); REST for resource CRUD, webhooks, and anything cacheable at the edge.
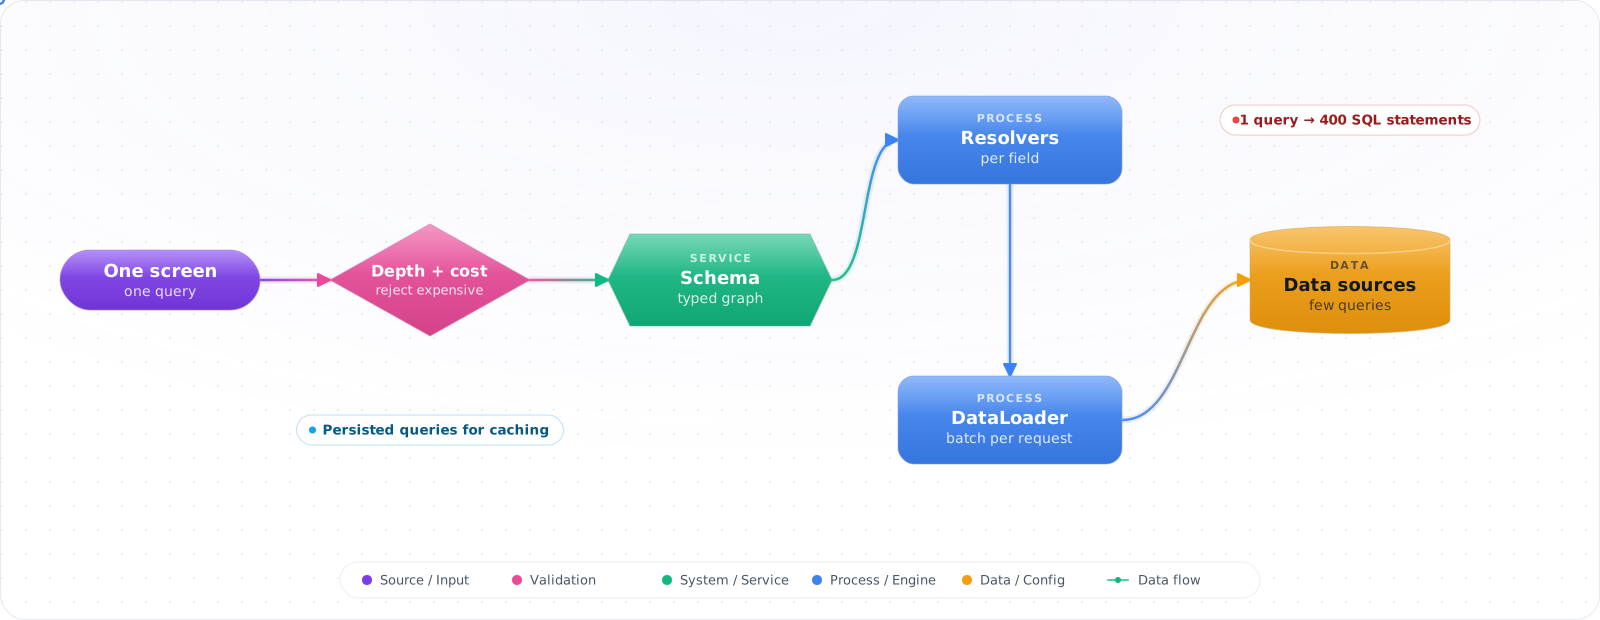
- Your single GraphQL query triggers 400 SQL statements
- Clients send 50KB queries on every render
- You can't rate-limit because every request hits one URL
- Your federated graph composition fails on every deploy
DataLoader for N+1, persisted queries for bandwidth + security, and field-level cost analysis for limits.
How GraphQL Works, and What It Costs
The four building blocks:
- Schema — strongly-typed (SDL). Types, queries, mutations, subscriptions.
- Resolvers — functions that fetch one field. Composable, testable.
- DataLoader — request-scoped batching + caching. Solves N+1.
- Federation — multiple subgraphs composed into one supergraph by a gateway (Apollo Router / Cosmo Router).
flowchart LR
    C["Mobile client"] -->|persisted query hash| GW["GraphQL Gateway<br/>(Apollo Router / HotChocolate)"]
    GW --> S1["Users subgraph"]
    GW --> S2["Orders subgraph"]
    GW --> S3["Catalog subgraph"]
    S1 --> DB1["Users DB"]
    S2 --> DB2["Orders DB"]
    S3 --> DB3["Catalog DB"]

    style GW fill:#E10098,color:#fff,stroke:#a8006d
Building a Production GraphQL Server
Step 1: Define the schema (HotChocolate 15, .NET 10)
var builder = WebApplication.CreateBuilder(args);

builder.Services
    .AddGraphQLServer()
    .AddQueryType<Query>()
    .AddMutationType<Mutation>()
    .AddProjections()       // EF Core projections from selection set
    .AddFiltering()
    .AddSorting()
    .AddInstrumentation();  // OpenTelemetry traces

var app = builder.Build();
app.MapGraphQL();           // POST /graphql + GET /graphql/ui (Nitro)
app.Run();
Step 2: Resolvers with EF Core projection
public class Query
{
    [UseProjection]                       // selection set → SELECT only requested cols
    [UseFiltering]
    [UseSorting]
    public IQueryable<Order> GetOrders([Service] AppDb db) => db.Orders;
}

public class Order
{
    public long Id { get; set; }
    public DateTimeOffset PlacedAt { get; set; }
    public long CustomerId { get; set; }

    // Field-level resolver, batched via DataLoader (next step)
    public async Task<Customer?> GetCustomer(
        CustomerByIdDataLoader loader, CancellationToken ct)
        => await loader.LoadAsync(CustomerId, ct);
}
Step 3: DataLoader for N+1 elimination
// HotChocolate 15 source-generated DataLoader
public static class CustomerDataLoaders
{
    [DataLoader]
    internal static async Task<IReadOnlyDictionary<long, Customer>>
        GetCustomerByIdAsync(
            IReadOnlyList<long> ids,
            AppDb db,
            CancellationToken ct)
        => await db.Customers
            .Where(c => ids.Contains(c.Id))
            .ToDictionaryAsync(c => c.Id, ct);
}
// 100 orders → ONE query: SELECT * FROM customers WHERE id IN (...)
Step 4: Persisted queries (bandwidth + allow-list)
builder.Services
    .AddGraphQLServer()
    .UsePersistedOperationPipeline()       // require known query hashes only
    .AddFileSystemOperationDocumentStorage("./persisted");

// Build step extracts queries from client → SHA-256 → ./persisted/{hash}.graphql
// Production rejects any query not in the store. No more 50KB POST bodies,
// no more arbitrary queries from attackers.
Step 5: Cost analysis + complexity limits
builder.Services
    .AddGraphQLServer()
    .ModifyCostOptions(o =>
    {
        o.MaxFieldCost = 1_000;
        o.MaxTypeCost  = 1_000;
        o.EnforceCostLimits = true;
    });

// In schema:
// type Query {
//   orders(first: Int @cost(weight: "10")): [Order!]! @listSize(slicingArguments: ["first"])
// }
// Stops a malicious 10-level-deep nested query from melting the DB.
Step 6: Federation v2 subgraph
builder.Services
    .AddGraphQLServer()
    .AddApolloFederation()
    .AddType<OrderType>();

public class OrderType : ObjectType<Order>
{
    protected override void Configure(IObjectTypeDescriptor<Order> d)
    {
        d.Key("id");                          // @key(fields: "id")
        d.Field(o => o.Customer)
         .ResolveReferenceWith(...);          // entity resolver for federation
    }
}
// Apollo Router / Cosmo composes this with other subgraphs into one supergraph.
Errors: Why Your Dashboard Says Everything Is Fine
A GraphQL server answers most requests with HTTP 200, including ones that failed. Errors travel in an errors array next to whatever data could be resolved, so one broken resolver produces a response with most of the page and a null where the failing field should be. That is a feature for the client, which can render what it has. For operations, it is a trap: load balancer metrics and uptime checks see a wall of 200s while a resolver fails on every request.
Three practices make failures visible again:
- Measure at the resolver, not the HTTP layer.Emit metrics and traces per operation name and per resolver, with error counts. Your alert is “error rate for
CheckoutPageabove 1%”, not “5xx rate”. - Classify errors. Put a stable code in
extensions.code(for exampleNOT_FOUND,FORBIDDEN,INTERNAL) so clients and dashboards can tell a user mistake from a server fault. - Model expected failures in the schema.“Card declined” is not an exception, it is a result. Return a union such as
PlaceOrderPayload = OrderPlaced | CardDeclined | OutOfStock, so clients must handle each case and theerrorsarray is reserved for the unexpected.
Evolving a Schema Without Versions
GraphQL APIs are usually not versioned. The schema evolves in place, and the rule that makes this work is simple: add freely, remove only what nobody uses. New fields and types are safe because clients only receive what they ask for. To remove or change a field, mark it @deprecated(reason: "Use deliveryWindow"), then watch field-level usage. Because every client names the exact fields it wants, you can know precisely which operations, and therefore which apps, still read the old field. When usage reaches zero, or reaches only clients whose owners have agreed a date, remove it.
Put that check in CI. Schema registry tools compare a proposed schema with the operations clients have actually sent recently and fail the build when a change would break one of them. That is a stronger guarantee than a version number, because it is based on real usage rather than on what might be used.
How GraphQL Servers Get Into Trouble
- N+1 everywhere. Every nested field that hits a DB without DataLoader is an N+1 waiting to happen. Make DataLoader the default, not the exception.
- Allowing arbitrary queries in production. Without persisted queries or query allow-listing, a client (or attacker) can request the whole graph. Use
UsePersistedOperationPipeline. - No depth/cost limits. A 7-level nested query on a graph with cycles can run for hours. Set
MaxFieldCostand depth limits before going live. - Treating mutations like REST. Mutations should return the updated entity (so clients update their cache without a refetch).
voidmutations are an anti-pattern. - One giant monolith schema.Past ~50 types it's painful. Federate by domain (users, orders, catalog) and let a router compose.
- Caching is "free". GraphQL hits one URL, so HTTP caching is harder than REST. Use persisted queries + response cache by query hash + per-field DataLoader cache.
When I Would Use GraphQL
- GraphQL shines for BFFs, mobile, and aggregation graphs. REST still wins for cacheable resource CRUD.
- HotChocolate 15 + EF Core projections eliminates most N+1 risk via selection-set translation.
- DataLoader is non-optional. Treat it like the
usingkeyword. - Persisted queries cut bandwidth and lock down the surface area at the same time. Always on in prod.
- Federation v2 lets teams own subgraphs independently — but only adopt it once you have 3+ teams.
- Set cost + depth limits before the first deploy, not after the first incident.
- Keep mutations returning the updated entity; clients will thank you.