Start With the Quickstart
For a prototype, the quickstart code is fine: a key, a client and a call. It shows whether the idea works. The patterns below are for when real users depend on it, because the things that then go wrong are throttling, slow answers and replies your code can't parse.
Take a typical case, made up for illustration. A support assistant ran happily on one Azure OpenAI deployment for months. Then a launch email went out, traffic jumped six-fold, and about one request in five came back with a 429. The client retried each failure immediately, several times over, which kept the deployment over quota for longer. Around the same time, the team found the app was creating a new client per request.
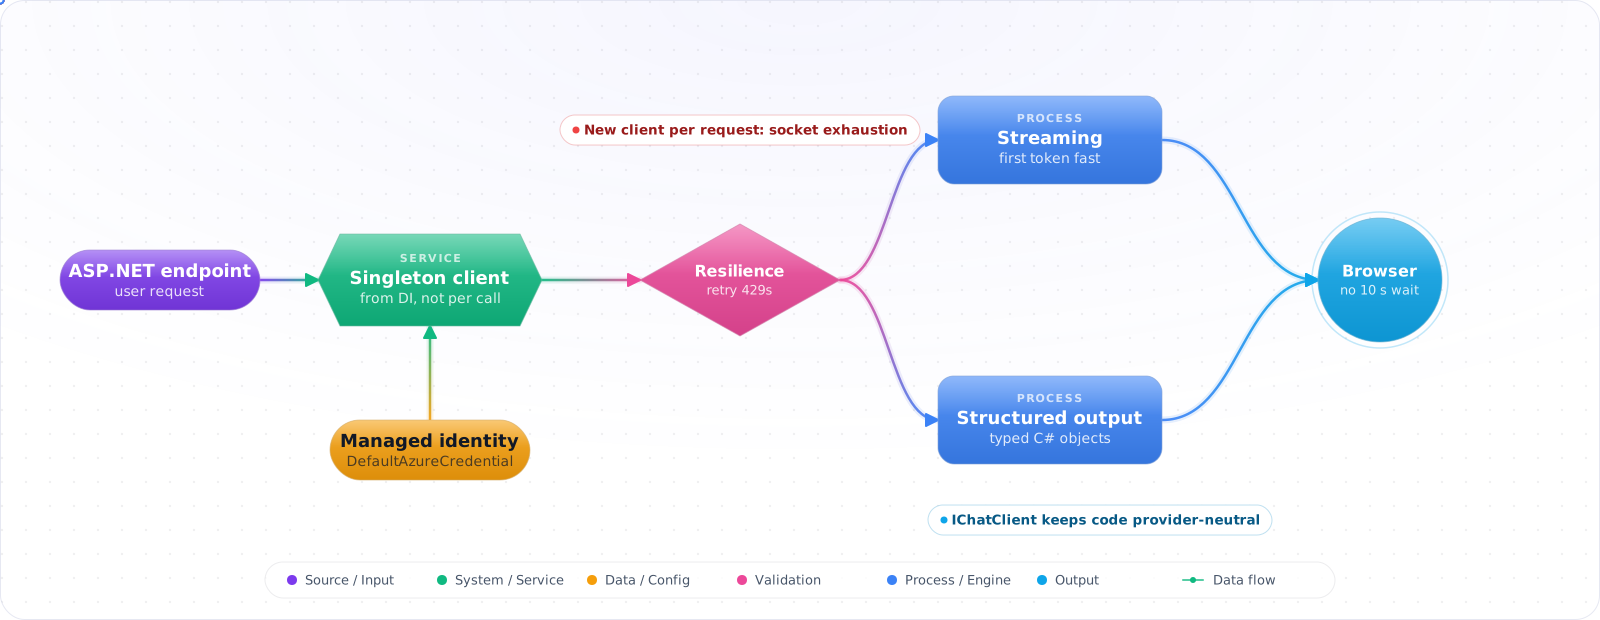
Calling a model from ASP.NET Core takes a few lines. Calling it well means one long-lived client from DI, identity-based auth, retries that respect retry-after, streaming so users are not staring at a spinner, and structured output you can parse. Below are those patterns in .NET, plus what has changed on the platform recently and how to keep your code from aging with it.
- You followed the Azure OpenAI quickstart and it works — but you're not sure it's production-ready
- Your app creates a new
AzureOpenAIClientper request and you want to know why that's wasteful - Users complain about 10-second load times because you're waiting for GPT-5.6 Sol to finish before responding
- You want structured JSON from the LLM but keep getting free-text responses that break your parser
How the SDK and Deployments Fit Together
The Azure OpenAI .NET SDK (Azure.AI.OpenAI) wraps the REST API with typed models, built-in retry logic, and streaming support. The key decision: use AzureOpenAIClient as a long-lived singleton, not a per-request disposable.
      flowchart LR
          A["ASP.NET Core App"] --> B["AzureOpenAIClient - Singleton"]
          B --> C["Chat Completions"]
          B --> D["Embeddings"]
          B --> E["Image Generation"]
          B --> F["Audio/Whisper"]

          C --> G["Azure OpenAI Endpoint"]
          D --> G
          E --> G
          F --> G

          style B fill:#4f46e5,color:#fff,stroke:#4338ca
          style G fill:#059669,color:#fff,stroke:#047857
Production Patterns in ASP.NET Core
Step 1: SDK Setup and Dependency Injection
// Program.cs — Register as singleton
using Azure.AI.OpenAI;
using Azure.Identity;

builder.Services.AddSingleton(sp =>
{
    var endpoint = new Uri(builder.Configuration["AzureOpenAI:Endpoint"]!);
    // No API keys in config. DefaultAzureCredential suits local dev; once deployed, Microsoft
    // advises replacing it with a specific credential such as ManagedIdentityCredential.
    var credential = new DefaultAzureCredential();

    return new AzureOpenAIClient(endpoint, credential);
});

// Register a typed chat client for your deployment
builder.Services.AddSingleton(sp =>
{
    var client = sp.GetRequiredService<AzureOpenAIClient>();
    return client.GetChatClient("gpt-5.6-sol");  // deployment name
});
Why singleton? Azure SDK clients are thread-safe, and Microsoft's guidance is to treat them as singletons. Building one per request repeats setup work for nothing. Don't equate that with new HttpClient() in a loop, though: the SDK clients share an internal HttpClient by default, so socket exhaustion only becomes a risk if you pass in a transport whose lifetime you manage badly.
Check it: Search the code for places that construct the client. There should be one, in startup. Then search your configuration and secrets for an API key. With Entra credentials there should be none.
Step 2: Basic Chat Completion
public class ChatService
{
    private readonly ChatClient _chatClient;

    public ChatService(ChatClient chatClient)
    {
        _chatClient = chatClient;
    }

    public async Task<string> GetCompletionAsync(string userMessage)
    {
        var messages = new List<ChatMessage>
        {
            new SystemChatMessage("You are a helpful technical assistant."),
            new UserChatMessage(userMessage)
        };

        var options = new ChatCompletionOptions
        {
            // Reasoning deployments reject temperature, so it's left out. They also need
            // max_completion_tokens: check what your SDK version sends, because
            // Azure.AI.OpenAI 2.1 wrote this property as max_tokens when we tested it.
            MaxOutputTokenCount = 1000
        };

        ChatCompletion response = await _chatClient.CompleteChatAsync(
            messages, options);

        return response.Content[0].Text;
    }
}
Check it: Log the input and output token counts from one response. If they aren't being recorded, you can't tell which feature is driving the bill.
Step 3: Retry Policy Configuration
The SDK has built-in retry logic, but the defaults aren't tuned for LLM workloads. 429 (rate limit) responses include aRetry-After header — the SDK respects it automatically, but you should configure max retries and timeouts:
// Custom retry options for LLM workloads
var clientOptions = new AzureOpenAIClientOptions
{
    RetryPolicy = new ClientRetryPolicy(maxRetries: 4),
    NetworkTimeout = TimeSpan.FromMinutes(3) // Long outputs take time
};

var client = new AzureOpenAIClient(endpoint, credential, clientOptions);
For production systems, add Polly for more sophisticated retry strategies:
// Polly retry with exponential backoff + circuit breaker
builder.Services.AddResiliencePipeline("azure-openai", pipelineBuilder =>
{
    pipelineBuilder
        .AddRetry(new RetryStrategyOptions
        {
            MaxRetryAttempts = 3,
            BackoffType = DelayBackoffType.Exponential,
            Delay = TimeSpan.FromSeconds(2),
            ShouldHandle = new PredicateBuilder()
                // ClientResultException is what this SDK throws. Retries multiply with the
                // SDK's own, so lower its maxRetries if you add this.
                .Handle<ClientResultException>(ex =>
                    ex.Status == 429 || ex.Status >= 500)
        })
        .AddCircuitBreaker(new CircuitBreakerStrategyOptions
        {
            FailureRatio = 0.5,
            SamplingDuration = TimeSpan.FromSeconds(30),
            MinimumThroughput = 10,
            BreakDuration = TimeSpan.FromSeconds(15)
        });
});
Check it: Send a burst that goes over the deployment's rate limit and watch the retries. They should wait for the time the service asks for, and stop after the configured number of attempts.
Step 4: Streaming Responses
For chat-style UIs, streaming shows text as soon as the first tokens arrive, rather than after the whole response:
// Minimal API endpoint with SSE streaming
app.MapPost("/api/chat", async (
    ChatRequest request,
    ChatClient chatClient,
    HttpContext httpContext) =>
{
    httpContext.Response.ContentType = "text/event-stream";

    var messages = new List<ChatMessage>
    {
        new SystemChatMessage(SystemPrompt), // a server-side constant: never take this from the client
        new UserChatMessage(request.Message)
    };

    await foreach (StreamingChatCompletionUpdate update in
        chatClient.CompleteChatStreamingAsync(messages, cancellationToken: httpContext.RequestAborted))
    {
        foreach (ChatMessageContentPart part in update.ContentUpdate)
        {
            await httpContext.Response.WriteAsync(
                $"data: {JsonSerializer.Serialize(new { text = part.Text })}\n\n");
            await httpContext.Response.Body.FlushAsync();
        }
    }

    await httpContext.Response.WriteAsync("data: [DONE]\n\n");
});
Check it: Open the endpoint in a browser and watch the text arrive. If it appears all at once, something between the model and the browser is buffering the stream.
Step 5: Structured Outputs with JSON Schema
When you need the LLM to return structured data (not free text), use JSON mode with a schema definition:
public async Task<ProductClassification> ClassifyAsync(string productDescription)
{
    var messages = new List<ChatMessage>
    {
        new SystemChatMessage("""
            Classify the product and extract attributes.
            Return JSON matching the provided schema.
            """),
        new UserChatMessage(productDescription)
    };

    var options = new ChatCompletionOptions
    {
        ResponseFormat = ChatResponseFormat.CreateJsonSchemaFormat(
            "product_classification",
            BinaryData.FromObjectAsJson(new
            {
                type = "object",
                properties = new
                {
                    category = new { type = "string",
                        @enum = new[] { "electronics", "clothing", "food", "other" } },
                    confidence = new { type = "number", minimum = 0, maximum = 1 },
                    tags = new { type = "array",
                        items = new { type = "string" } }
                },
                required = new[] { "category", "confidence", "tags" },
                additionalProperties = false
            }),
            strictSchemaEnabled: true
        )
    };

    ChatCompletion response = await _chatClient.CompleteChatAsync(messages, options);
    // A refusal has no JSON to parse. Web defaults match the schema's lowercase names.
    if (response.Refusal is not null) throw new InvalidOperationException(response.Refusal);
    return JsonSerializer.Deserialize<ProductClassification>(
        response.Content[0].Text, JsonSerializerOptions.Web)!;
}
Check it: Run the classification on twenty varied inputs and parse every result. All twenty should deserialise without special handling.
What Changed on the Platform: Foundry, the v1 API, and IChatClient
The integration pattern in this article is stable, but three things around it have moved, and each one affects how long your code lasts without changes.
The service is now part of Microsoft Foundry
Azure OpenAI is documented as Azure OpenAI in Microsoft Foundry Models. Your resource, endpoint and SDK keep working. The model lifecycle is what you need to plan for: a generally available model is retired 18 months after launch and closed to new customers after 12. Standard deployments are upgraded automatically at retirement. Provisioned deployments are not, so they need a manual migration. Set versionUpgradeOption on each deployment deliberately instead of accepting the default.
The v1 API removes the monthly api-version
The next-generation v1 API uses a base URL ending in /openai/v1/ and no longer needs a dated api-version on every call. New features arrive without a version bump, and the standard OpenAI client can call Azure with only a base URL change. If your configuration still carries a preview api-version string, moving to v1 removes a regular source of maintenance.
IChatClient decouples your code from the provider
Microsoft.Extensions.AI defines IChatClient, a provider-neutral abstraction that the Azure OpenAI SDK, the OpenAI SDK and local runtimes all implement. Register that interface instead of the concrete ChatClient, and logging, caching, telemetry and function invocation become middleware you add once.
builder.Services.AddSingleton(sp =>
    new AzureOpenAIClient(endpoint, new DefaultAzureCredential()));

builder.Services.AddChatClient(sp =>
        sp.GetRequiredService<AzureOpenAIClient>()
          .GetChatClient("chat-prod")        // your deployment name
          .AsIChatClient())
    .UseOpenTelemetry()
    .UseFunctionInvocation();

// Controllers and services depend on IChatClient, not on Azure types.
public class SummaryService(IChatClient chat)
{
    public async Task<string> SummariseAsync(string text, CancellationToken ct)
    {
        var response = await chat.GetResponseAsync($"Summarise in three bullets: {text}", cancellationToken: ct);
        return response.Text;
    }
}1. Not setting NetworkTimeout
Default HTTP timeout is 100 seconds. Long completions (2000+ tokens with GPT-5.6 Sol) can exceed this, especially under load. SetNetworkTimeout to 3–5 minutes for generation endpoints.
2. Storing API keys in appsettings.json
Use managed identity in production, through a specific credential such as ManagedIdentityCredential. DefaultAzureCredential suits local dev, where it can use Azure CLI credentials. API keys in config files end up in source control, logs, and error messages.
3. Ignoring token count in responses
Every response includes Usage.InputTokenCount and Usage.OutputTokenCount. Log these. Without usage tracking, you can't identify which features are driving costs or when prompt changes increase consumption.
4. Blocking on streaming enumeration
If you enumerate CompleteChatStreamingAsync into a list before sending to the client, you've defeated the purpose. Stream directly to the HTTP response. Don't collect all chunks then forward them.
5. One deployment for everything
Use separate Azure OpenAI deployments (and ideally separate resource instances) for different workload tiers: chat (latency-sensitive, lower TPM), batch processing (throughput-optimized, higher TPM), embeddings (high volume, separate quota).
Try It on Your Own System This Week
Three checks on an application that already calls Azure OpenAI, about an hour in total:
- List your deployments and their model versions. Write the retirement date next to each.
- Check the network timeout on the client. A long completion can outlast the default.
- Count the workloads that share one deployment. Interactive chat and batch jobs compete for the same quota unless you separate them.
Before You Depend on a Deployment
Treat Azure model versions as a dependency with an end date. Note the retirement date for each deployment in your repo, and alert ahead of it. Remember that the newest family on Azure usually lags the OpenAI API, so check the Azure model lifecycle page before you promise a model to a customer.
- Register
AzureOpenAIClientas a singleton. It's thread-safe, and per-request instances only add setup overhead. - Use Microsoft Entra credentials instead of API keys:
DefaultAzureCredentiallocally, and a specific credential such asManagedIdentityCredentialonce deployed. - Add a Polly circuit breaker on top of the SDK's built-in retries for production resilience. The SDK retries handle transient errors; Polly handles sustained outages.
- Stream responses for any user-facing chat feature. The time-to-first-token matters more than total completion time for perceived performance.
- Log token counts on every request. Cost visibility is a production requirement, not a nice-to-have.