

AI Wisdom

Tag

production

7 articles tagged with “production”

A/B-testinga-starA2AACRadaptive-thinkingagent-observabilityagent-patternsagent-protocolsagent-securityagent-skillsagentsAGENTS.mdaggregationaiai-gatewayAI-SearchaksalertingAlertmanageralgorithmsAnthropicAnthropic-APIAPEapi-designapi-gatewayAPI-providersapi-versioningapimAPMapp-routerapp-serviceappsecarchitectureArizearm-templatesASP.NET-Coreaspnet-coreaspnetcoreassertion-functionsassertsasyncauditauthenticationauthorizationAutoGenautomationazureAzure-APIMazure-content-safetyazure-front-doorazure-functionsAzure-OpenAIazure-policyazure-storagebatch-APIbddbeam searchBedrockbenchmarksbest-practicesbfsbi-encoderbias-detectionbicepbinary-searchbranchingbstBundlercache-componentscachingcap-theoremcapability-taggingCapitalizecascadingcase-based-reasoningchain-of-thoughtchartschatbotcheckpointingchunkingCIci-cdci-optimizationcicdclass-decoratorClaudeClaude-CodeCLAUDE.mdclean-architecturecloudcloud-securitycloudeventscode-reviewCodexcoding-agentscompactioncomparisoncompilerOptionscompliancecomposeconcurrencyconcurrent-renderingconditional-typesconsistencyconsistent-hashingconstrained-generationconstraintsconsumer-drivencontainer-registrycontainerscontent-moderationcontent-safetycontextcontext-compressioncontext-engineeringcontext-windowcontract-testingconversational-agentsCopilotcosmos-dbcost-allocationcost-controlcost-optimizationcost-per-taskcost-performanceCoTcoveragecqrscross-sessioncsharpCursorcvecypress.d.tsdapperdashboardsdastdata-fetchingdatabasesdataloaderdatasetsddddecision-frameworkdeclaration-filesdecoratorsDeepEvalDefinitelyTypeddependency-injectiondependency-scanningdeployment-slotsdeploymentsdeprecationdesign-patternsdevopsdfsdijkstradiscriminated-unionsdistributed-tracingdistributivedockerDocker-HubdocumentationDORAdotnetdotnet-9drift-detectionDSPydurable-executiondynamic-discoverydynamic-programminge2e-testingedge AIef-coreef-core-9embeddingsengineeringenvironmentsepisodic-memoryerror-budgetevalsevaluationevent-drivenevent-gridevent-hubseventingexamplesexperience-replayexperimentalDecoratorsfactualityfail-fastfaithfulnessfeature-flagsfederationfew-shotfiberfine-tuningFinOpsflaky-testsflex-consumptionfrontendfunction-callinggarakGeminiGemmagen-ai-semantic-conventionsgenericsGHCRgitGitFlowGitHubgithub-actionsgoal-decompositiongolden-signalsGoogle-DeepMindGPTgpt-4oGPT-6GPUgrammargraphgraphqlGroqgroundingGroupChatgrpcguardrailshallucinationhallucination-detectionharmful-contentharness-engineeringhclhealth-checksheapHelmhookshotchocolateHPAhttphttp2http3hybridcacheiacICLidempotencyidentityimage-scanningin-context-learningincident-responseindexesinferinferenceinfrastructureinput-validationintegrationintegration-testinginteroperabilityintrosortinvariantisolationIstiojailbreakjestjoinsjotaiJSONJSON-modejsonbjwtk8skey-remappingkey-vaultkiotaknapsackknowledge-baseKQLkubernetesKV cacheLangChainLangfuseLangGraphLangSmithlanguagelatencyleast-agencylegacy-codeLinkerdlinqLlamallama.cppLLMLLM-as-judgeLLM-monitoringLLM-securityload-balancinglogginglong-running-agentslong-term-memorylost-in-the-middlelower-boundmanaged-identitymapped-typesmaterialized-viewsMCPmemoizationmemorymemory-consolidationmergemessage-queuemessagingmeta-promptingmetadatametricsmicroservicesmicrosoftminimal-apisMistralmockingmocksModel-Context-Protocolmodel-routingmodel-selectionmodel-servingmoderationmodule-augmentationmodule-resolutionmodulesmongodbmonitoringmonorepomswMTEBmTLSmulti-agentmulti-stage-buildsmulti-tenantmultimodalmvccnarrowingnetwork-securitynextjs-16Node16normalizationnosqloauthoauth2observabilityoffline-evalsoidcOmiton-callon-deviceonline-evalsopaopen-sourceopen-weightOpenAIOpenAI-APIopenapiOpenTelemetryOPROorchestrationOTELOutlinesoutput-formatoutput-validationOWASPP99paaspackage-exportspactpactflowpage-objectsPagerDutyparsingPartialpartitioningpathspattern-matchingperformancepersonal-AIpgvectorPhiPhoenixPickPIIPII-filteringpineconepipelineplanningplaywrightpluginspolicy-as-codepollypostgresqlpricingproductionproduction-monitoringprogressive-disclosureproject-referencesprompt-cachingprompt-designprompt-engineeringprompt-injectionprompt optimisationpromptfooprotobufpulumipythonQdrantqualityquality-gatesquality-scorequantizationqueuesRAGRAG-evaluationRAGASrate-limitingreactreact-19react-compilerreact-internalsreact-queryreact-server-componentsrealtimereasoningreasoning-effortRecordrecursionrecursive-typesred-blackred-green-refactorred teamingredisreflectionregression-testingrelease-managementreplanningresource-limitsResponses-APIrestreusable-workflowsrlsrolling-updatesruntime-safetysaga-patternsandboxingsastsbomscaleschemaschema-designschema-validationSDKsdlcsearchsecrets-managementsecuritysecurity-testingself-consistencyself-hostingSemantic-Kernelsemantic-similarityserializableserver-actionsserverlessservice-busservice-meshshardingshortest-pathsidecar-proxysignalrSKILL.mdSLISLMSLOslopsquattingsnapshot-testingsoftware-designsortingspec-driven-developmentspeculative-decodingspiessqlstabilitystate-graphstate-managementstreamingstreamsstrict-modestridestring-typesstructured-loggingstructured-outputstubssummarisationsupertestsupply-chainsystem-designtail-calltanstack-querytask-framingTC39tddtemplate-literalstemplatesterraformtest-architecturetest-doublestest-pyramidtestcontainerstestingtesting-patternstesting-strategythreat-modelingtoken-buckettoken-budgettoken-economicstoken-limittoken-maskingtoken-trackingtokenstokens-per-secondtool-callingtool-registrytool-usetopological-sortToTtoxicitytracingtrajectorytransactionstree-of-thoughttreestrietrunk-basedtsconfigTTFTtype-guardstype-narrowingtype-predicatestype-safe-routestype-systemtype-transformstypestypescriptunit-testingusage-metricsuser-feedbackutility-typesvalidationvalkeyvaluesvaultvector-dbvector-searchvector-storevendor-neutralverificationversion-controlversioningVertex-AIvisual-regressionvitestvLLMvoice-agentsvulnerabilitiesweaviateweb-apiweb-securityWebLLMwebsocketswindow-functionsWindsurfwiremockworkflowsworking-memoryworkload-identityworkspacesxunityarpzero-shotzero-trustzodzustand
AI Engineering
UsersAssistantVector indexKeyword indexRerankerLLM

Designing RAG Systems That Actually Scale

Intermediate

Chunking strategies, embedding pipelines, retrieval patterns, and when RAG breaks down in production systems.
Updated 12 min
Read →
AI Engineering
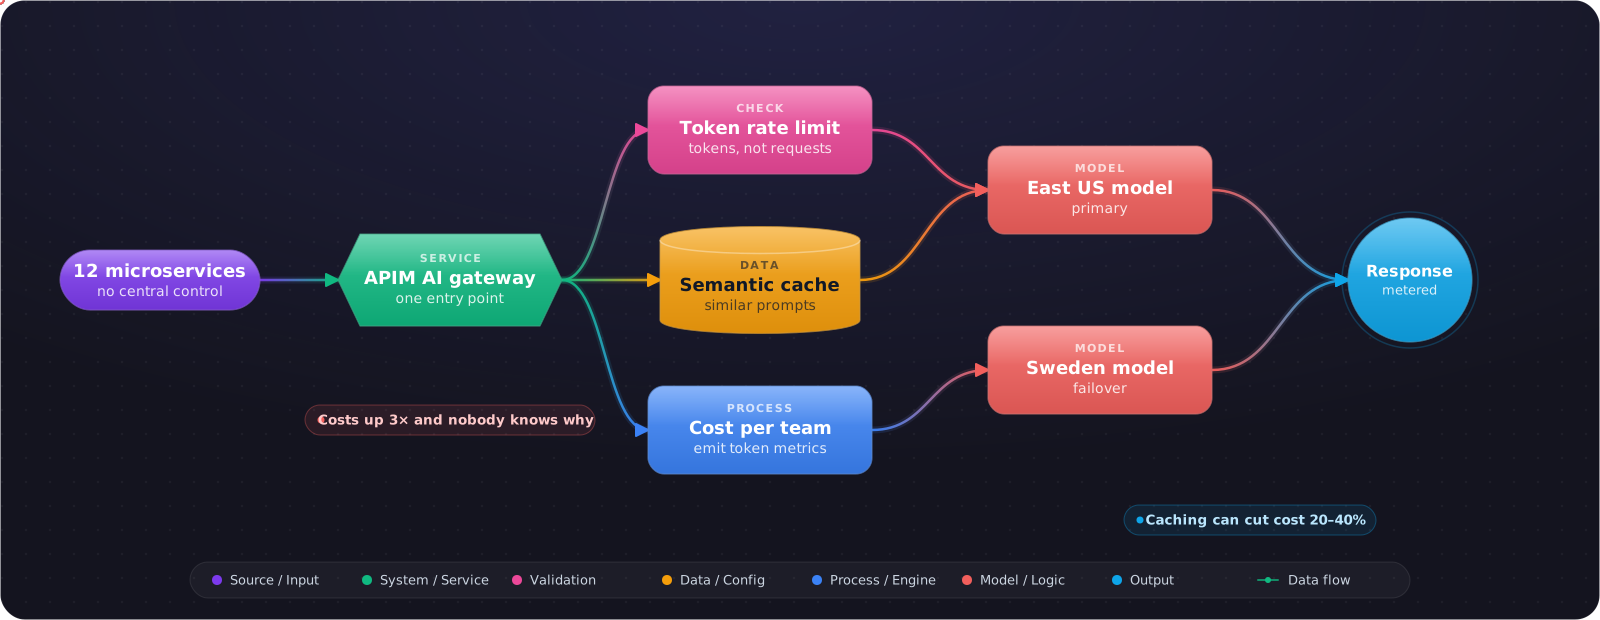
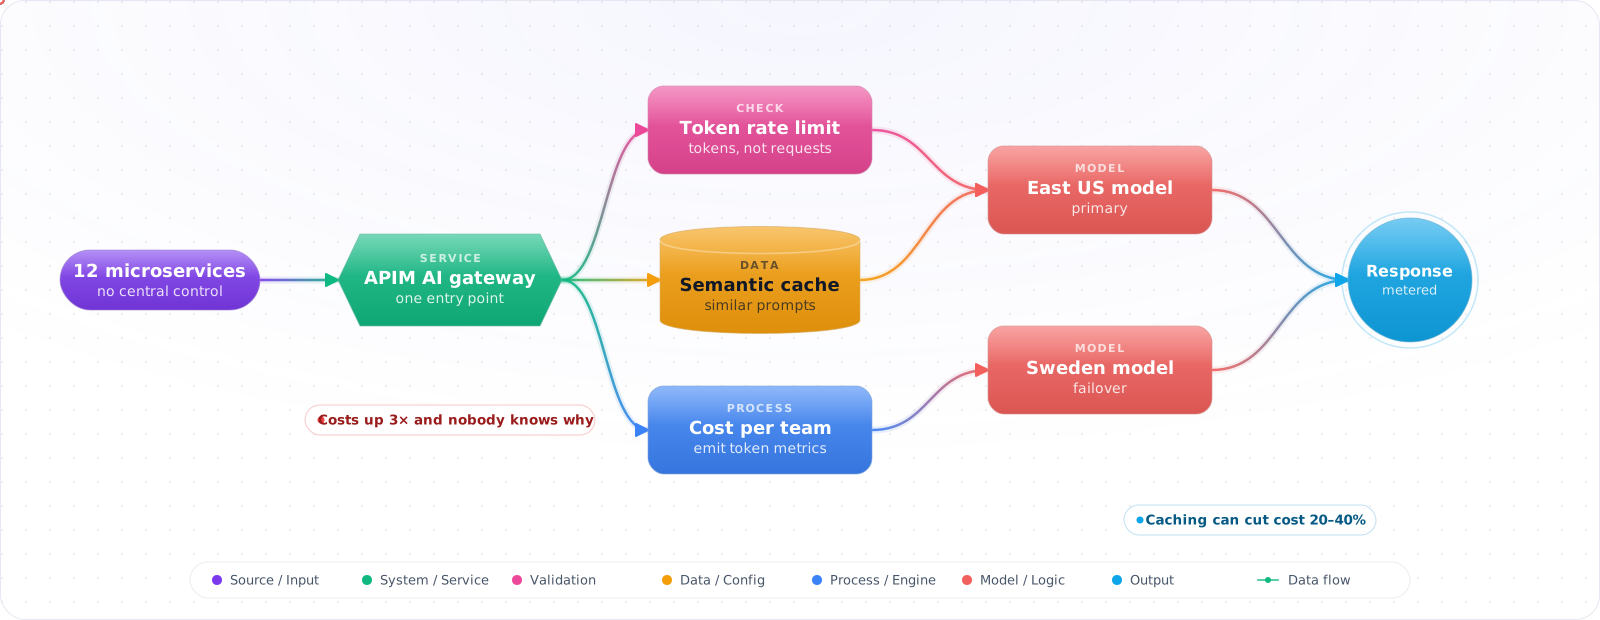
Twelve microservices call Azure OpenAI through one AI gateway on Azure API Management that applies token-based rate limits, semantic caching and per-team cost tracking, and fails over between regional deployments.Twelve microservices call Azure OpenAI through one AI gateway on Azure API Management that applies token-based rate limits, semantic caching and per-team cost tracking, and fails over between regional deployments.

The AI Gateway Pattern: Why Every Production LLM Needs One

Intermediate

API Management, rate limiting, semantic caching, and cost control with Azure APIM as an AI Gateway.

Updated 10 min
Read →
Agentic Systems
Product teamSupervisorResearch workersCRM workerWriterJob storeDeadline, budgetOne trace

Multi-Agent Architecture Patterns in Production

AdvancedPRO

Orchestrator, supervisor, and swarm patterns for multi-agent systems with real trade-offs and failure modes.
Updated 14 min
Read →
AI Engineering
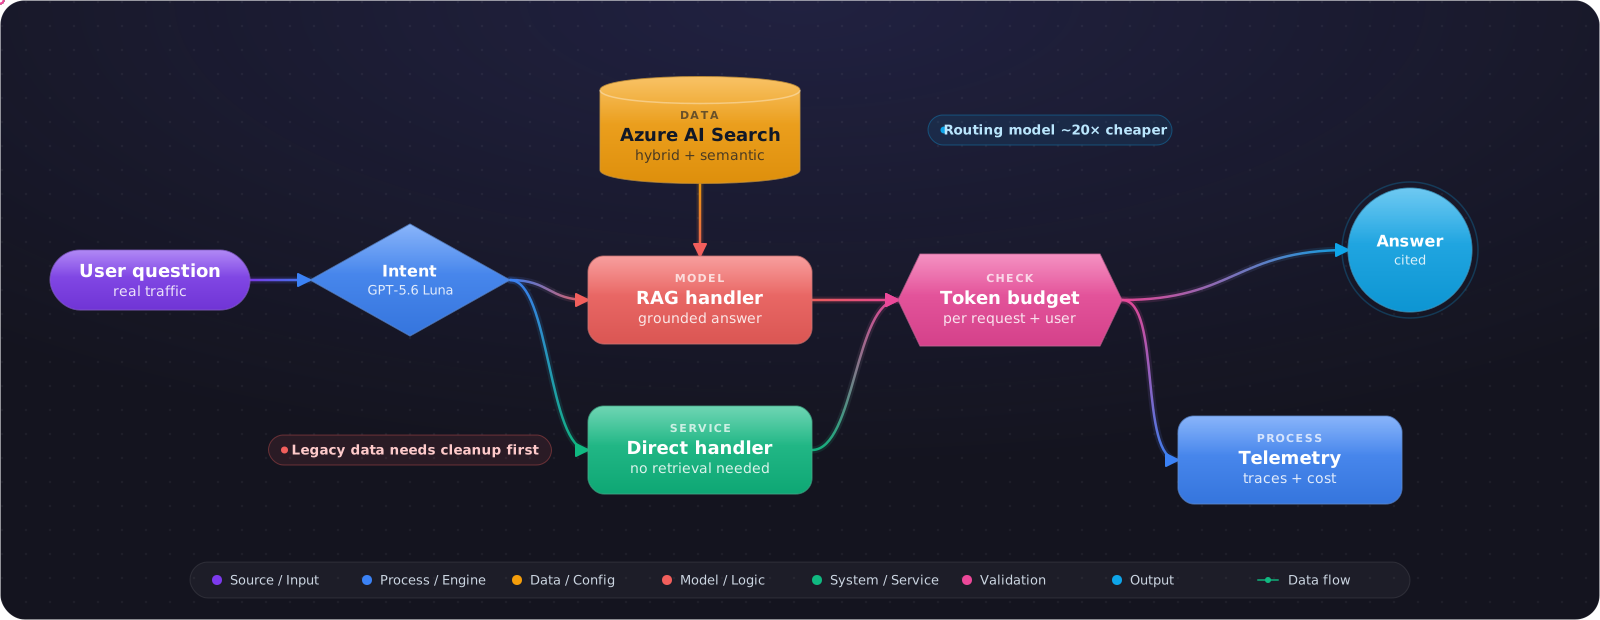
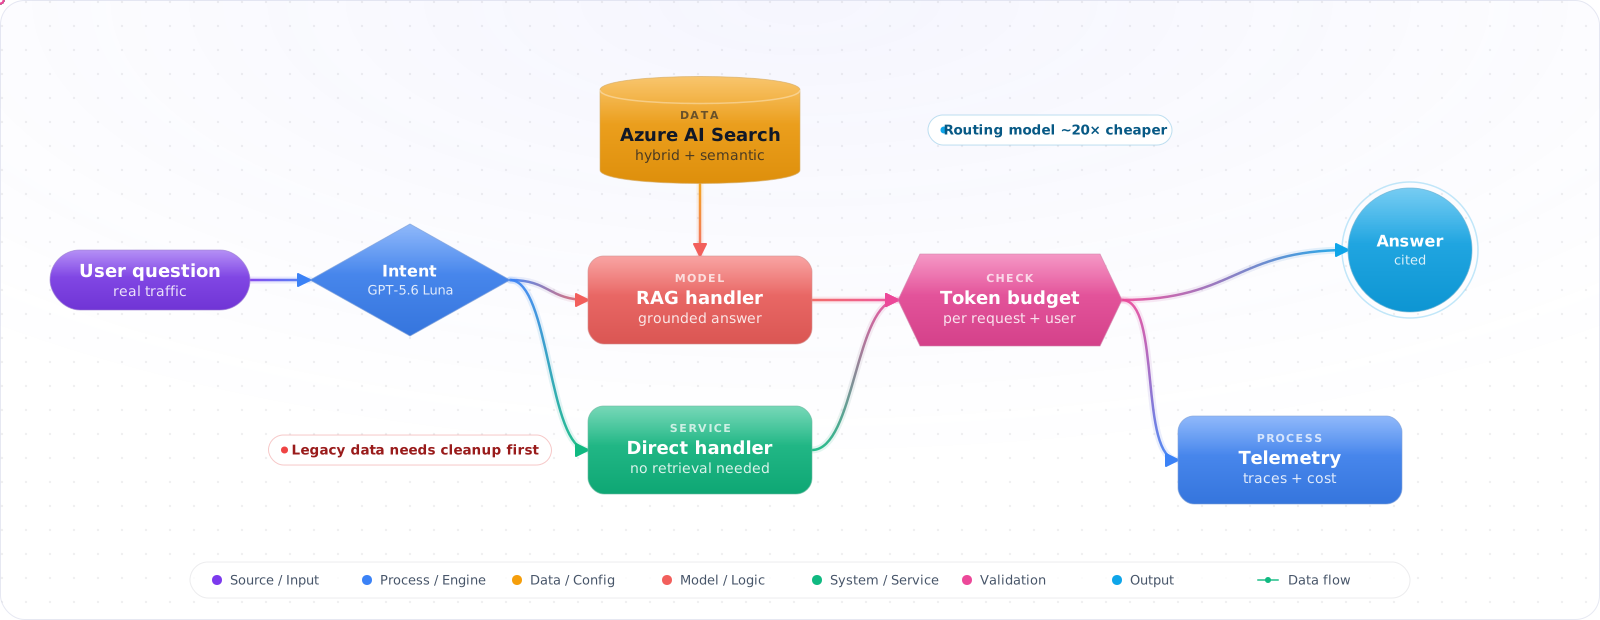
A production AI system on Azure: an orchestrator classifies intent with a cheap model, routes to RAG over Azure AI Search with hybrid retrieval or to direct handlers, enforces token budgets, and traces every step.A production AI system on Azure: an orchestrator classifies intent with a cheap model, routes to RAG over Azure AI Search with hybrid retrieval or to direct handlers, enforces token budgets, and traces every step.

How to Build a Production-Ready AI System (Azure OpenAI + AI Search — Real Architecture)

AdvancedPRO

Azure OpenAI + AI Search + embeddings — real-world architecture for production AI systems, including legacy data, orchestration, hybrid retrieval, cost control, and failure modes.

Updated 15 min
Read →
Backend (.NET / C#)
CustomersSupport assistantOne shared clientEntra identityModel deploymentRetry and breaker

Integrating Azure OpenAI with ASP.NET Core: A Production Guide

Foundational

SDK setup, retry policies, streaming responses, and structured outputs for Azure OpenAI in .NET production applications.

Updated 10 min
Read →
AI Engineering
EmployeeHR portalKernelModelLeave pluginHR servicesTraces

Building Reliable AI Agents with Semantic Kernel

Intermediate

Plugin architecture, memory, planners, and error handling patterns for building production AI agents in .NET with Semantic Kernel.
Updated 11 min
Read →
LLM Model Landscape
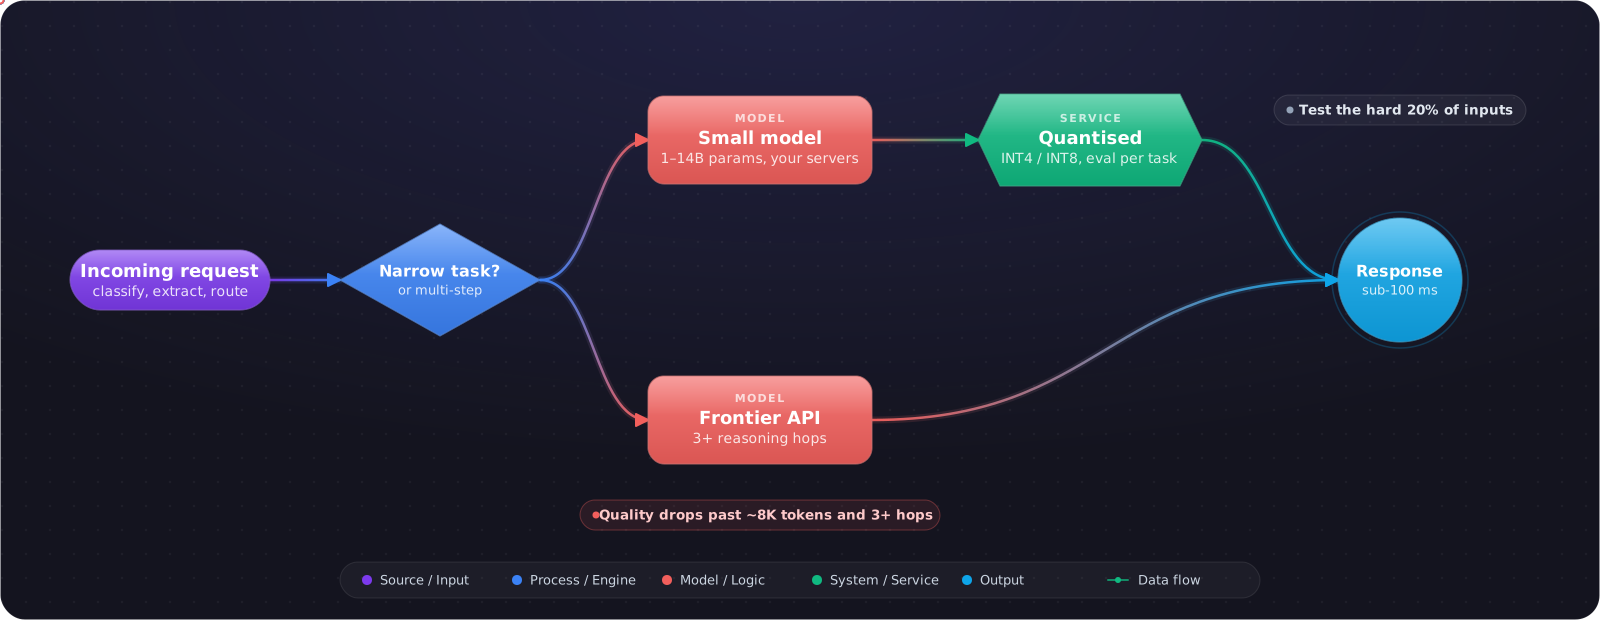
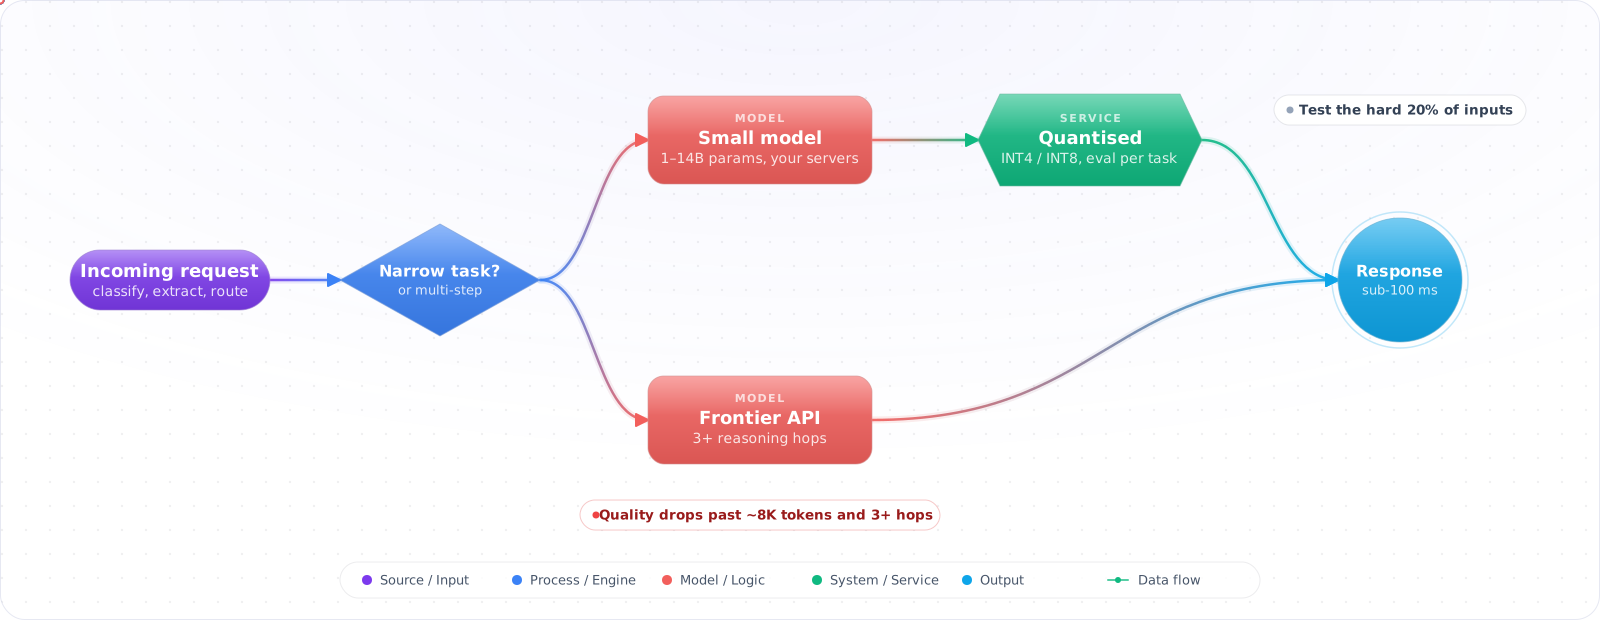
A router sends narrow requests to a quantised small model on your own servers and hard multi-step requests to a frontier API.A router sends narrow requests to a quantised small model on your own servers and hard multi-step requests to a frontier API.

Small Language Models in Production

When and how to use small language models like Phi, Gemma, and Mistral in production — quantization, deployment patterns, and latency-cost trade-offs.

Updated 11 min
Read →