Start With the Dashboard You Already Have
For a small service with few users, the default dashboard from your platform is enough, because you'd notice a problem yourself. Deliberate monitoring starts when customers begin finding problems before you do, and at that point more panels aren't the answer.
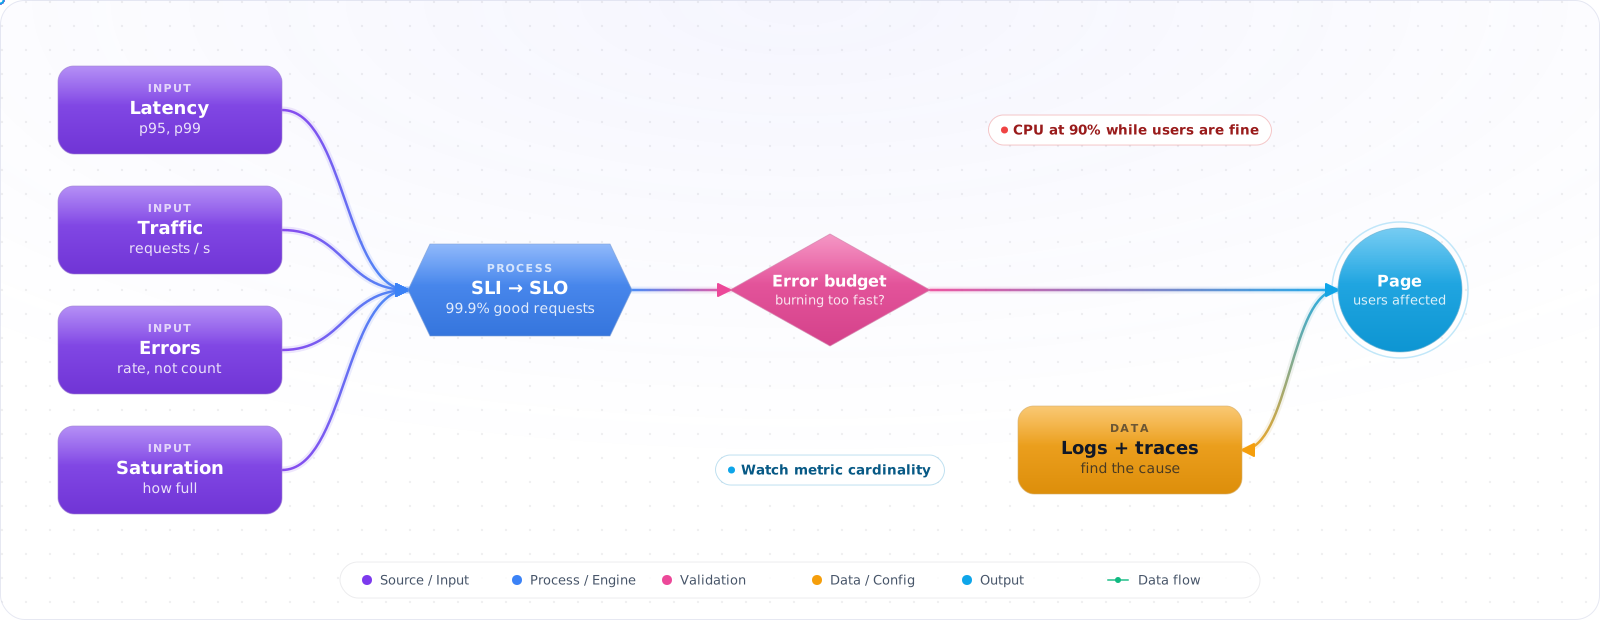
Most monitoring setups are reactive: CPU alert fires, you look at dashboards, you guess what broke. Good production monitoring flips this — it tells you what users are experiencing before they file tickets, alerts on symptoms not causes, and gives you the context to diagnose fast. The Four Golden Signals and SLOs are the framework.
- You get paged at 2am for CPU at 90% while the service is actually fine
- Your error rate is 5% but you don't know if that's normal or a crisis
- Incident investigation starts with “check the logs” with no obvious starting point
- You have 200 Datadog monitors but none of them correlate to user impact
SLO-based alerting means far fewer pages, and the ones you do get need a person.
The Four Golden Signals
Google SRE defined four signals to watch for any service. They're sufficient for detecting most production problems:
flowchart TD
    signals["Four Golden Signals"] --> latency
    signals --> traffic
    signals --> errors
    signals --> saturation

    latency["Latency
How long requests take
(p50, p95, p99 — not average)"]
    traffic["Traffic
How much demand
(requests/sec, events/sec)"]
    errors["Errors
Failed requests rate
(5xx, timeouts, business errors)"]
    saturation["Saturation
How full the service is
(CPU, memory, connection pool, queue depth)"]

    style signals fill:#0078D4,color:#fff,stroke:#005a9e
Check it: Open your service's main dashboard and find traffic, errors, latency and saturation. If that takes more than a few seconds, the dashboard is showing too much.
SLI / SLO / SLA
// SLI — Service Level Indicator
// A quantitative measure of service behaviour
// Example: proportion of requests served in < 200ms

const sli = {
  name: 'API latency',
  query: 'sum(rate(http_request_duration_seconds_bucket{le="0.2"}[5m])) / sum(rate(http_request_duration_seconds_count[5m]))',
  // Value: 0.0 to 1.0
};

// SLO — Service Level Objective
// The target value for an SLI
// Example: 99.5% of requests in < 200ms over a 30-day rolling window

const slo = {
  sli: 'API latency',
  target: 0.995,    // 99.5%
  window: '30d',
};

// SLA — Service Level Agreement
// The contractual commitment to customers (usually weaker than SLO)
// Example: 99% of requests in < 1s (looser than the SLO, so you breach the SLO first)

// Error budget = time/requests you can "spend" on incidents
// Error budget = (1 - SLO target) * window
// = (1 - 0.995) * 30 days
// = 0.005 * 43,200 minutes
// = 216 minutes per month of allowed degraded latencyCheck it: Work out last month's value for your main indicator and compare it with the target. If you can't compute it, the indicator isn't being measured.
Error Budget Alerts
Alert on error budget burn rate, not on individual metric thresholds. A five-minute 5xx spike at 3am that uses a fraction of a percent of your monthly error budget is not worth waking someone up. A sustained 14.4x burn rate, which would exhaust a 30-day budget in about two days, is.
# Prometheus alerting rules — SLO burn rate approach
groups:
  - name: api_slo_burn_rate
    rules:
      # Fast burn: high severity — page immediately
      # 14.4x burn rate = 30-day budget exhausted in ~50 hours
      # threshold: 1 - 14.4 * (1 - 0.995) = 0.928
      - alert: APILatencySLOHighBurn
        expr: |
          sum(rate(http_request_duration_seconds_bucket{le="0.2"}[1h]))
          / sum(rate(http_request_duration_seconds_count[1h])) < 0.928
          and
          sum(rate(http_request_duration_seconds_bucket{le="0.2"}[5m]))
          / sum(rate(http_request_duration_seconds_count[5m])) < 0.928
        labels:
          severity: critical
        annotations:
          summary: "API latency SLO burning fast — page on-call"
          description: "14.4x burn rate. Budget exhausted in ~2 days if sustained."

      # Slow burn: ticket only — 3x burn rate, budget exhausted in 10 days
      - alert: APILatencySLOSlowBurn
        expr: |
          sum(rate(http_request_duration_seconds_bucket{le="0.2"}[6h]))
          / sum(rate(http_request_duration_seconds_count[6h])) < 0.985
        for: 60m
        labels:
          severity: warning
        annotations:
          summary: "API latency SLO degraded — create ticket"
          description: "Budget burning at elevated rate. No immediate action needed."

      # Don't do this:
      # - alert: HighCPU
      #   expr: cpu_usage > 0.9
# This is a cause, not a symptom. CPU at 90% may be fine.Check it: Replay your last incident against the burn-rate rule. It should have fired early in the incident, and it shouldn't have fired on last week's brief blip.
Structured Logging
import pino from 'pino';
import type { Request, Response } from 'express';
import { trace } from '@opentelemetry/api';

// ✅ Structured — queryable, filterable, correlatable
const logger = pino({
  level: process.env.LOG_LEVEL ?? 'info',
  base: {
    service: 'api-server',
    version: process.env.APP_VERSION,
    env: process.env.NODE_ENV,
  },
});

// Log with context that enables downstream queries
export function logRequest(req: Request, res: Response, durationMs: number) {
  logger.info({
    msg: 'HTTP request',
    method: req.method,
    path: req.path,
    statusCode: res.statusCode,
    durationMs,
    requestId: req.get('x-request-id'),
    userId: res.locals.userId,    // set by your auth middleware; correlate errors to users
    traceId: trace.getActiveSpan()?.spanContext().traceId,    // correlate to distributed traces
  });
}

// Error logging with full context
export function logError(error: Error, context: Record<string, unknown>) {
  logger.error({
    msg: 'Unhandled error',
    err: {
      message: error.message,
      stack: error.stack,
      name: error.name,
    },
    ...context,
  });
}

// ❌ Unstructured — impossible to query at scale
// console.log('User ' + userId + ' failed to checkout: ' + error.message);
Distributed Tracing
// OpenTelemetry — vendor-neutral tracing
import { NodeSDK } from '@opentelemetry/sdk-node';
import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http';
import { HttpInstrumentation } from '@opentelemetry/instrumentation-http';
import { ExpressInstrumentation } from '@opentelemetry/instrumentation-express';
import { PgInstrumentation } from '@opentelemetry/instrumentation-pg';
import { trace, SpanStatusCode } from '@opentelemetry/api';

// src/instrumentation.ts — loaded before everything else
const sdk = new NodeSDK({
  serviceName: 'api-server',
  // Reads OTEL_EXPORTER_OTLP_ENDPOINT and appends /v1/traces; passing that
  // base URL as `url` would skip the suffix
  traceExporter: new OTLPTraceExporter(),
  instrumentations: [
    new HttpInstrumentation(),        // auto-instrument all HTTP calls
    new ExpressInstrumentation(),     // auto-instrument Express routes
    new PgInstrumentation(),          // auto-instrument PostgreSQL queries
  ],
});

sdk.start();

// Manual span for custom operations
const tracer = trace.getTracer('api-server');

async function processPayment(orderId: string) {
  return tracer.startActiveSpan('process-payment', async (span) => {
    try {
      span.setAttribute('order.id', orderId);
      const result = await paymentProvider.charge(orderId);
      span.setAttribute('payment.provider', 'stripe');
      return result;
    } catch (error) {
      span.recordException(error as Error);
      span.setStatus({ code: SpanStatusCode.ERROR });
      throw error;
    } finally {
      span.end();
    }
  });
}Check it: Pick a slow request from yesterday and find its trace. It should show which service and which call the time went on.
Metric Cardinality: The Cost Nobody Budgets For
Every unique combination of label values on a metric is a separate time series that the monitoring system stores and indexes. A request counter labelled by method, route and status code is a few hundred series. Add a user id label and it becomes millions. The bill grows, queries slow down, and at some point the monitoring system itself becomes the incident.
| Do not use as a metric label | Use instead |
|---|---|
| User id, tenant id, session id, request id | Put it on the log line and the trace span |
The raw URL path, such as /orders/8841 | The route template, such as /orders/:id |
| Error message text | A small fixed set of error codes |
| Timestamps or version hashes that change with every deployment | A separate build-info metric |
The rule that follows is a division of work. Metrics answer how much and how often, with a small number of bounded labels. Logs and traces answer who and which one, with as much detail as you need. Exemplars connect the two: a latency bucket can carry the id of one trace that fell into it, so you can go from a slow percentile to an actual request without labelling the metric by request.
Check it: List your metrics by number of series and look at the labels on the largest. Any label that holds a user, tenant or request id belongs on a log line or a span.
Try It on Your Own System This Week
Three checks on a service you already monitor, about an hour in total:
- Ask who found your last three incidents. If customers found them first, your signals aren't measured where users feel them.
- Count the panels on your main dashboard. Then count the ones anyone looked at during the last incident.
- Find a latency chart that shows an average. Replace it with p95 and p99.
Pitfalls
Alerting on averages
Average latency hides tail latency problems. If 99% of your requests complete in 50ms but 1% take 10 seconds, your average might look fine at 150ms. Always use percentiles (p95, p99) for latency SLOs. Your slowest users are the ones who churn.
Too many dashboards, not enough context
A 50-panel Grafana dashboard that shows everything doesn't help you during an incident. Create a single “service health” dashboard that shows the four golden signals and nothing else. Link from alert to dashboard to runbook — make the path automatic.
No runbooks
Every alert should have a runbook: what to check first, what actions to take, when to escalate. A runbook doesn't need to be long — three bullet points written by whoever created the alert is 10x better than nothing. The goal is any on-call engineer can handle it, not just the one who wrote the code.
OpenTelemetry and Keeping Costs Sane
OpenTelemetry has become the default way to instrument services, and I'd use it for anything new. It separates how you collect telemetry from where it goes, so changing vendors no longer means re-instrumenting your code. Logs, metrics and traces share a common context, which means you can jump from a slow trace straight to its logs.
Run the OpenTelemetry Collector between your apps and your backend. It can batch, filter, add attributes and sample in one place, and you can change destinations without a deploy. Tail sampling is the feature that pays for it. Keep all errors and slow requests, and sample a small share of the rest, which can cut trace volume dramatically while keeping the traces you actually open.
Cardinality is the bill
Metric cost is driven by the number of unique label combinations. One label with a user ID can turn one time series into a million. Never put user IDs, request IDs or full URLs into metric labels. Use route templates such as /orders/:id, and put high-cardinality detail in traces and logs, where it belongs. Check your top metrics by series count each quarter, because this cost creeps up unnoticed.
Profiles and eBPF
Continuous profiling is becoming the fourth signal. A low-overhead profiler shows which functions use CPU in production, and that often finds savings no dashboard reveals. eBPF-based tools can collect network and system metrics without changing your code. That's handy for a quick view of a system you don't own, though it doesn't replace application-level traces.
Dashboards people use
Most dashboards are built once and never opened. Give each service one dashboard that answers one question: is it healthy, and if not, where's the problem? Start with the golden signals at the top, then dependencies, then detail. Keep dashboards in code with the service, so they stay current and get reviewed. If you run LLM features, add cost per request, token usage and model errors, since those are the numbers that surprise people. See agent observability for what changes with agents. Remember your own monitoring can fail too. Use an external uptime check, or a dead man's switch, so that you hear about it if the whole system goes quiet.