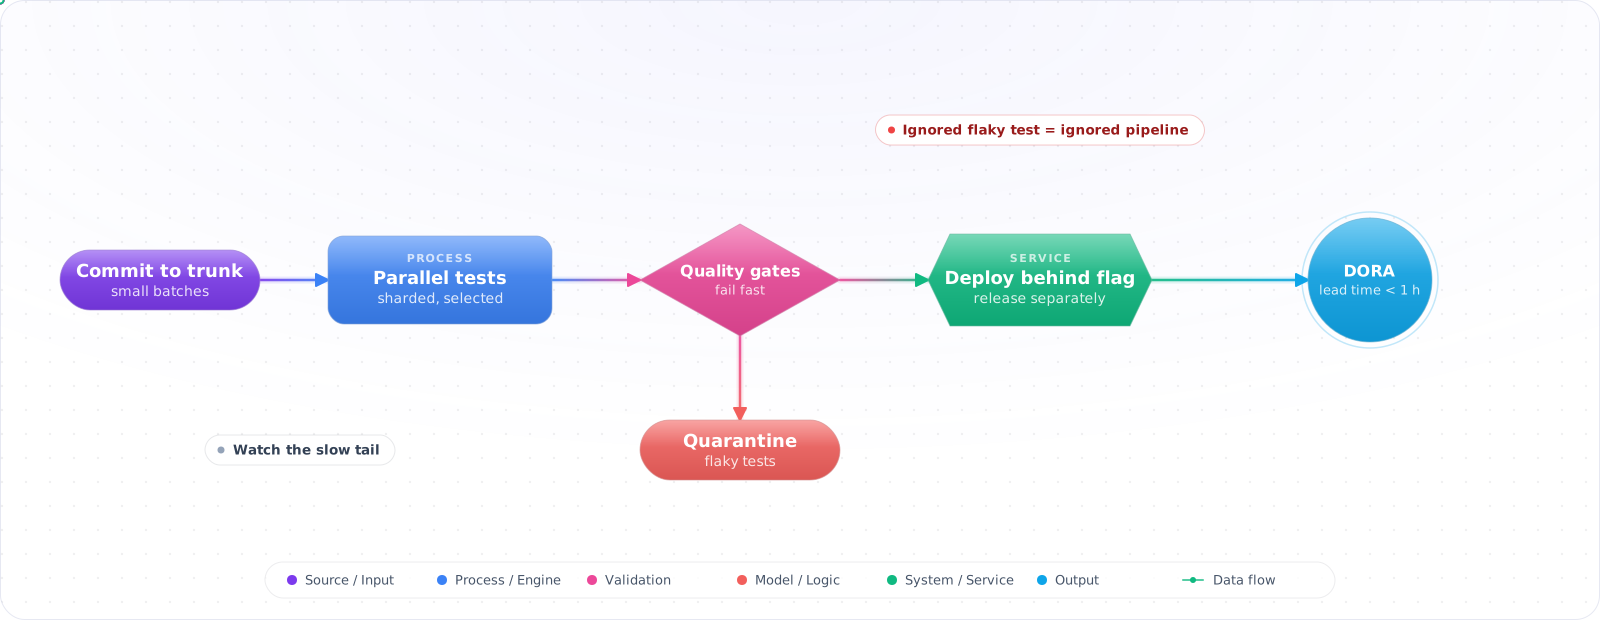
Start With One Simple Pipeline
While the whole pipeline finishes in a few minutes, one sequence of steps is fine, and anything cleverer is wasted effort. Design starts to matter when the wait is long enough that people stop trusting it, or stop waiting for it.
A CI/CD pipeline that takes 40 minutes to run isn't a pipeline — it's a deployment tax. Developers stop running it locally, stop reading the output, and merge with crossed fingers. Good pipeline design is about fast feedback: fail early, fail clearly, and only block on things that actually matter.
- Your pipeline runs everything sequentially when most jobs could run in parallel
- A flaky E2E test blocks deployments randomly, so the team ignores it
- You have no idea if your pipeline is getting faster or slower over time
- Your “quality gate” is “it compiles and tests pass” — nothing more
DORA metrics give you a quantified baseline. Pipeline topology and quality gate design give you a path to improve them.
DORA Metrics: The Baseline
DORA (DevOps Research and Assessment) is known for four delivery metrics that cover speed and stability together, which helps you avoid improving one by quietly giving up the other.
quadrantChart
    title Delivery performance (illustrative)
    x-axis Slow Deployment Frequency --> High Deployment Frequency
    y-axis High Change Failure Rate --> Low Change Failure Rate
    quadrant-1 Elite
    quadrant-2 High
    quadrant-3 Low
    quadrant-4 Medium
    Elite: [0.9, 0.9]
    High: [0.65, 0.75]
    Medium: [0.4, 0.45]
    Low: [0.2, 0.25]
The four metrics are below. DORA's benchmark values change between reports, so take them from the latest one:
- Deployment Frequency: How often you deploy to production
- Lead Time for Changes: Time from commit to running in production
- Change Failure Rate: Share of deploys that cause a production failure
- Time to Restore Service: How quickly you recover when something breaks
Check it: Work out last month's four numbers from your deploy and incident history. If you can't, that's the first thing to instrument.
Pipeline Topology
# Principles:
# 1. Fail fast — cheapest checks first
# 2. Parallelise where possible — lint and test run independently
# 3. Cache aggressively — don't reinstall deps on every run
# 4. Artifact handoff — build once, deploy that exact artifact

# Example job graph for a Node.js service (timings are illustrative):
#
# [pr-check] ─┬─ [lint + typecheck] (2 min)
#             ├─ [unit tests + coverage] (3 min)
#             └─ [build] (4 min)
#
# On main merge:
# [integration tests] (5 min)
#     └─ [docker build + push] (3 min)
#          └─ [deploy staging] (2 min)
#               └─ [smoke tests] (1 min)
#                    └─ [deploy production] (2 min, manual approval gate)

jobs:
  # Stage 1: Fast static checks (no runtime needed)
  lint-typecheck:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v7
      - uses: pnpm/action-setup@v6         # setup-node needs pnpm installed first
        with: { version: 10 }
      - uses: actions/setup-node@v7
        with: { node-version: '24', cache: 'pnpm' }
      - run: pnpm install --frozen-lockfile
      - run: pnpm lint && pnpm typecheck

  # Stage 1 (parallel): Tests with coverage gate
  test:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v7
      - uses: pnpm/action-setup@v6         # setup-node needs pnpm installed first
        with: { version: 10 }
      - uses: actions/setup-node@v7
        with: { node-version: '24', cache: 'pnpm' }
      - run: pnpm install --frozen-lockfile
      - run: pnpm test --coverage
      - name: Enforce coverage threshold
        run: |
          node -e "
            const c = require('./coverage/coverage-summary.json').total;
            const fail = (n, t) => { if (c[n].pct < t) { console.error(n + ': ' + c[n].pct + '% < ' + t + '%'); process.exit(1); } };
            fail('lines', 80); fail('branches', 75);"

  # Stage 2: Build (only after stage 1 passes)
  build:
    needs: [lint-typecheck, test]
    runs-on: ubuntu-latest
    permissions:
      contents: read
      packages: write
    outputs:
      image: ${{ steps.push.outputs.imageid }}
    steps:
      - uses: actions/checkout@v7
      - uses: docker/login-action@v4
        with:
          registry: ghcr.io
          username: ${{ github.actor }}
          password: ${{ secrets.GITHUB_TOKEN }}
      - uses: docker/build-push-action@v7
        id: push
        with:
          push: true
tags: ghcr.io/myorg/api:${{ github.sha }}Check it: Look at the first failure in ten recent runs, and how long it took to appear. Lint and unit failures should show within the first couple of minutes.
Quality Gates
A quality gate is a hard stop: the pipeline fails if a metric falls below a threshold. Soft warnings that don't block deploys are easy to ignore.
# Example quality gates in CI:

# 1. Test coverage
- run: pnpm test --coverage --coverageThreshold='{"global":{"lines":80,"branches":75}}'

# 2. Bundle size (prevent accidental bloat)
- name: Check bundle size
  uses: andresz1/size-limit-action@v1
  with:
    github_token: ${{ secrets.GITHUB_TOKEN }}
    # .size-limit.js configures thresholds — fails if exceeded

# 3. Dependency audit (no high/critical CVEs)
- run: pnpm audit --audit-level=high

# 4. Performance budget (Lighthouse CI)
- uses: treosh/lighthouse-ci-action@v10
  with:
    budgetPath: ./budget.json
uploadArtifacts: trueCheck it: Push a change that drops coverage below the threshold. The pipeline should fail, not warn.
Flaky Test Management
Flaky tests are the silent killers of pipeline trust. Once developers learn a failure might be flaky, they start assuming everything is flaky — and stop taking failures seriously.
# Quarantine pattern: move flaky tests to a separate job
# that doesn't block the merge, but still tracks failure rate

jobs:
  test:
    runs-on: ubuntu-latest
    steps:
      - run: pnpm test         # Only stable tests — blocks merge

  test-flaky:
    runs-on: ubuntu-latest
    continue-on-error: true   # Doesn't fail the workflow
    steps:
      - run: pnpm test:flaky   # Quarantined flaky tests
      # But: alert/notify if failure rate > threshold
      - if: failure()
        run: |
          curl -X POST ${{ secrets.SLACK_WEBHOOK }} \
-d '{"text": "Flaky test failure: ${{ github.run_id }}"}'Check it: Count the reruns in the last hundred pipeline runs. Then list the quarantined tests with their owners. Any with no owner will stay there.
Measuring Your Pipeline
# Record job timings and publish to your observability stack
# GitHub Actions exposes duration via the API, or use this pattern
# (it assumes an earlier step with the id start_time):

- name: Record pipeline duration
  if: always()  # Run even if previous steps failed
  run: |
    DURATION=$(($(date +%s) - ${{ steps.start_time.outputs.time }}))

    # Push metric to your TSDB (Datadog, InfluxDB, etc.)
    curl -X POST "https://api.datadoghq.com/api/v1/series" \
      -H "DD-API-KEY: ${{ secrets.DD_API_KEY }}" \
      -d '{
        "series": [{
          "metric": "ci.pipeline.duration_seconds",
          "points": [['$(date +%s)', '$DURATION']],
          "tags": ["job:${{ github.job }}", "repo:${{ github.repository }}"]
        }]
      }'
Sharding, Selection, and the Slow Tail
Once dependencies are cached and independent jobs run in parallel, the test suite is usually what is left. Three techniques keep it from growing with the codebase.
- Shard the suite. Split tests across several runners and balance the shards by recorded duration, not by file count. Ten runners at four minutes each cost about the same as one runner at forty, and the feedback arrives ten times sooner.
- Run what a change can affect. In a monorepo, use the dependency graph to build and test only the packages downstream of the changed files. Keep a scheduled full run so that a mistake in the selection logic is caught within a day.
- Measure the tail. Track the median and the 95th percentile duration for each stage. The median shows the normal case. The 95th percentile shows queueing, cold caches and retries, and it is the experience people remember and plan around.
Set a budget, for example ten minutes from push to result on a pull request, and treat a breach as a defect to fix. A pipeline with no budget gets a little slower with every change.
Try It on Your Own System This Week
Three checks on a pipeline you already run, about an hour in total:
- Time your pipeline from push to result. Use the 95th percentile as well as the median. The slow runs are the ones people plan around.
- Find the job that fails most often. If it's a flaky test, quarantine it today and give it an owner.
- Check whether production gets the image that staging tested. Compare the digests. If they differ, you tested something else.
Pitfalls
Caching test artifacts between runs
Cache the package manager's store by lockfile hash. Don't cache test output or build artifacts between runs of the same job — they should be reproducible from source. The exception: test coverage history (for trending) should persist to an external store.
Coverage thresholds without baseline
Enforcing 80% coverage on a codebase that has 40% coverage today will make the pipeline red immediately. Start below your current level and ratchet up over time.
E2E tests in the hot path
E2E tests belong after staging deploy — not before. They're slow, environment-dependent, and often flaky. Running them before merge adds that time to every PR cycle. Test the integration contract in unit/integration tests; validate end-to-end behaviour on the staging environment.
Securing the Pipeline
A CI pipeline has credentials to production, runs third-party code, and gets far less review than the application itself. That makes it one of the most attractive targets in your company. The 2025 compromises of popular GitHub Actions and npm packages showed how fast this spreads: one poisoned dependency can read every secret a job has access to.
Start with secrets. Replace long-lived cloud keys with OIDC, so that a job gets a short-lived token scoped to one repository and branch. Pin third-party actions to a full commit SHA, since a tag can be moved by whoever controls that repository. Set permissions: contents: read by default, and grant more only to the jobs that need it. Keep untrusted code away from secrets: a workflow that runs on a pull request from a fork must never have access to deploy credentials, and pull_request_target is the classic way to get that wrong.
Build provenance is the next step. Generate an SBOM and sign your images, so that a deploy can verify what it's running and where it came from. Tools like Cosign and GitHub's artifact attestations make this practical, and SLSA gives you a framework to measure progress.
Pipelines for AI code
Agent-written code raises the volume, so the pipeline has to do more of the checking. Consider gates that flag new dependencies and changed test assertions, since those are where agent mistakes tend to hide. For LLM features, add an eval stage that runs on prompt and model changes, as well as on code changes, and compares against a baseline. Keep that stage cheap on pull requests with a small smoke set, and run the full suite nightly. An AI eval is a test with a cost, so budget for it.
Fast feedback beats perfect feedback
Developers stop trusting slow pipelines. Aim for under ten minutes to a useful signal. Run lint and unit tests first, cache dependencies aggressively, and split test jobs. Treat flaky tests as bugs: quarantine them with an owner, and fix or delete them on a deadline. A pipeline that's red for no reason teaches people to ignore red.