Start by Asking Directly
For a lookup or a simple classification, ask for the answer and nothing else. Reasoning adds tokens there and changes nothing. Asking for the steps earns its place when the answer depends on several of them, such as dates, rules and exceptions.
Ask a model whether a return started on 5 April falls inside a 30-day window from a 9 March delivery, and ask for just "yes" or "no". It will often get it wrong. Ask it to work through the dates first and it usually gets it right. Same model, same question; the only difference is that it had room to do the arithmetic before committing to an answer.
That is chain-of-thought: the model writes intermediate steps before its conclusion, so the answer is generated after the reasoning instead of in place of it. It costs output tokens and latency, and on today's reasoning models it is largely built in. On smaller, non-reasoning models it is still one of the cheapest accuracy gains there is, provided you keep the final answer separate and check whatever can be checked.
- Your LLM gets multi-step arithmetic or logic problems wrong, even on simple cases
- The model makes classification decisions that seem right until you trace the reasoning
- You need the model to debug code or explain a decision in auditable steps
- Your agent makes confident wrong answers on tasks that require decomposition
Zero-shot CoT is a single appended sentence that improved accuracy on reasoning tasks in the original studies, with zero additional examples. Test it on your model, because current reasoning models often do this work unprompted.
Zero-Shot CoT
The simplest form: append “Let's think step by step” to any prompt. This instruction activates reasoning traces in models trained with CoT examples (which includes most instruction-tuned models today). No examples needed.
flowchart LR
    direct["Direct answer
(no reasoning)
Prompt → Answer
Fast, less accurate"]
    zeroCoT["Zero-shot CoT
Append 'step by step'
Prompt → Reasoning → Answer
Slower, more accurate"]
    fewCoT["Few-shot CoT
Examples with reasoning
Examples + Prompt → Reasoning → Answer
Best for complex tasks"]

    direct -->|add 'step by step'| zeroCoT
    zeroCoT -->|add examples| fewCoT
// Zero-shot CoT: one phrase changes accuracy significantly

// ❌ Direct — model jumps to conclusion, more error-prone
const directPrompt = `
An API processes 240 requests per minute.
During a traffic spike, the rate triples for 5 minutes then drops to 180 req/min.
If each request uses 2KB of memory and you have 512MB available,
do you have enough memory during the spike?
`;

// ✅ Zero-shot CoT — model reasons through intermediate steps
const cotPrompt = `
An API processes 240 requests per minute.
During a traffic spike, the rate triples for 5 minutes then drops to 180 req/min.
If each request uses 2KB of memory and you have 512MB available,
do you have enough memory during the spike?

Think through this step by step.
`;

// Model output with CoT:
// Step 1: Normal rate = 240 req/min, spiked rate = 240 × 3 = 720 req/min
// Step 2: Memory during spike = 720 × 2KB = 1,440KB = 1.44MB per minute of requests
// Step 3: But requests are concurrent — how many at once? Need avg response time...
// [model identifies the ambiguity and addresses it]
// Final answer: [more accurate than direct]Check it: Take ten multi-step questions with known answers. Run them with and without the step-by-step instruction on your model, and count the difference.
Few-Shot CoT
// Few-shot CoT: examples with full reasoning traces
// Most effective for tasks with a consistent reasoning pattern

const fewShotCoTPrompt = `
You are a code review assistant. For each change, reason through its correctness before deciding.

Example 1:
Code change:
  const user = await db.users.findOne(userId);
  return user.email;

Reasoning:
- findOne could return null if userId doesn't exist
- Accessing .email on null will throw a TypeError at runtime
- This is missing a null check

Decision: REJECT — add null check: if (!user) throw new Error('User not found')

Example 2:
Code change:
  const users = await db.users.findMany({ limit: 100 });
  return users.map(u => u.email);

Reasoning:
- findMany returns an empty array if no results, never null
- limit: 100 prevents unbounded queries
- map on empty array returns empty array safely

Decision: APPROVE — looks safe

Now review this change:
Code change:
  const config = JSON.parse(process.env.APP_CONFIG);
  return config.apiKey;
`;
// Model reasons: JSON.parse throws on invalid JSON, env var could be undefined...
// Decision: REJECT — missing error handling
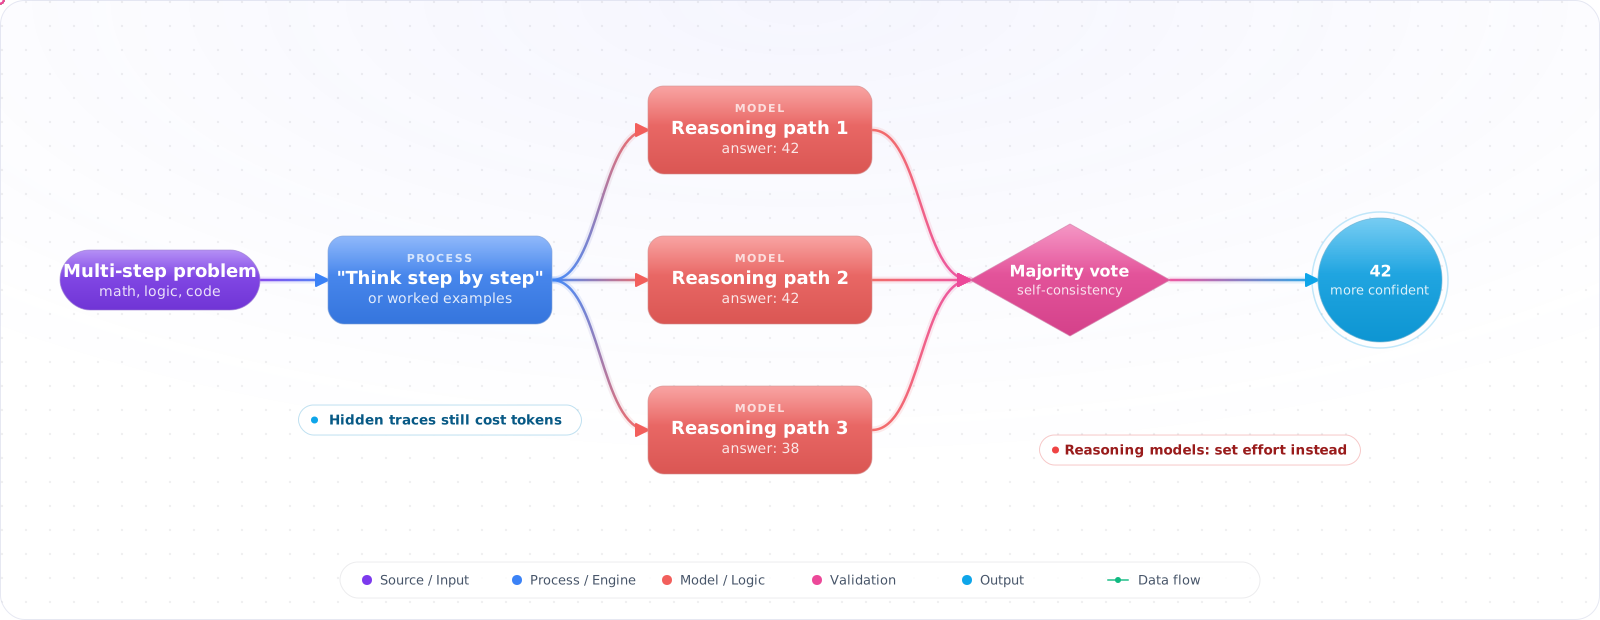
Self-Consistency
// Self-consistency: generate N reasoning paths, take majority answer
// Improves accuracy further — like an ensemble for reasoning tasks

async function selfConsistentAnswer(
  prompt: string,
  n = 5
): Promise<string> {
  // Generate N independent reasoning paths with temperature > 0
  const responses = await Promise.all(
    Array.from({ length: n }, () =>
      openai.chat.completions.create({
        model: 'gpt-6-luna', reasoning_effort: 'none',  // sampling params need reasoning off
        messages: [{ role: 'user', content: `${prompt}\n\nThink step by step.` }],
        temperature: 0.7,  // Non-zero for diversity
      })
    )
  );

  const answers = responses.map(r => {
    const text = r.choices[0].message.content ?? '';
    // Extract final answer from CoT output
    // Common patterns: "Therefore: X", "Final answer: X", last sentence
    return extractFinalAnswer(text);
  });

  // Majority vote
  const counts = new Map<string, number>();
  for (const answer of answers) {
    counts.set(answer, (counts.get(answer) ?? 0) + 1);
  }

  return [...counts.entries()].sort((a, b) => b[1] - a[1])[0][0];
}

// When to use self-consistency:
// - High-stakes decisions where accuracy outweighs cost (N × API calls)
// - Tasks with discrete answers (classification, calculation, yes/no)
// - When you see high variance in single-pass answersCheck it: Run one hard question five times and compare the final answers. If they disagree, a single call was never reliable for it.
CoT for Code Tasks
// Ask the model to explain before implementing
// Catches design errors before they become code errors

const codingPrompt = `
Task: Write a function that deduplicates an array of objects by a given key,
keeping the last occurrence of each duplicate.

Before writing code:
1. State your approach and data structure choice
2. Identify edge cases you'll handle
3. Note any performance considerations

Then write the implementation.
`;

// Model output structure:
// Approach: Use a Map, iterate forward, overwrite on duplicate key (last-wins)
// Edge cases: empty array, key not present on some objects, undefined values
// Performance: O(n) time, O(n) space
//
// function dedupeByKey<T>(arr: T[], key: keyof T): T[] {
//   const seen = new Map<unknown, T>();
//   for (const item of arr) {
//     seen.set(item[key], item);  // overwrite = last wins
//   }
//   return [...seen.values()];
// }

// The pre-code reasoning step surfaces edge cases before they're embedded in code
// Significantly reduces bug rate compared to asking for direct implementation
CoT on Models That Already Reason
Chain-of-thought was invented for models that answered in a single pass. The current frontier models do not: the GPT-6 family, the Claude 5.5 models and current Gemini models all reason internally before they answer, and you control how much with a setting (reasoning effort on OpenAI, effort with adaptive thinking on Anthropic, thinking level on Gemini). That changes what the technique is for.
| Situation | What to do |
|---|---|
| Reasoning model, hard problem | Raise the effort setting. Adding "think step by step" on top is redundant and can make the answer longer without making it better. |
| Reasoning model, you need to see the steps | Ask for the working in the answer itself ("show the calculation, then the result"). The internal reasoning is not returned in full, so do not rely on it for an audit trail. |
| Reasoning switched off, or a small or self-hosted model | Classic CoT still earns its tokens. This is where zero-shot and few-shot CoT give the largest lift. |
| Simple lookup or classification | Neither. Use low effort and no CoT; you are paying for reasoning tokens that change nothing. |
Two details catch people out. Reasoning tokens are billed as output tokens and count against the output cap, so a smallmax_completion_tokens can return an empty answer because the budget went on thinking. And self-consistency needs variety between runs: on OpenAI that means a model where sampling is allowed (GPT-6 Luna with reasoning off), because the reasoning tiers rejecttemperature.
Check it: On a reasoning model, take the step-by-step instruction out of the prompt, and compare quality and output tokens on your eval set.
Pitfalls
CoT on simple lookup tasks
Adding “think step by step” to “What is the capital of France?” adds tokens without adding accuracy. CoT helps reasoning tasks — multi-step math, logic, code analysis, decisions with trade-offs. For factual retrieval, direct prompts are faster and equally accurate.
Hallucinated reasoning steps
A model can produce confident, plausible-looking reasoning steps that are factually wrong — and then correctly derive the answer from the wrong premises. Always verify factual claims in the reasoning chain, especially for domain-specific knowledge. CoT makes the reasoning inspectable, but inspection is still your job.
Wrong final answer despite correct steps
The model can reason correctly up until the final step and then make a non sequitur conclusion. For high-stakes tasks, validate the final answer against the reasoning chain independently. Self-consistency helps here — if 4 of 5 paths reach the same answer through different reasoning, that's a useful signal, but not a calibrated probability, because separate paths can share the same mistake.
Try It on Your Own System This Week
Three checks on a prompt that asks for reasoning, about an hour in total:
- Find where your code reads the final answer. It should be a field of its own, placed after the reasoning.
- Search your logs for empty responses. A cap sized for the visible answer can run out during thinking.
- Pick one answer and check a step in code. A rationale is a debugging aid, and it can be wrong.
What Reasoning Models Change in Practice
"Let's think step by step" was once the highest-value line in prompting. On today's reasoning models, it's often unnecessary, since the model already reasons before it answers, and asking again can waste tokens or even reduce quality. Current models from OpenAI and Google, and Anthropic's adaptive thinking, handle this with a setting. So the control has moved from your prompt to a parameter: reasoning effort.
Here's how I think about it now. If you're on a reasoning model, don't ask for step-by-step reasoning in the prompt. Set effort according to the task, and ask only for the final output you need. Providers advise against trying to control or extract the hidden reasoning, which can be summarised or withheld, so don't build a feature that depends on reading it.
Where explicit reasoning still earns its place
Chain-of-thought hasn't disappeared. It's still valuable in three situations:
- On small or open-weight models, where it improves accuracy on multi-step problems.
- When a person needs to check the reasoning, so it has to be part of the output. Ask for a short rationale after the answer, or in a named field.
- On models with reasoning turned off, for low-latency or cost reasons.
For the second case, structured output works nicely: have reasoning as a field placed before answer in the schema. The model writes its reasoning first, and your code can log it and show only the answer to the user.
Reasoning isn't proof
A clear explanation doesn't mean the answer is right. Models can produce a plausible explanation for a wrong conclusion, and research has shown that stated reasoning doesn't always reflect how the model reached its answer. So treat a rationale as a debugging aid, and not as evidence of correctness. For anything important, verify with code, a calculation or a retrieval check. Asking a model to write and run code for arithmetic beats asking it to reason through the numbers.
Costing it properly
Reasoning tokens are billed as output, and they count against your output cap. An output limit sized for the visible answer can run out during thinking, which gives you an empty response with no error. Leave room, and watch for that failure in your logs. Higher effort also raises latency, and it can raise cost several times over. Try each effort level on your eval set and find the point where quality stops improving. For a lot of production work, that point is lower than people assume.