

Beyond Text Output
The first time you need a model to do something (look up an order, run a calculation, open a ticket), the tempting approach is to ask it to describe the action as JSON and parse the reply. It works in testing. In production the replies arrive with prose around the JSON, renamed fields, and arguments the user never mentioned.
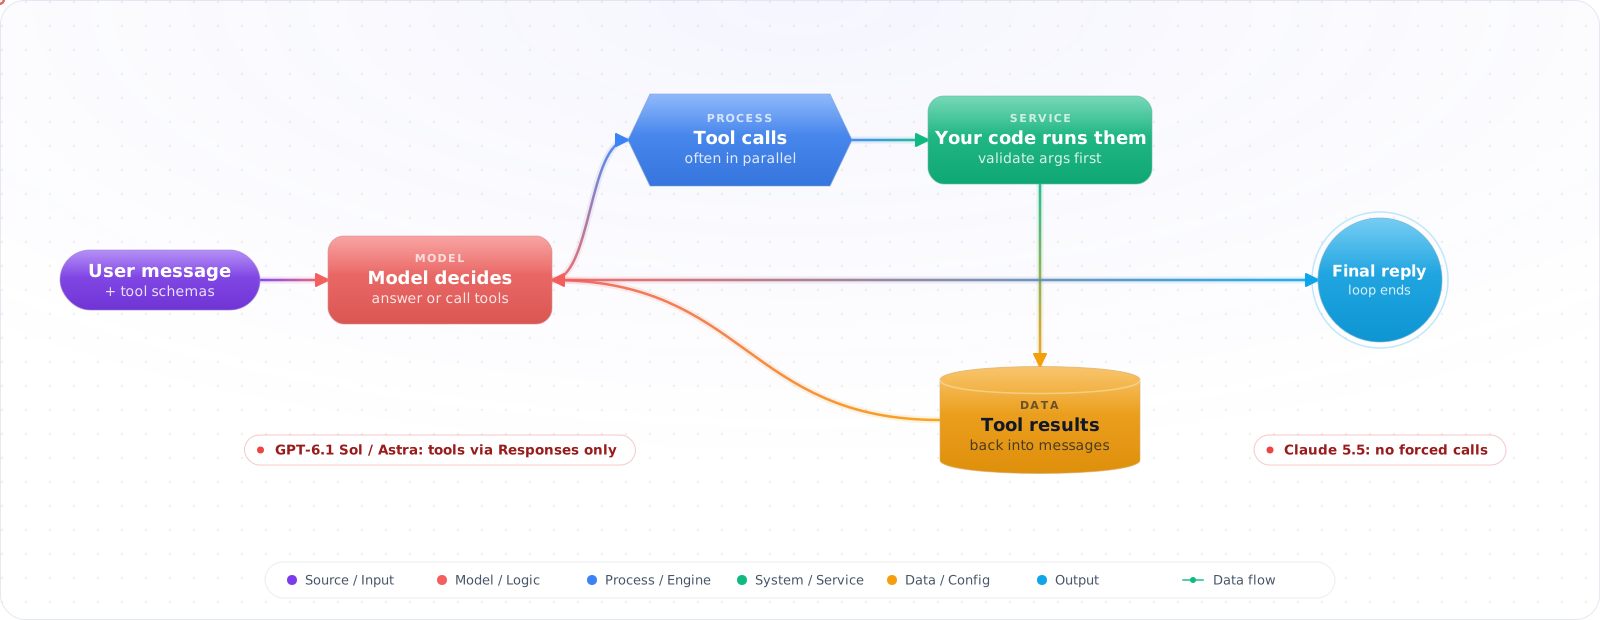
Function calling is the fix: you describe your functions as typed tools, and the model returns structured calls for your code to validate and run. The model never executes anything; your loop does. That loop is the part to get right: schemas, validation, errors fed back to the model, parallel calls, step limits, and the provider differences that break portable code.
- You're regex-parsing LLM outputs to extract structured data, and it breaks on edge cases
- You have an agent loop that sometimes calls the wrong tool because the descriptions are vague
- You need the model to trigger external actions (database query, API call) based on conversation context
- Your LLM sometimes calls a tool with invalid arguments and your code throws at runtime
Well-defined tool schemas eliminate the parsing layer and make LLM-to-function calls as reliable as typed function signatures.
Tool Schema Design
The model selects tools and generates arguments based entirely on your schema descriptions. Bad descriptions mean wrong tool selection. Treat tool descriptions like API documentation — write them for someone who can't see your code.
sequenceDiagram
    participant User
    participant LLM
    participant App
    participant DB

    User->>LLM: "Show me orders from last week over $500"
    LLM->>App: tool_call: searchOrders({minAmount:500, dateFrom:"2025-01-13"})
    App->>DB: SELECT * FROM orders WHERE ...
    DB->>App: [{id: 123, amount: 750, ...}]
    App->>LLM: tool_result: [{id:123, ...}, {id:456, ...}]
    LLM->>User: "Found 2 orders: order #123 for $750..."
import OpenAI from 'openai';

const openai = new OpenAI();

// Define tools with precise descriptions — the model reads these
const tools: OpenAI.Chat.Completions.ChatCompletionTool[] = [
  {
    type: 'function',
    function: {
      name: 'searchOrders',
      description: `Search customer orders by date range and amount.
        Use when the user asks about orders, purchases, or transactions.
        Returns an array of order objects with id, amount, status, and date.`,
      parameters: {
        type: 'object',
        properties: {
          minAmount: {
            type: 'number',
            description: 'Minimum order amount in USD. Omit if no minimum.',
          },
          maxAmount: {
            type: 'number',
            description: 'Maximum order amount in USD. Omit if no maximum.',
          },
          dateFrom: {
            type: 'string',
            description: 'Start date in ISO 8601 format (YYYY-MM-DD). Omit for all dates.',
          },
          dateTo: {
            type: 'string',
            description: 'End date in ISO 8601 format (YYYY-MM-DD). Omit for today.',
          },
          status: {
            type: 'string',
            enum: ['pending', 'processing', 'shipped', 'delivered', 'cancelled'],
            description: 'Filter by order status. Omit to return all statuses.',
          },
        },
        required: [],  // All params optional — model decides what to include
        additionalProperties: false,
      },
    },
  },
];
The Conversation Loop
type Message = OpenAI.Chat.Completions.ChatCompletionMessageParam;

// Tool implementations
const toolHandlers: Record<string, (args: unknown) => Promise<unknown>> = {
  searchOrders: async (args) => {
    // CRITICAL: validate args before executing
    const parsed = SearchOrdersSchema.parse(args); // Zod validation
    return db.orders.findMany({
      where: {
        amount: { gte: parsed.minAmount, lte: parsed.maxAmount },
        createdAt: { gte: parsed.dateFrom, lte: parsed.dateTo },
        status: parsed.status,
      },
    });
  },
};

async function runAgentLoop(userMessage: string): Promise<string> {
  const messages: Message[] = [
    { role: 'system', content: 'You are a helpful order management assistant.' },
    { role: 'user', content: userMessage },
  ];

  // Loop until the model stops calling tools
  while (true) {
    const response = await openai.chat.completions.create({
      model: 'gpt-6-luna', reasoning_effort: 'none',
      messages,
      tools,
      tool_choice: 'auto',  // model decides when to call tools
    });

    const message = response.choices[0].message;
    messages.push(message);

    // No tool calls → final text response
    if (!message.tool_calls) {
      return message.content ?? '';
    }

    // Execute each tool call
    for (const toolCall of message.tool_calls) {
      const args = JSON.parse(toolCall.function.arguments);
      const result = await toolHandlers[toolCall.function.name]?.(args) ?? 'Tool not found';

      // Append tool result to conversation
      messages.push({
        role: 'tool',
        tool_call_id: toolCall.id,
        content: JSON.stringify(result),
      });
    }
    // Loop continues — model sees tool results and decides next step
  }
}
Parallel Tool Calls
// When the model calls multiple tools in one turn, execute them in parallel
// This is a performance optimisation — the model already decided to call all of them

const response = await openai.chat.completions.create({
  model: 'gpt-6-luna', reasoning_effort: 'none',
  messages,
  tools,
});

const toolCalls = response.choices[0].message.tool_calls ?? [];

// Execute all tool calls in this turn concurrently
const toolResults = await Promise.all(
  toolCalls.map(async (toolCall) => {
    const args = JSON.parse(toolCall.function.arguments);
    const result = await toolHandlers[toolCall.function.name]?.(args);
    return {
      role: 'tool' as const,
      tool_call_id: toolCall.id,
      content: JSON.stringify(result),
    };
  })
);

messages.push(response.choices[0].message, ...toolResults);
Controlling Tool Use
// tool_choice controls whether and which tools the model uses

// auto — model decides (default)
tool_choice: 'auto'

// none — never use tools (text-only response)
tool_choice: 'none'

// required — must call at least one tool
tool_choice: 'required'

// specific function — must call this exact function
tool_choice: { type: 'function', function: { name: 'searchOrders' } }

// Use 'required' for structured data extraction tasks:
// "Extract the key details from this support ticket"
// + required tool: extractTicketDetails
// Guarantees structured output, never returns unstructured text
Provider Rules That Break Portable Tool Code
The tool-calling loop is the same everywhere, but the request rules are not, and they changed with the 2026 model generations. Code that ran unchanged against GPT-4o and Claude 3.5 now fails in three specific places.
| What you send | OpenAI (GPT-6 family) | Anthropic (Claude 5.5 models) |
|---|---|---|
| Tools on the chat endpoint | GPT-6.1 Sol and Astra accept tools only through the Responses API. Chat Completions tool calling works on GPT-6 Luna with reasoning effort set to none. | Works on the Messages API for every tier. |
| Forcing a tool call | tool_choice: 'required' or a named function is still accepted. | Forced tool choice (any or a named tool) is rejected on Fable 5.1, Opus 5.5 and Sonnet 5.5. Only auto and none work. |
| Sampling parameters | temperature and top_p are rejected unless reasoning effort is none. | Non-default sampling values are rejected on the current models. |
The practical consequence: do not build your design around forcing a call. If you were forcing a tool only to get JSON back, use structured outputs instead, which every current provider supports. If you genuinely need the model to call one specific tool, keeptool_choice on auto, say so in the instructions, and validate that the call happened before you continue.
Strict mode: make argument validation the provider's job
Both OpenAI and Anthropic let you mark a tool definition as strict. In strict mode the arguments are guaranteed to match your JSON Schema, so the missing-field and wrong-type failures disappear. The cost is a tighter schema: every property must be listed as required, andadditionalProperties must be false. Express an optional field as a union with null rather than leaving it out ofrequired.
const searchOrders = {
  type: 'function',
  name: 'searchOrders',
  description: 'Find orders for a customer. Use when the user asks about order status.',
  strict: true,
  parameters: {
    type: 'object',
    properties: {
      customerId: { type: 'string' },
      status: { type: ['string', 'null'], enum: ['open', 'shipped', 'cancelled', null] },
    },
    required: ['customerId', 'status'],   // strict mode: every property is required
    additionalProperties: false,          // strict mode: no extra keys
  },
};
Strict mode guarantees the shape, not the meaning. A schema-valid customerId can still belong to a different user, so the authorisation check in your handler stays.
Pitfalls
Trusting model-generated arguments directly
Never execute a tool call with unvalidated model output. The model can hallucinate argument values, generate SQL fragments, produce out-of-range numbers, or construct paths that traverse directories. Always validate against a schema (Zod, Joi, AJV) before passing to your handler. Treat LLM-generated arguments like untrusted user input.
Overloading a single tool
A callDatabase(sql: string) tool that accepts raw SQL is a security and reliability disaster. Use narrow, typed tools with explicit parameters. The model should be selecting typed parameters — not constructing strings that your code interprets.
Missing tool call IDs in history
Every tool_calls entry in the assistant message must have a corresponding tool message with the matchingtool_call_id. Missing a tool result causes an API error on the next turn. If a tool fails, still append a tool message with an error description so the model can gracefully handle it.