

Keeping a Long Conversation on Track
Short-term memory is everything the agent "remembers" within a single conversation: prior turns, tool outputs, scratchpad notes, and the running plan. Get it wrong and you either blow the context window (and the bill) or you drop the one fact the next turn needs. There is no universal answer — the right strategy depends on conversation length, latency budget, and how often the agent re-references old facts.
- Your agent forgets the user's name by turn 10
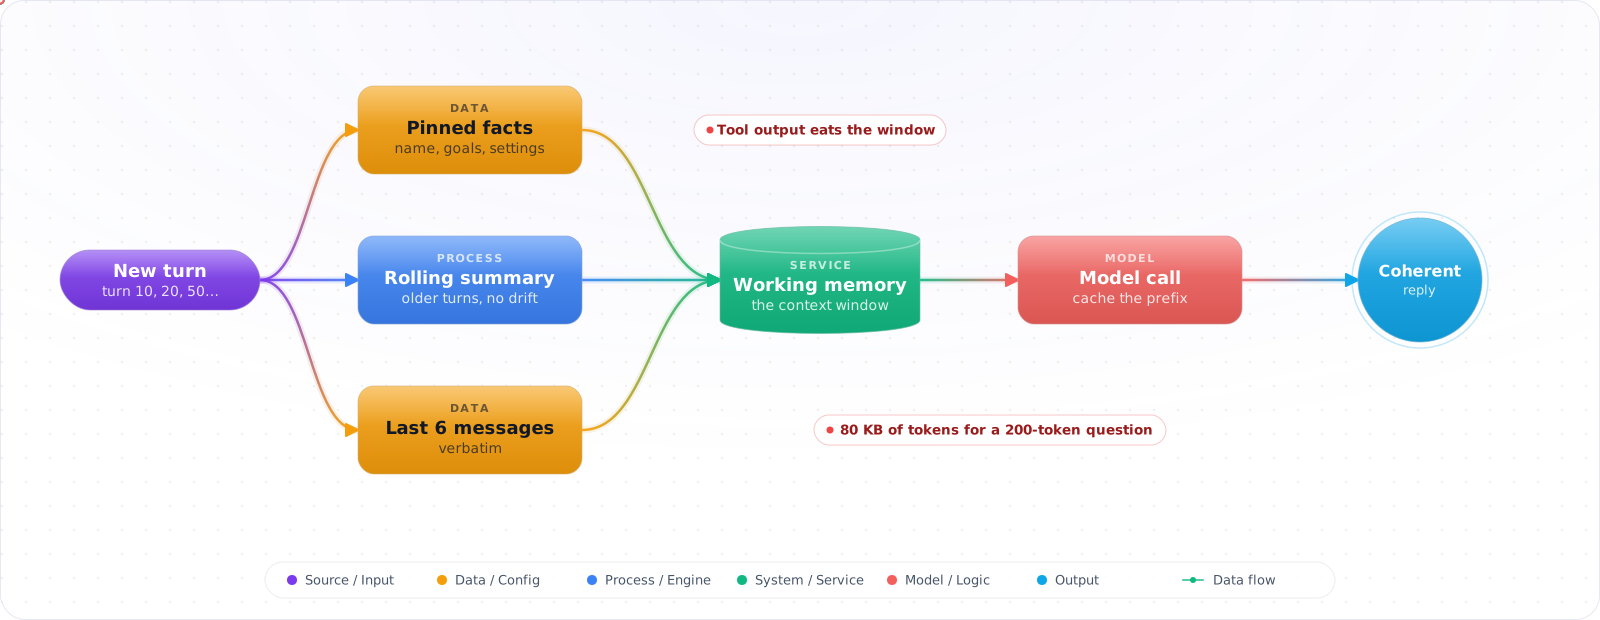
- You pay for 80 KB of tokens to answer a 200-token question
- Trimming history breaks tool-call/tool-result pairs and the next call hard-errors
The Four Strategies
- Full history — append-only. Simple, correct, expensive. Works up to ~20 turns on a 128K model.
- Sliding window — keep the last N messages. Cheap and stateless, but loses early facts.
- Rolling summary — every K turns, summarise the older half and drop it. Good cost/recall trade-off.
- Hybrid (summary + recent + pinned)— a permanent "facts about user" block + a running summary + the last 6 messages verbatim. This is what most production agents converge on.
flowchart LR
    R[Raw turn N] --> A{Window full?}
    A -- no --> H[Append to history]
    A -- yes --> S[Summarise oldest 50%]
    S --> P[Update pinned facts]
    P --> H
    H --> C[Compose prompt:<br/>pinned + summary + recent 6]
The Tool-Call Trap
OpenAI, Anthropic, and Azure all require that every tool_call message be followed by a matching tool message with the same tool_call_id— or the API rejects the request. Naive trimming ("drop the oldest 4 messages") breaks this invariant constantly. The fix: trim by turn boundary, never by message count.
function trimToWindow(messages: Msg[], maxTokens: number): Msg[] {
  // Group into turns: user → (assistant + tool_call + tool_result)+
  const turns = groupIntoTurns(messages);
  let total = 0;
  const kept: Msg[] = [];
  for (const turn of turns.reverse()) {
    const t = estimateTokens(turn);
    if (total + t > maxTokens) break;
    kept.unshift(...turn);
    total += t;
  }
  return kept;
}
Pinned Facts: The Cheapest Win
A 200-token "system facts" block at the top of every request is almost free at provider cache prices and removes 80% of the "forgets the user's name" complaints. Update it via a small extraction call every N turns:
// Run every 5 turns, non-blocking
const facts = await llm.extract({
  system: "Extract durable facts (name, role, preferences, constraints).",
  messages: lastTurns,
  schema: factsSchema,
});
state.pinnedFacts = merge(state.pinnedFacts, facts);
Rolling Summaries Without Drift
Each summary is generated from the previous summary plus the new chunk, not from scratch. This keeps cost O(1) per turn but means errors compound. Mitigate by:
- Re-summarising from raw history every 50 turns (the "refresh").
- Constraining the summariser with a strict schema: decisions, open questions, user preferences.
- Logging the raw history so you can replay if the summary clearly drifted.
Provider Caching Changes the Maths
Anthropic prompt caching and OpenAI's automatic prefix caching can drop the cost of a stable prefix by 50–90%. If your system prompt + pinned facts + summary live at the top, they are cached, and only the rolling tail costs full price. This shifts the optimal strategy from "summarise aggressively" to "keep a stable prefix and append".
Tool Outputs Eat the Window
In agent conversations, user messages are rarely the problem. Tool results are. One search call returns forty kilobytes of JSON, one file read returns a whole log, and after three such calls most of the context window is data the model looked at once and will never need verbatim again. Trimming by turn keeps the conversation valid but still carries all of it.
Shrink tool results when you store them, not only when you trim. Keep the full result outside the prompt, in your own store, keyed by a handle. Put a compact version in the conversation: the fields the agent asked for, a row count, the first few items, and the handle. If the agent needs more, it calls a tool to fetch it by handle. A practical rule I start with is that any tool result over a couple of thousand tokens gets this treatment, and results older than a few turns are replaced by their one-line summary.
function compactToolResult(result: unknown, handle: string): string {
  const rows = Array.isArray(result) ? result : [result];
  return JSON.stringify({
    handle,                       // full result stored server-side under this key
    total: rows.length,
    preview: rows.slice(0, 5),
    note: rows.length > 5 ? 'Call fetch_result with the handle for more.' : undefined,
  });
}
Letting the Provider Hold State
Some provider APIs can now keep conversation state on their side: you send a reference to the previous response instead of the full history, and some offer automatic clearing of old tool results. That removes a lot of plumbing and works well with prefix caching. The trade-offs are control and data handling. You no longer decide exactly what the model sees each turn, conversation data is retained by the provider under its retention terms, and moving to another provider means rebuilding state. I use provider-side state for prototypes and short-lived sessions, and keep my own history store for anything that has to be audited, replayed or moved.
Measuring Whether Memory Works
Memory strategies fail quietly; the agent just becomes a little more forgetful. Track a few numbers per conversation: prompt tokens per turn (it should plateau, not climb), how often summaries are refreshed, and how often users repeat information they already gave, which you can detect with a cheap classifier. Add recall tests to your evaluation set: plant a fact in turn 3 of a scripted conversation and ask about it in turn 40. If that test fails after a change to the summariser or the trimming rules, you have found the regression before your users did.
Production Checklist
- Always trim by turn boundary, never by message count.
- Estimate tokens with the provider's tokenizer (
tiktoken,@anthropic-ai/tokenizer), notlength / 4. - Store raw history in your own DB; the LLM context is a view, not the source of truth.
- Emit a metric per turn:
messages.kept,messages.summarised,tokens.in,tokens.cached.
Key Takeaways
- Short-term memory is a budget problem with correctness constraints — tokens × cost × recall.
- Hybrid (pinned facts + rolling summary + recent turns) is the default that survives contact with users.
- Trim by turn boundary, exploit provider caching, and keep the raw log out-of-band.