


Problem Context
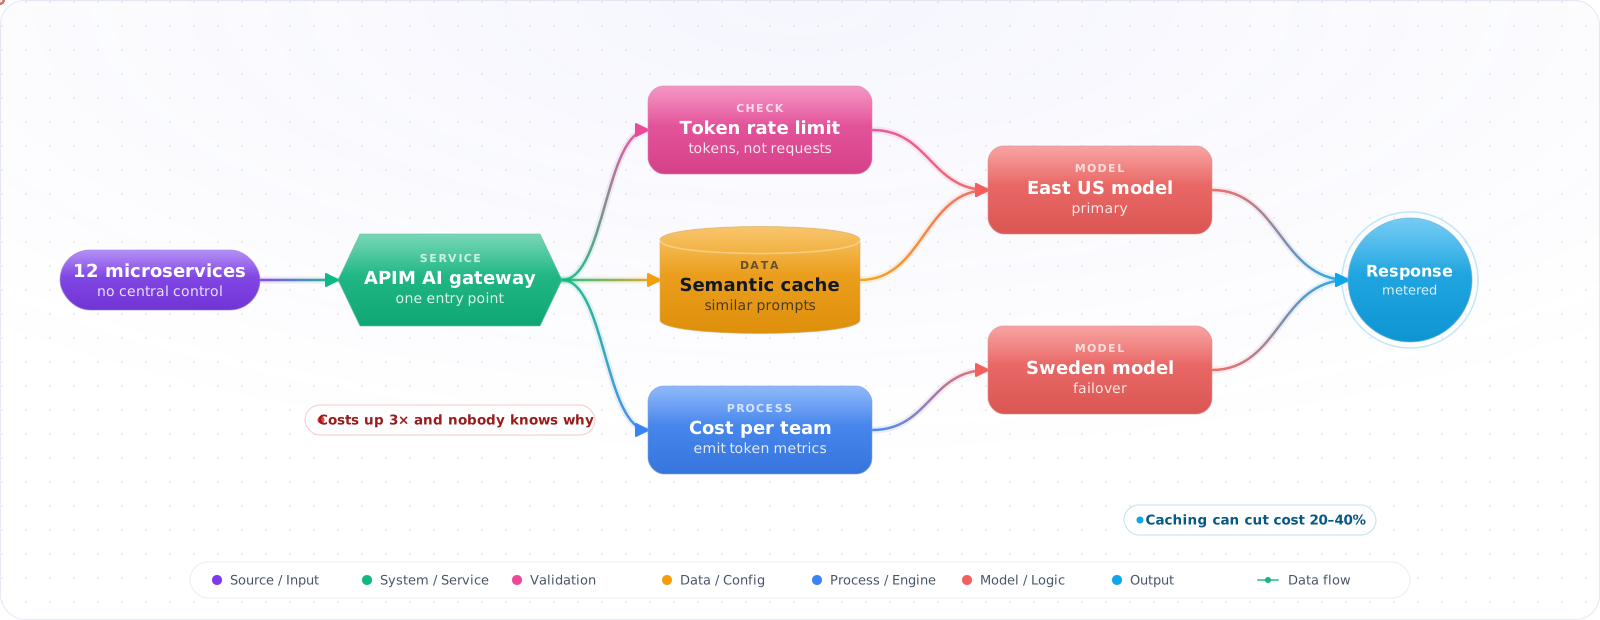
Your team has a working LLM integration. The demo is impressive. Then production happens: costs spike unpredictably, one runaway feature burns through your token budget, a model endpoint has a brownout, and you have zero visibility into which service is calling what.
The AI Gateway pattern places an intermediary layer between your applications and LLM endpoints. It's the same pattern we've used for decades with API Gateways — but adapted for the unique characteristics of generative AI: variable latency, token-based pricing, non-deterministic outputs, and rapidly evolving model versions.
- Your LLM costs spiked 3x last month and you have no idea which feature caused it
- One team's runaway summarization job burned through the token budget for everyone
- You're calling Azure OpenAI directly from 12 different microservices with no central control
- A model endpoint went down and half your features broke because there's no fallback
One gateway in front of every model call addresses all four.
Concept Explanation
An AI Gateway sits between your application services and one or more LLM providers, providing a single control plane for traffic management, cost governance, and observability.
      flowchart LR
          subgraph Applications
              A1["Chat Service"]
              A2["Search Service"]
              A3["Code Assistant"]
          end

          subgraph AI Gateway
              GW["Azure API Management"]
              GW --> SC["Semantic Cache"]
              GW --> RL["Rate Limiting"]
              GW --> LB["Load Balancer"]
              GW --> LOG["Token Logging"]
          end

          subgraph Backends
              B1["Azure OpenAI - East US"]
              B2["Azure OpenAI - West EU"]
              B3["Claude API"]
              B4["Local Model - Phi-4"]
          end

          A1 --> GW
          A2 --> GW
          A3 --> GW
          LB --> B1
          LB --> B2
          LB --> B3
          LB --> B4

          style GW fill:#4f46e5,color:#fff,stroke:#4338ca
          style SC fill:#7c3aed,color:#fff,stroke:#6d28d9
          style RL fill:#d97706,color:#fff,stroke:#b45309
Core Capabilities
1. Token-Aware Rate Limiting
HTTP rate limiting (requests/second) doesn't work for LLMs because one request might use 50 tokens and another 4,000. You need token-based quotas: "Team X gets 500K tokens/day across all models." Azure APIM supports this with its built-in llm-token-limit policy, which counts the tokens in LLM responses and enforces a rate, a quota, or both.
2. Semantic Caching
If two users ask "What's our refund policy?" within an hour, why call the LLM twice? Semantic caching embeds the incoming prompt, checks similarity against recent requests, and returns a cached response if the match exceeds a threshold. This alone can cut costs noticeably for customer-facing applications.
3. Load Balancing Across Deployments
Azure OpenAI enforces per-deployment token-per-minute (TPM) limits. A single deployment rarely has enough capacity for production traffic. The gateway round-robins or priority-routes across multiple deployments, regions, or even providers — transparently to the calling application.
4. Model Routing
Not every request needs GPT-5.6 Sol. A gateway can route based on request metadata: simple classification tasks go to GPT-5.6 Luna, complex reasoning goes to GPT-5.6 Sol, and latency-sensitive requests go to a local Phi-4 deployment.
Implementation
Azure API Management (APIM) has first-class support for AI Gateway patterns. Here's the core setup:
Step 1: Configure Multiple Backends
<!-- A backend pool holds the three deployments. Pools can use round-robin,
     weighted or priority-based balancing, and backends can have circuit breakers. -->
      <set-backend-service backend-id="aoai-pool" />
Step 2: Token-Based Rate Limiting
<!-- Inbound: enforce a token rate and a daily token budget per subscription -->
<llm-token-limit
    counter-key="@(context.Subscription.Id)"
    tokens-per-minute="80000"
    token-quota="500000"
    token-quota-period="Daily"
    estimate-prompt-tokens="false"
    remaining-quota-tokens-header-name="x-remaining-token-quota" />

<!-- Outbound: Track actual token consumption -->
<choose>
    <when condition="@(context.Response.StatusCode == 200)">
        <set-variable name="tokens" value="@{
            var body = context.Response.Body.As<JObject>();
            return body["usage"]?["total_tokens"]?.ToString() ?? "0";
        }" />
        <log-to-eventhub logger-id="token-logger">@{
            return new JObject(
                new JProperty("subscription", context.Subscription.Id),
                new JProperty("tokens", context.Variables["tokens"]),
                new JProperty("model", context.Request.Headers
                    .GetValueOrDefault("x-model", "unknown")),
                new JProperty("timestamp", DateTime.UtcNow)
            ).ToString();
        }</log-to-eventhub>
    </when>
</choose>
Step 3: Semantic Cache with Azure Redis
<!-- Inbound: Check semantic cache -->
<llm-semantic-cache-lookup
    score-threshold="0.05"
    embeddings-backend-id="embedding-backend"
    embeddings-backend-auth="system-assigned">
    <vary-by>@(context.Subscription.Id)</vary-by>
</llm-semantic-cache-lookup>

<!-- Outbound: Store in cache -->
<llm-semantic-cache-store duration="3600" />
APIM's built-in semantic cache policy handles the embedding, similarity search, and cache management internally. You configure the similarity threshold, and lower values demand a closer match. Microsoft suggests starting around 0.05 and warns that values above 0.2 can return the wrong answer.
Step 4: Content Safety
<!-- Inbound: screen prompts with Azure AI Content Safety -->
<llm-content-safety backend-id="content-safety-backend" shield-prompt="true">
    <categories output-type="EightSeverityLevels">
        <category name="Hate" threshold="4" />
        <category name="Violence" threshold="4" />
    </categories>
</llm-content-safety>
Pitfalls
1. Caching non-deterministic outputs
If your application relies on temperature > 0 for creative outputs, semantic caching returns the same response every time. Only cache when deterministic answers are acceptable — factual Q&A, document summarization, classification.
2. Gateway becomes a single point of failure
If the gateway goes down, every AI feature goes down. Use APIM's multi-region deployment or an active-passive failover configuration. Include circuit-breaker policies that fall back to a direct endpoint if the gateway is unhealthy.
3. Ignoring streaming responses
Most LLM integrations use server-sent events (SSE) for streaming. Gateway policies that buffer the full response before forwarding break streaming latency. Ensure your gateway supports pass-through streaming and only logs token counts from the final SSE event.
4. Over-engineering routing logic
Start with simple round-robin. Sophisticated cost-optimized routing that picks the cheapest model per request sounds great until you're debugging why some responses are subtly wrong because the router picked the wrong model tier. Add intelligence gradually, with evaluation metrics.
5. No fallback strategy
When Azure OpenAI returns 429 (rate limited), the gateway should automatically retry against a different deployment or region, not propagate the error. Configure retry-after with exponential backoff and cross-region failover.
Gateways in the Age of Agents
The gateway started as a way to route and rate limit chat calls. Agents have widened its job, and InfoQ's 2026 trends report lists AI gateways among the innovators this year.
The biggest change is that tool traffic now needs a choke point as well. Every call an agent makes to an MCP server is a place where credentials, data and untrusted content cross a boundary. An MCP gateway gives you one place to enforce which servers are allowed, attach per-user credentials, log tool calls and apply rate limits. The 2026-07-28 MCP revision helps here, since requests now carry Mcp-Method and Mcp-Name headers, so a gateway can route and limit by tool without parsing the body. Removing sessions also means any replica can serve any request.
Cost control needs a new unit too. A per-request limit doesn't stop an agent making 400 requests. Budgets should apply per run, per user and per team, and they should stop work when exceeded, not just raise an alert after the money has gone.
Model routing
Routing is where a gateway pays for itself. Send simple requests to a cheaper tier and hard ones to a stronger model, based on rules or a small classifier. Be careful with one thing: prompt caches are per model, so routing a conversation between models on every turn can lose your cached prefix. Keep a session on one model unless you have a reason to move it. Fallback needs the same care. Models differ in parameters and tool rules, so a request that works on one provider can fail on another. A failover path you have never tested is just a theory, so run it on real traffic occasionally.
Semantic caching still has a place, but be conservative. A cached answer to a similar question can be wrong for the current user. Include the user's tenant in the key, and keep it off for anything personalised. Exact-match caching and provider prompt caching are safer and often save more.
Keep your gateway boring, and make sure it can fail open or closed by policy. It sits on every model call, so if it goes down, everything does.
Practical Takeaways
- Deploy an AI Gateway before you have cost problems, not after. Retrofitting routing and quotas into 15 different services is painful.
- Semantic caching can pay off quickly. For customer-facing apps with repeated questions, it can save tokens with near-zero implementation effort on APIM.
- Use token-based quotas, not request-based. One summarization request can cost many times more than a classification request.
- Log every request's token count, model, latency, and calling service. This data is how you'll optimize costs and debug quality issues.
- Start with Azure APIM's built-in AI policies rather than building custom middleware. The policies cover streaming, token counting and caching, though token counts are estimated when streaming.