

Your Offline Set Has Not Met Your Users Yet
Offline evals (a fixed test set in CI) catch the regressions you can imagine. Online evals catch the regressions only your real users generate: surprise topic mixes, new languages, abusive inputs, and slow degradations from prompt drift. Without online evals, your first signal of quality decay is a customer complaint — and by then the bad responses are weeks old.
- You ship a prompt change, CI is green, users complain three days later
- You have no number for "is the answer actually good?" in production
- Your only quality signal is thumbs-down clicks, which lag by hours and bias toward angry users
The Three Online Eval Modes
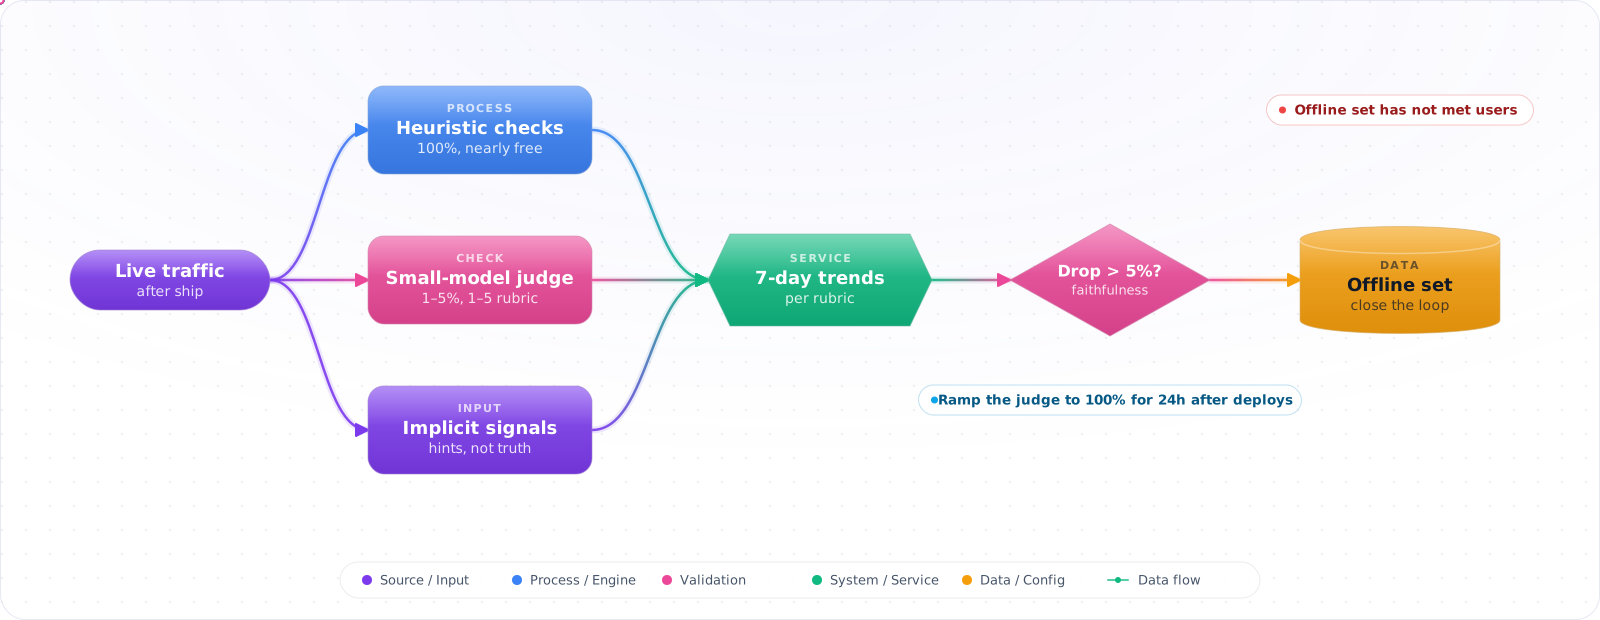
- Reference-free heuristics — schema valid, language detect, length plausible, citation present. Fast, cheap, run on 100%.
- LLM-as-judge — a separate model scores faithfulness, relevance, harmfulness against a rubric. Run on 1–5% of traffic.
- Implicit user signals — click-through, copy event, follow-up question, abandonment. Free, noisy, lagging.
flowchart LR
    P[Production request] --> R[Response]
    R --> H[Heuristics: schema/language/length]
    H --> S{Sample 1–5%}
    S -- yes --> J[LLM-as-judge:<br/>faithfulness, relevance, harm]
    J --> M[Metric: eval.score]
    R --> UI[User UI]
    UI --> IM[Implicit signals:<br/>copy, follow-up, abandon]
    IM --> M
LLM-as-Judge: The Three Rubrics That Matter
- Faithfulness — does the answer only state things supported by the retrieved context? Critical for RAG.
- Relevance — does the answer address the question that was asked? Catches off-topic drift.
- Safety/policy — does the response violate your content rules? Complements your guardrails.
Use a smaller, cheaper model as the judge (gpt-6-luna, claude-haiku) with a strict rubric and a 1–5 score. Calibrate the judge against a human-labelled set before trusting it — judges drift too.
Rubric: Faithfulness (1–5)
5  Every claim is directly supported by the context.
4  All key claims supported; minor unsupported detail.
3  Mix of supported and unsupported claims.
2  Mostly unsupported; one or two grounded claims.
1  Hallucinated; nothing in the context.

Return JSON: { "score": int, "unsupported_claims": [string] }
Implicit Signals: Treat as Hints, Not Truth
Implicit signals are great as early-warning indicators but terrible as ground truth (users abandon for many reasons unrelated to quality). Useful pairings:
- Drop in "copy answer" events on the support widget → answers got less actionable.
- Spike in "ask again" rate → answers got less clear.
- Increase in average follow-up turn count → first-turn answer is missing context.
Sampling Strategy
- Run heuristic checks on 100% — cost is essentially zero.
- LLM-as-judge on 1–5% steady-state, ramped to 100% on a deploy for 24h.
- Always evaluate all negative-feedback responses (free training set for offline evals).
- Always evaluate a stratified sample (per tenant, per language, per endpoint) so small segments aren't invisible.
Closing the Loop
Online evals only matter if they trigger action. Wire them into:
- An alert when 7-day faithfulness drops > 5%.
- A nightly export of low-scoring responses into your offline eval set (after PII review).
- A deploy gate that runs a 30-minute canary at 100% eval sampling on each release.
Failure Modes
- Judge model upgrade silently shifts scores. Pin the judge model version and the rubric version.
- Sampling bias — sampling only successful requests hides the failures you most need to evaluate.
- Eval drift — the rubric stops matching what the product cares about. Re-validate against human labels quarterly.
- Privacy — judge prompts include user inputs. Send them to the same vendor/region as your primary LLM, not a third party.
Production Checklist
- 100% heuristic checks; 1–5% LLM-as-judge; 100% on negative-feedback samples.
- Pinned judge model + versioned rubric + human-calibrated thresholds.
- Eval scores emitted as metrics with the same dimensions as cost/latency.
- Alerts and deploy gates wired to eval drift.
Key Takeaways
- Online evals are the quality counterpart to cost telemetry — without them you ship blind.
- Heuristics + LLM-as-judge + implicit signals form a layered, affordable quality pulse.
- Wire evals into alerts and deploy gates or they are just dashboards.