

LLM Model Landscape
GPT-4o, Claude, Llama, Gemini — model selection, benchmarks, cost-performance trade-offs, context windows and deployment options.
13 articlesin LLM Model Landscape
GPT: OpenAI's Model Family in Practice
The GPT-6 tiers, what reasoning effort replaced, when to use the Responses API over Chat Completions, how the bill is calculated, and what is different on Azure.
Claude: Anthropic's Model Family in Practice
The four Claude tiers, adaptive thinking and effort, the tool-use rules that differ from other providers, prompt caching, and where you can run it.
Llama: Open-Weight Models for Production
The Llama lineup and licence, serving with Ollama and vLLM, GPU memory sizing, and an honest look at when a hosted API is still the better choice.
Evals for Choosing a Model
Why public benchmarks do not transfer to your workload, how to build a model-selection eval, and why cost per successful task beats price per token.
Hallucination Testing: Measuring What the Model Makes Up
The three kinds of hallucination, a test set that includes questions with no answer, claim-by-claim faithfulness scoring, and what lowers the rate.
Edge Models: Running Small LLMs on Phones, Laptops and Browsers
What fits in device memory, why bandwidth sets generation speed, which runtime to use per platform, and how to ship quantised weights with a cloud fallback that keeps the privacy promise.
Self-Hosting LLMs: Running a Model as a Service
Break-even maths, GPU sizing from weights and KV cache, choosing between vLLM, SGLang and llama.cpp, and what to scale and alert on once open-weight models carry production traffic.
Gemini: Google's Multimodal AI
Google's natively multimodal model family — the Pro/Flash trade-off, Search grounding, built-in code execution, and Vertex AI for enterprise deployment.
LLM Cost-Performance Analysis
Frontier vs mini-tier trade-offs, model routing and cascading architectures, batch pricing, and a worked cost model for a real production feature.
Context Windows: Size, Quality, and Trade-offs
Context length limits, the 'lost in the middle' effect, prompt caching, and when a huge context window is the wrong fix for a retrieval problem.
LLM API Providers Compared
OpenAI, Anthropic, Google, Azure, AWS Bedrock, Together, Groq — compare direct, cloud-hosted, and inference-as-a-service API providers on pricing, latency, and enterprise fit.
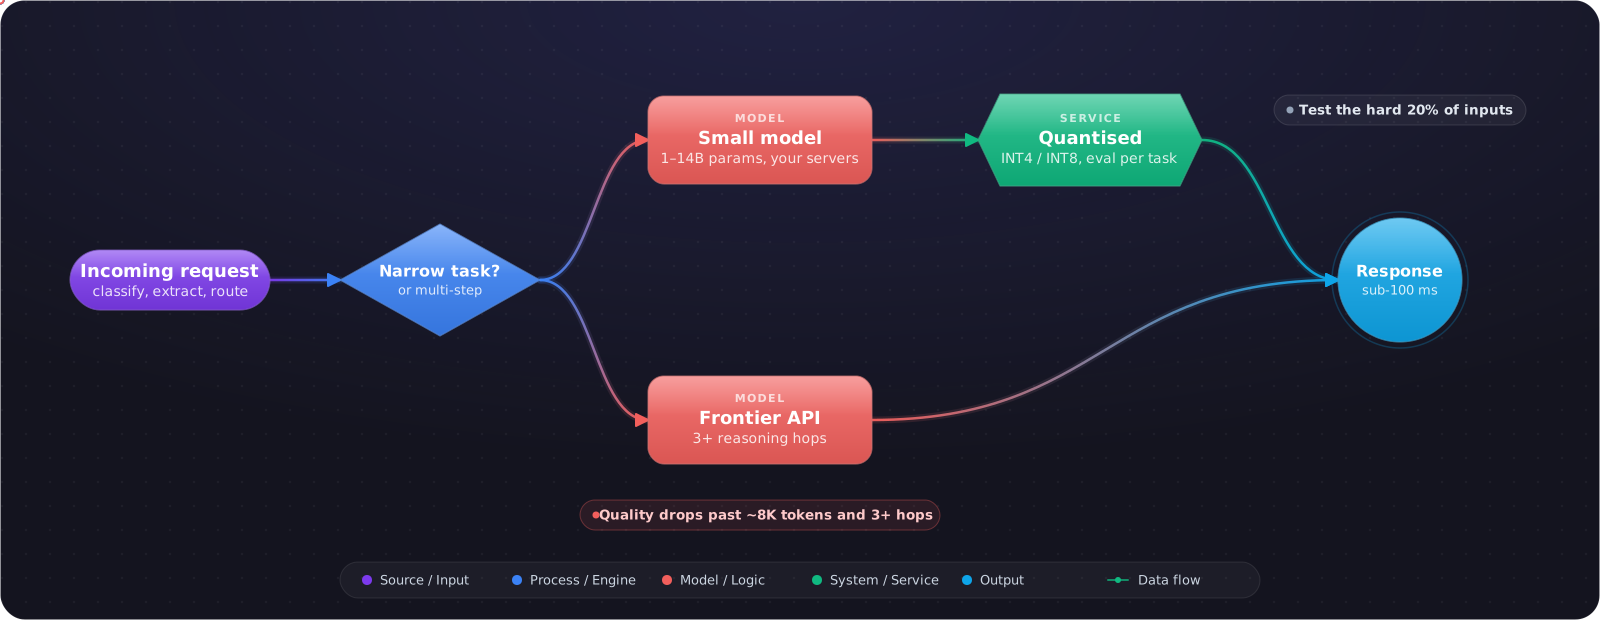
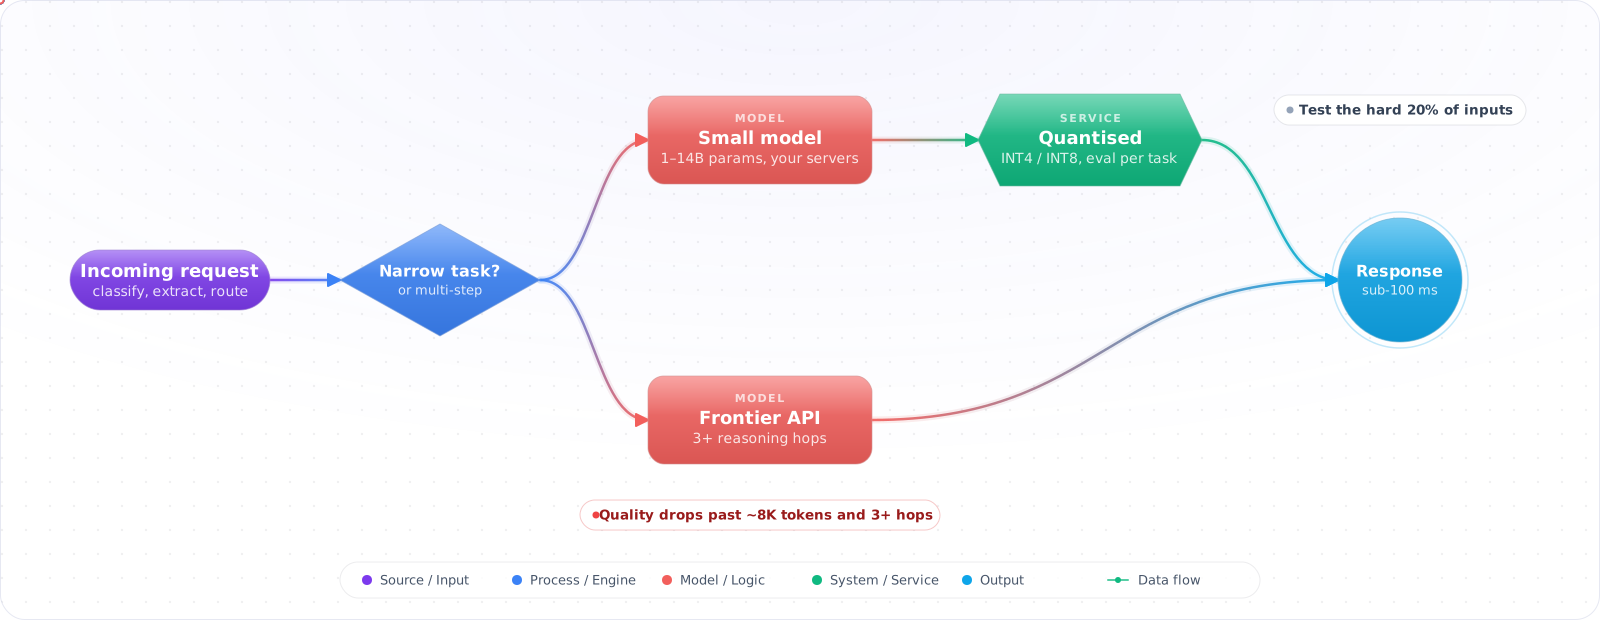
Small Language Models in Production
When and how to use small language models like Phi, Gemma, and Mistral in production — quantization, deployment patterns, and latency-cost trade-offs.
Claude vs GPT for Engineering Workflows
A practical comparison of Claude and GPT models for real engineering tasks — code generation, debugging, architecture reviews, and documentation.