

Show, Don't Tell
You have written two careful paragraphs describing the summary format: three lines, these labels, no greetings. The model follows it most of the time and drifts the rest. Then you paste in three example summaries, and the drift mostly stops.
That is few-shot prompting, and it works because models copy what they are shown more reliably than they follow descriptions. It is also easy to get wrong. Examples teach content as well as format, their order matters more than it should, and every example costs tokens on every call. Below is how to choose them, when zero-shot is enough, and how the advice changes on reasoning models.
- Your LLM outputs the right content but the wrong format — you're spending tokens reformatting
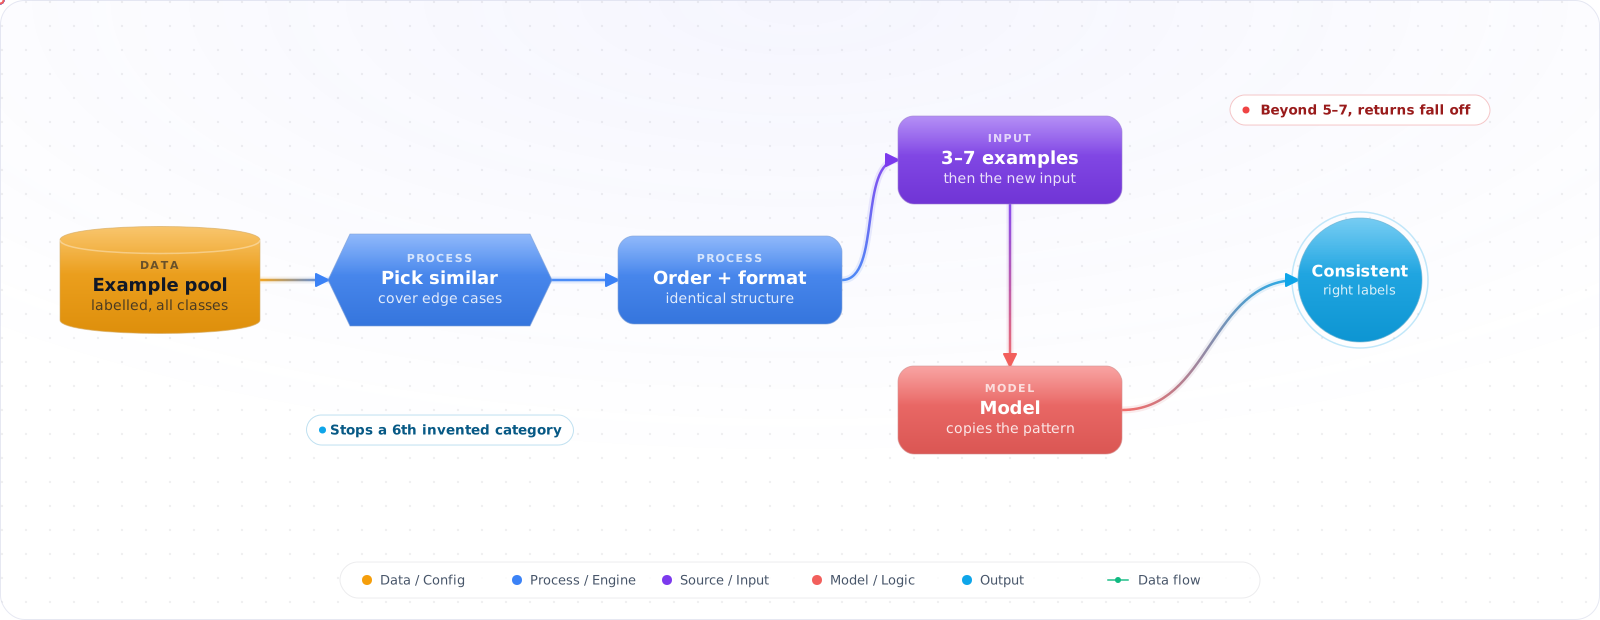
- You have a classification task with 5 categories and the model keeps inventing a 6th
- Your model writes in a style that doesn't match your product voice
- You've tried describing what you want in instructions but the model ignores them
Three well-chosen examples in the prompt consistently outperform two paragraphs of instructions for format-sensitive tasks.
Few-Shot vs Zero-Shot
flowchart TD
    task["New task"] --> wellKnown

    wellKnown{"Well-known task?
(summarise, translate,
write code)"}
    wellKnown -->|Yes| zeroShot["Zero-shot
Just describe the task"]
    wellKnown -->|No| specific

    specific{"Format-sensitive
or style-specific?"}
    specific -->|Yes| fewShot["Few-shot
3–5 examples in prompt"]
    specific -->|No| zeroShot
Few-Shot Structure
// Building a few-shot prompt programmatically
const examples = [
  {
    input: "The checkout button doesn't work on mobile",
    output: JSON.stringify({
      category: "bug",
      priority: "high",
      component: "checkout",
      platform: "mobile"
    })
  },
  {
    input: "Can you add dark mode?",
    output: JSON.stringify({
      category: "feature-request",
      priority: "medium",
      component: "ui",
      platform: "all"
    })
  },
  {
    input: "How do I reset my password?",
    output: JSON.stringify({
      category: "support",
      priority: "low",
      component: "auth",
      platform: "all"
    })
  }
];

function buildFewShotPrompt(userTicket: string): string {
  const exampleBlock = examples.map(e =>
    `Input: ${e.input}
Output: ${e.output}`
  ).join('

');

  return `You are a support ticket classifier. Classify each ticket into the JSON format shown.

${exampleBlock}

Input: ${userTicket}
Output:`;
}

// Usage
const prompt = buildFewShotPrompt("App crashes when I upload a profile picture");
// Model completes: {"category":"bug","priority":"high","component":"profile","platform":"all"}
Example Selection
Random examples are baseline. Strategic selection improves accuracy significantly for complex tasks.
// Strategy 1: Semantic similarity — show examples most similar to the input
// Uses embeddings to find the closest examples in your example bank

async function selectSimilarExamples(
  input: string,
  exampleBank: Array<{ input: string; output: string }>,
  k = 3
): Promise<Array<{ input: string; output: string }>> {
  const inputEmbedding = await embed(input);

  const ranked = await Promise.all(
    exampleBank.map(async (example) => {
      const exampleEmbedding = await embed(example.input);
      const similarity = cosineSimilarity(inputEmbedding, exampleEmbedding);
      return { example, similarity };
    })
  );

  return ranked
    .sort((a, b) => b.similarity - a.similarity)
    .slice(0, k)
    .map(r => r.example);
}

// Strategy 2: Label coverage — ensure examples span all output categories
// For classification: include at least one example per class
function selectBalancedExamples(
  exampleBank: Array<{ input: string; output: { category: string } }>,
  categoriesNeeded: string[]
): Array<{ input: string; output: { category: string } }> {
  return categoriesNeeded.map(category =>
    exampleBank.find(e => e.output.category === category)!
  );
}
Ordering and Format Consistency
// Order effect: models pay more attention to early and late examples
// Put edge cases or tricky examples at the end (recency effect)
// Put typical cases first (helps establish the pattern)

// Format consistency: your examples must follow the EXACT same format
// or the model will blend the formats

// ❌ Inconsistent — model will produce inconsistent output
const badExamples = [
  "Input: foo
Output: {"a":1}",
  "Input: bar
Output: {
  "a": 2
}"  // different JSON formatting
];

// ✅ Consistent — same format every time
const goodExamples = [
  "Input: foo
Output: {"a":1}",
  "Input: bar
Output: {"a":2}"  // identical formatting
];

// If you want structured JSON output, use structured output mode
// instead of few-shot JSON examples:
const response = await openai.chat.completions.create({
  model: 'gpt-6.1-sol',
  messages: [{ role: 'user', content: prompt }],
  response_format: {
    type: 'json_schema',
    json_schema: {
      name: 'ticket_classification',
      schema: {
        type: 'object',
        properties: {
          category: { type: 'string', enum: ['bug', 'feature-request', 'support'] },
          priority: { type: 'string', enum: ['low', 'medium', 'high'] },
        },
        required: ['category', 'priority'],
      },
    },
  },
});
Few-Shot With Reasoning Models
Examples have not stopped working, but what they are good for has narrowed. A current frontier model rarely needs examples to understand a task. It still needs them to learn conventions that cannot be guessed: your label set, your house style, the exact output shape, where you draw the line on an ambiguous case.
- Use examples for conventions, not for capability. If the model already gets the task right zero-shot, examples mostly cost tokens. If it gets the task right but in the wrong format or with the wrong boundary cases, examples are the fastest fix.
- Watch for over-anchoring. Strong models copy examples closely. Three examples that all happen to be short, polite and about billing will pull every answer toward short, polite and billing. Vary the examples along every dimension you do not want copied.
- Leave the reasoning out of the examples. Worked reasoning traces helped single-pass models. A reasoning model does its own thinking, and a scripted trace tends to constrain it. Show input and final output only.
- Put examples in the cached part of the prompt. A stable block of examples near the top of the prompt is billed at the cached rate on repeat requests, roughly a tenth of the normal input price. Examples chosen per request cannot be cached, so only select dynamically when it measurably improves accuracy.
Pitfalls
Too many examples
More examples are not always better. Beyond 5–7 examples, returns diminish rapidly and you're spending tokens that could go to the actual task. If you need many examples to constrain the output, fine-tuning is usually more efficient than few-shot at scale.
Label leakage in examples
If your examples are not representative of your production input distribution, the model will learn patterns that don't transfer. Evaluate on a held-out set of real inputs, not on examples similar to the ones in your prompt.
Conflating few-shot with fine-tuning
Few-shot prompting works at inference time and costs tokens on every call. Fine-tuning bakes the pattern into model weights and costs nothing at inference time beyond the task itself. For high-volume, repetitive tasks (thousands of calls per day), fine-tune on your few-shot examples rather than including them in every prompt.