Start by Asking the Model Directly
Not every question needs retrieval. If the answer is general knowledge the model already has, asking it directly is simpler, cheaper and faster. Retrieval earns its place when the answer lives in your own documents: policies, manuals, tickets, anything the model was never trained on or that changed last week.
The RAG demo is easy: put a few PDFs in a vector store, retrieve the top three chunks, ask the model. It answers the five questions you try, and everyone is impressed. Then real users arrive with real questions, and the answers start citing the wrong policy, missing the obvious paragraph, or confidently making something up from a chunk that was nearly relevant.
Almost none of that is the model. It is retrieval: how documents are split, how candidates are ranked, whether keyword matches survive, whether anyone measures what was retrieved at all. Below are the decisions that decide whether a RAG system holds up, with the numbers I would start from and the point where each one stops being the right call.
- Your RAG demo was impressive — but in production it retrieves the wrong chunks a third of the time
- You've tuned chunk sizes for days and retrieval precision barely moved
- The LLM confidently cites something completely wrong, because the retrieval returned garbage
- You're about to stuff your entire knowledge base into one vector store and hope queries work
- Outcome: Choose a defensible RAG baseline and separate retrieval failures from generation failures.
- Environment: Azure AI Search hybrid retrieval, Azure OpenAI embeddings, and LangChain's Python text splitter; adapt SDK and model versions to your deployment.
- Code status: The Python and C# blocks are partial snippets, not a complete runnable project. The Mermaid block is conceptual.
- Scope: Covers ingestion, chunking, retrieval, reranking, and evaluation—not identity, tenant isolation, deployment, or an all-in cost model.
What Actually Decides Retrieval Quality
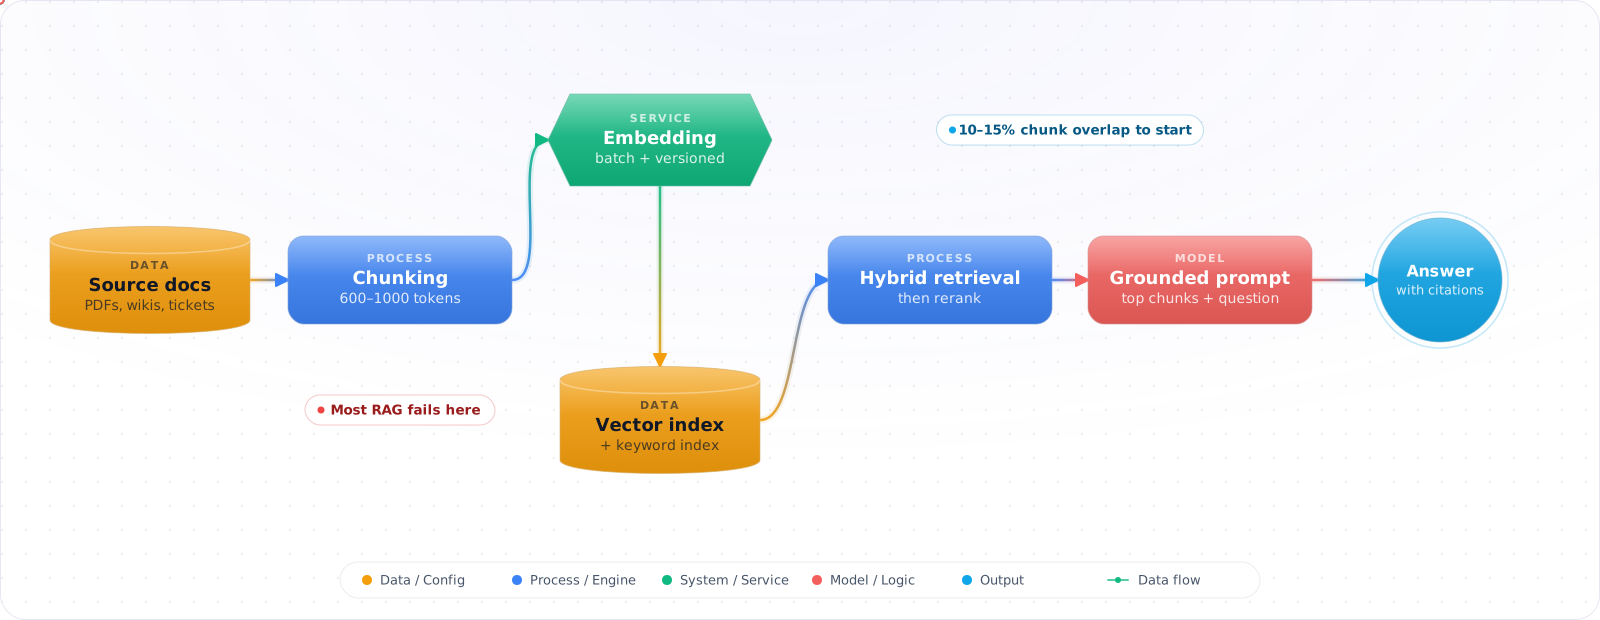
A production RAG system has four critical stages, each with its own failure modes:
      flowchart LR
          A["Document Ingestion"] --> B["Chunking and Preprocessing"]
          B --> C["Embedding and Indexing"]
          C --> D["Retrieval and Ranking"]
          D --> E["LLM Generation"]
          E --> F["Response + Citations"]

          style A fill:#4f46e5,color:#fff,stroke:#4338ca
          style B fill:#4f46e5,color:#fff,stroke:#4338ca
          style C fill:#7c3aed,color:#fff,stroke:#6d28d9
          style D fill:#7c3aed,color:#fff,stroke:#6d28d9
          style E fill:#059669,color:#fff,stroke:#047857
          style F fill:#059669,color:#fff,stroke:#047857
Stage 1: When answers come back half-complete, look at how you chunk
Chunking is where many RAG systems silently fail. The wrong chunk size means either too little context (the LLM can't synthesize an answer) or too much noise (irrelevant content dilutes the signal).
Fixed-size chunking (e.g., 512 tokens with 50-token overlap) is the baseline. It's fast and predictable but ignores document structure entirely. A code sample split mid-function is useless.
Semantic chunking splits on natural boundaries — paragraphs, sections, or topic shifts detected via embedding similarity. This preserves meaning but adds preprocessing cost.
Recursive chunking first splits by structure (headings, code blocks), then subdivides large sections to a size limit. It is a practical baseline to compare against fixed and semantic chunking. Note the units in the example below: with length_function=len, those sizes are characters, not tokens.
# Recursive chunking with LangChain (pip install langchain-text-splitters)
from langchain_text_splitters import RecursiveCharacterTextSplitter

splitter = RecursiveCharacterTextSplitter(
    chunk_size=800,       # characters, because length_function is len
    chunk_overlap=100,
    separators=["\n## ", "\n### ", "\n\n", "\n", ". ", " "],
    length_function=len,
)

chunks = splitter.split_documents(documents)
Rule of thumb: Start with 600–1000 token chunks, 10–15% overlap. Measure retrieval precision before optimizing further.
Check it: Print ten chunks at random and read each as if you had nothing else to go on. Every one should make sense by itself. If one starts mid-sentence, or cuts a table or a code sample in half, the splitter is the problem and not the model.
Stage 2: When similar passages get confused, check the embedding step
Your embedding model is the bottleneck you don't see. Key decisions:
- Model choice:
text-embedding-3-large(Azure OpenAI) for general use. Cohere's embedding models if you need multilingual. Treat the named models as examples and compare currently supported candidates on your own corpus before choosing one. - Dimensionality: 1536 dims is common. Azure OpenAI's large model supports a
dimensionsparameter; lower dimensions can reduce storage and search cost, but measure the recall change on your corpus. - Batch processing: Batch within the provider's current request limits, then tune batch size against throughput, latency, and retry cost.
// Azure OpenAI embedding with reduced dimensions
var embeddingOptions = new EmbeddingGenerationOptions
{
    Dimensions = 512  // Reduce from 3072 default
};

var response = await client.GenerateEmbeddingsAsync(
    new[] { "Your chunk text here" },
    embeddingOptions
);
Check it: Embed the same sentence through the indexing path and through the query path. The two vectors must be identical. A different model, dimension or clean-up step between the two paths is a common and silent cause of bad retrieval.
Stage 3: When the right passage is not in the results, change how you retrieve
Vector similarity alone is often insufficient. Production systems layer multiple retrieval strategies:
Hybrid search combines vector similarity with keyword (BM25) search. Azure AI Search does this natively with search +vectorQueries in a single API call. This catches exact-match terms that embedding similarity misses.
Re-ranking applies a cross-encoder model to the top-K results from initial retrieval. This is computationally expensive per-item but often improves precision when applied to 20–50 candidates. Azure AI Search offers built-in semantic ranking for this.
Query expansion rewrites the user query into multiple search variants using the LLM itself, then merges results. This handles ambiguous queries where the user's phrasing doesn't match document terminology.
Check it: Take twenty real questions, each with a known source passage. Count how often that passage is in the top ten with vector search alone, then with hybrid search, then with reranking. Keep each addition only if the count goes up.
Stage 4: When the model makes things up, ground the answer
Pass retrieved chunks as context with explicit grounding instructions:
System: Answer the user's question using ONLY the provided context.
If the context doesn't contain sufficient information, say so.
Cite sources using [1], [2] notation.

Context:
[1] {chunk_1_text} (source: design-doc.md, section: Architecture)
[2] {chunk_2_text} (source: api-spec.yaml, section: Endpoints)

User: {query}
Check it: Ask a question your documents don't cover. The assistant should say it doesn't know, not improvise. Then take a sample of answers and confirm that each cited passage really supports the sentence it is attached to.
Building the Pipeline Stage by Stage
A scalable RAG pipeline on Azure looks like this:
      flowchart TD
          subgraph Ingestion
              A["Blob Storage"] --> B["Azure Function Trigger"]
              B --> C["Document Cracking + Chunking"]
              C --> D["Azure OpenAI Embeddings"]
              D --> E["Azure AI Search Index"]
          end

          subgraph Query
              F["User Query"] --> G["Query Embedding"]
              G --> H["Hybrid Search + Semantic Ranking"]
              H --> I["Top-K Chunks"]
              I --> J["Azure OpenAI GPT-5.6 Sol"]
              J --> K["Grounded Response"]
          end

          E -.->|vector index| H

          style A fill:#d97706,color:#fff,stroke:#b45309
          style E fill:#4f46e5,color:#fff,stroke:#4338ca
          style J fill:#059669,color:#fff,stroke:#047857
          style K fill:#059669,color:#fff,stroke:#047857
Key implementation details:
- Ingestion: Trigger on blob upload via Event Grid. Use Azure Document Intelligence for PDFs, images, and scanned docs — it extracts structure (tables, headings) that plain text extraction misses.
- Indexing: Azure AI Search with vector + full-text fields. Configure
vectorSearchwith HNSW algorithm,efConstruction: 400for index build quality. - Query path: Create the query embedding first, then send the hybrid search request that consumes it. If keyword search is a separate branch, that independent branch can start alongside embedding; you then need an explicit fusion step. Set a latency budget for the whole path.
// Hybrid search with Azure AI Search.
// queryEmbedding is an input to VectorizedQuery, so its API call must finish first.
var searchOptions = new SearchOptions
{
    Size = 10,
    Select = { "content", "title", "source", "chunk_id" },
    QueryType = SearchQueryType.Semantic,
    SemanticSearch = new SemanticSearchOptions
    {
        SemanticConfigurationName = "default",
        QueryCaption = new QueryCaption(QueryCaptionType.Extractive)
    },
    VectorSearch = new VectorSearchOptions
    {
        Queries =
        {
            new VectorizedQuery(queryEmbedding)
            {
                KNearestNeighborsCount = 20,
                Fields = { "contentVector" }
            }
        }
    }
};

var results = await searchClient.SearchAsync<SearchDocument>(
    userQuery,  // BM25 keyword search
    searchOptions  // + vector search + semantic ranking
);
What Breaks Once Real Traffic Arrives
1. Ignoring chunk metadata
Chunks without source information are useless for citations and debugging. Always store: source document, section heading, page number, and timestamp. When retrieval goes wrong, you need to trace which chunk caused the issue.
2. One embedding model for everything
Code, natural language, and structured data (tables, JSON) have fundamentally different semantic structures. If your corpus mixes these, consider domain-specific embedding models or separate indexes with query routing.
3. No freshness strategy
Documents change. If you don't have an incremental update pipeline, your RAG system serves stale data within weeks. Track document hashes and re-embed only changed chunks.
4. Retrieval without evaluation
You can't improve what you don't measure. Build a test set of query → expected_chunks pairs. Track Mean Reciprocal Rank (MRR) and Recall@K as you change chunking or models.
5. Over-retrieving context
Stuffing 20 chunks into the prompt doesn't help — it confuses the model and burns tokens. Start with 3–5 chunks. Measure answer quality as you increase. Expect a plateau, and find it on your own data.
Measure Retrieval Separately
When an answer is wrong, find out which half failed. Keep a set of real questions with the documents that should answer them, and track recall@10 apart from answer quality. If the right chunk was never retrieved, no prompt can fix it. If it was retrieved and the answer is still wrong, retrieval is fine and the problem sits in context or generation. Teams that skip this tune the wrong half for months.
Try It on Your Own System This Week
Three checks on a RAG system you already have, about an hour in total:
- Collect twenty real questions and mark the passage that answers each. This small set is the most valuable thing in a RAG project. Everything else is tuned against it.
- For your last five wrong answers, look at what was retrieved. If the right passage wasn't there, fix retrieval. If it was there and the answer was still wrong, fix the prompt. Most teams find it's the first.
- Change a document and ask about the change. If the assistant still gives the old answer an hour later, you need an update pipeline before you need anything else.
What I Would Do First
- Start with a measured baseline. Recursive chunks around 600–1000 tokens are a heuristic starting range, not a universal optimum.
- Evaluate hybrid search (vector + BM25) when exact terms such as error codes, product names, and API endpoints matter. Keep the dense-only baseline so the added complexity has to earn its place.
- Measure retrieval quality separately from generation quality. Bad retrieval can't be fixed by a better LLM.
- Plan incremental ingestion early. The point where full re-indexing becomes unacceptable depends on corpus size, refresh rate, and indexing budget.
- Budget for re-ranking. Cross-encoder re-ranking on top-20 results can improve answer quality for complex queries. Late-interaction models like ColBERT v2 are another option.
- Consider Agentic RAG for complex queries. Instead of a single retrieve-then-generate pass, let the LLM plan multi-step retrieval: decompose questions, retrieve iteratively, self-evaluate sufficiency, and re-query when gaps are found. This can improve recall on multi-hop questions.
Completion Check
- A labelled query set measures retrieval recall separately from answer correctness and citation support.
- Chunk size, overlap, embedding model, vector dimensions, and retrieval settings are recorded as versioned experiment inputs.
- The query sequence respects its data dependencies, and any parallel keyword branch has an explicit fusion strategy.
- Failure tests cover missing evidence, stale documents, tenant filtering, and refusal when the retrieved context cannot support an answer.
- Any published latency, quality, or cost number includes its dataset, environment, assumptions, and exclusions.