

AI Wisdom

Tag

RAG

10 articles tagged with “RAG”

A/B-testinga-starA2AACRadaptive-thinkingagent-observabilityagent-patternsagent-protocolsagent-securityagent-skillsagentsAGENTS.mdaggregationaiai-gatewayAI-SearchaksalertingAlertmanageralgorithmsAnthropicAnthropic-APIAPEapi-designapi-gatewayAPI-providersapi-versioningapimAPMapp-routerapp-serviceappsecarchitectureArizearm-templatesASP.NET-Coreaspnet-coreaspnetcoreassertion-functionsassertsasyncauditauthenticationauthorizationAutoGenautomationazureAzure-APIMazure-content-safetyazure-front-doorazure-functionsAzure-OpenAIazure-policyazure-storagebatch-APIbddbeam searchBedrockbenchmarksbest-practicesbfsbi-encoderbias-detectionbicepbinary-searchbranchingbstBundlercache-componentscachingcap-theoremcapability-taggingCapitalizecascadingcase-based-reasoningchain-of-thoughtchartschatbotcheckpointingchunkingCIci-cdci-optimizationcicdclass-decoratorClaudeClaude-CodeCLAUDE.mdclean-architecturecloudcloud-securitycloudeventscode-reviewCodexcoding-agentscompactioncomparisoncompilerOptionscompliancecomposeconcurrencyconcurrent-renderingconditional-typesconsistencyconsistent-hashingconstrained-generationconstraintsconsumer-drivencontainer-registrycontainerscontent-moderationcontent-safetycontextcontext-compressioncontext-engineeringcontext-windowcontract-testingconversational-agentsCopilotcosmos-dbcost-allocationcost-controlcost-optimizationcost-per-taskcost-performanceCoTcoveragecqrscross-sessioncsharpCursorcvecypress.d.tsdapperdashboardsdastdata-fetchingdatabasesdataloaderdatasetsddddecision-frameworkdeclaration-filesdecoratorsDeepEvalDefinitelyTypeddependency-injectiondependency-scanningdeployment-slotsdeploymentsdeprecationdesign-patternsdevopsdfsdijkstradiscriminated-unionsdistributed-tracingdistributivedockerDocker-HubdocumentationDORAdotnetdotnet-9drift-detectionDSPydurable-executiondynamic-discoverydynamic-programminge2e-testingedge AIef-coreef-core-9embeddingsengineeringenvironmentsepisodic-memoryerror-budgetevalsevaluationevent-drivenevent-gridevent-hubseventingexamplesexperience-replayexperimentalDecoratorsfactualityfail-fastfaithfulnessfeature-flagsfederationfew-shotfiberfine-tuningFinOpsflaky-testsflex-consumptionfrontendfunction-callinggarakGeminiGemmagen-ai-semantic-conventionsgenericsGHCRgitGitFlowGitHubgithub-actionsgoal-decompositiongolden-signalsGoogle-DeepMindGPTgpt-4oGPT-6GPUgrammargraphgraphqlGroqgroundingGroupChatgrpcguardrailshallucinationhallucination-detectionharmful-contentharness-engineeringhclhealth-checksheapHelmhookshotchocolateHPAhttphttp2http3hybridcacheiacICLidempotencyidentityimage-scanningin-context-learningincident-responseindexesinferinferenceinfrastructureinput-validationintegrationintegration-testinginteroperabilityintrosortinvariantisolationIstiojailbreakjestjoinsjotaiJSONJSON-modejsonbjwtk8skey-remappingkey-vaultkiotaknapsackknowledge-baseKQLkubernetesKV cacheLangChainLangfuseLangGraphLangSmithlanguagelatencyleast-agencylegacy-codeLinkerdlinqLlamallama.cppLLMLLM-as-judgeLLM-monitoringLLM-securityload-balancinglogginglong-running-agentslong-term-memorylost-in-the-middlelower-boundmanaged-identitymapped-typesmaterialized-viewsMCPmemoizationmemorymemory-consolidationmergemessage-queuemessagingmeta-promptingmetadatametricsmicroservicesmicrosoftminimal-apisMistralmockingmocksModel-Context-Protocolmodel-routingmodel-selectionmodel-servingmoderationmodule-augmentationmodule-resolutionmodulesmongodbmonitoringmonorepomswMTEBmTLSmulti-agentmulti-stage-buildsmulti-tenantmultimodalmvccnarrowingnetwork-securitynextjs-16Node16normalizationnosqloauthoauth2observabilityoffline-evalsoidcOmiton-callon-deviceonline-evalsopaopen-sourceopen-weightOpenAIOpenAI-APIopenapiOpenTelemetryOPROorchestrationOTELOutlinesoutput-formatoutput-validationOWASPP99paaspackage-exportspactpactflowpage-objectsPagerDutyparsingPartialpartitioningpathspattern-matchingperformancepersonal-AIpgvectorPhiPhoenixPickPIIPII-filteringpineconepipelineplanningplaywrightpluginspolicy-as-codepollypostgresqlpricingproductionproduction-monitoringprogressive-disclosureproject-referencesprompt-cachingprompt-designprompt-engineeringprompt-injectionprompt optimisationpromptfooprotobufpulumipythonQdrantqualityquality-gatesquality-scorequantizationqueuesRAGRAG-evaluationRAGASrate-limitingreactreact-19react-compilerreact-internalsreact-queryreact-server-componentsrealtimereasoningreasoning-effortRecordrecursionrecursive-typesred-blackred-green-refactorred teamingredisreflectionregression-testingrelease-managementreplanningresource-limitsResponses-APIrestreusable-workflowsrlsrolling-updatesruntime-safetysaga-patternsandboxingsastsbomscaleschemaschema-designschema-validationSDKsdlcsearchsecrets-managementsecuritysecurity-testingself-consistencyself-hostingSemantic-Kernelsemantic-similarityserializableserver-actionsserverlessservice-busservice-meshshardingshortest-pathsidecar-proxysignalrSKILL.mdSLISLMSLOslopsquattingsnapshot-testingsoftware-designsortingspec-driven-developmentspeculative-decodingspiessqlstabilitystate-graphstate-managementstreamingstreamsstrict-modestridestring-typesstructured-loggingstructured-outputstubssummarisationsupertestsupply-chainsystem-designtail-calltanstack-querytask-framingTC39tddtemplate-literalstemplatesterraformtest-architecturetest-doublestest-pyramidtestcontainerstestingtesting-patternstesting-strategythreat-modelingtoken-buckettoken-budgettoken-economicstoken-limittoken-maskingtoken-trackingtokenstokens-per-secondtool-callingtool-registrytool-usetopological-sortToTtoxicitytracingtrajectorytransactionstree-of-thoughttreestrietrunk-basedtsconfigTTFTtype-guardstype-narrowingtype-predicatestype-safe-routestype-systemtype-transformstypestypescriptunit-testingusage-metricsuser-feedbackutility-typesvalidationvalkeyvaluesvaultvector-dbvector-searchvector-storevendor-neutralverificationversion-controlversioningVertex-AIvisual-regressionvitestvLLMvoice-agentsvulnerabilitiesweaviateweb-apiweb-securityWebLLMwebsocketswindow-functionsWindsurfwiremockworkflowsworking-memoryworkload-identityworkspacesxunityarpzero-shotzero-trustzodzustand
AI Engineering
UsersAssistantVector indexKeyword indexRerankerLLM

Designing RAG Systems That Actually Scale

Intermediate

Chunking strategies, embedding pipelines, retrieval patterns, and when RAG breaks down in production systems.

Updated 12 min
Read →
Databases
UsersApp serverVector index

Vector Database Selection for Production RAG

Cosmos DB, AI Search, Qdrant, Pinecone — benchmarks, cost, and operational complexity for production vector search.
Updated 9 min
Read →
AI Engineering
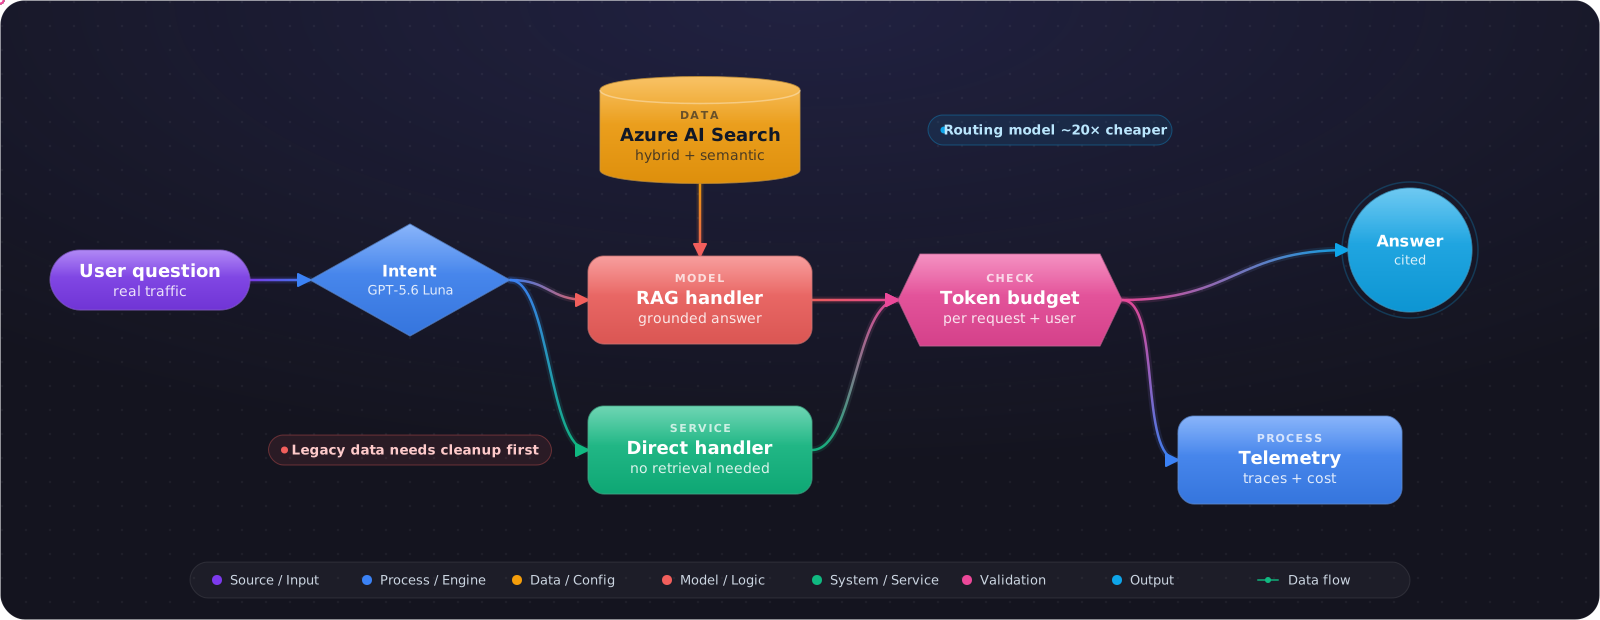
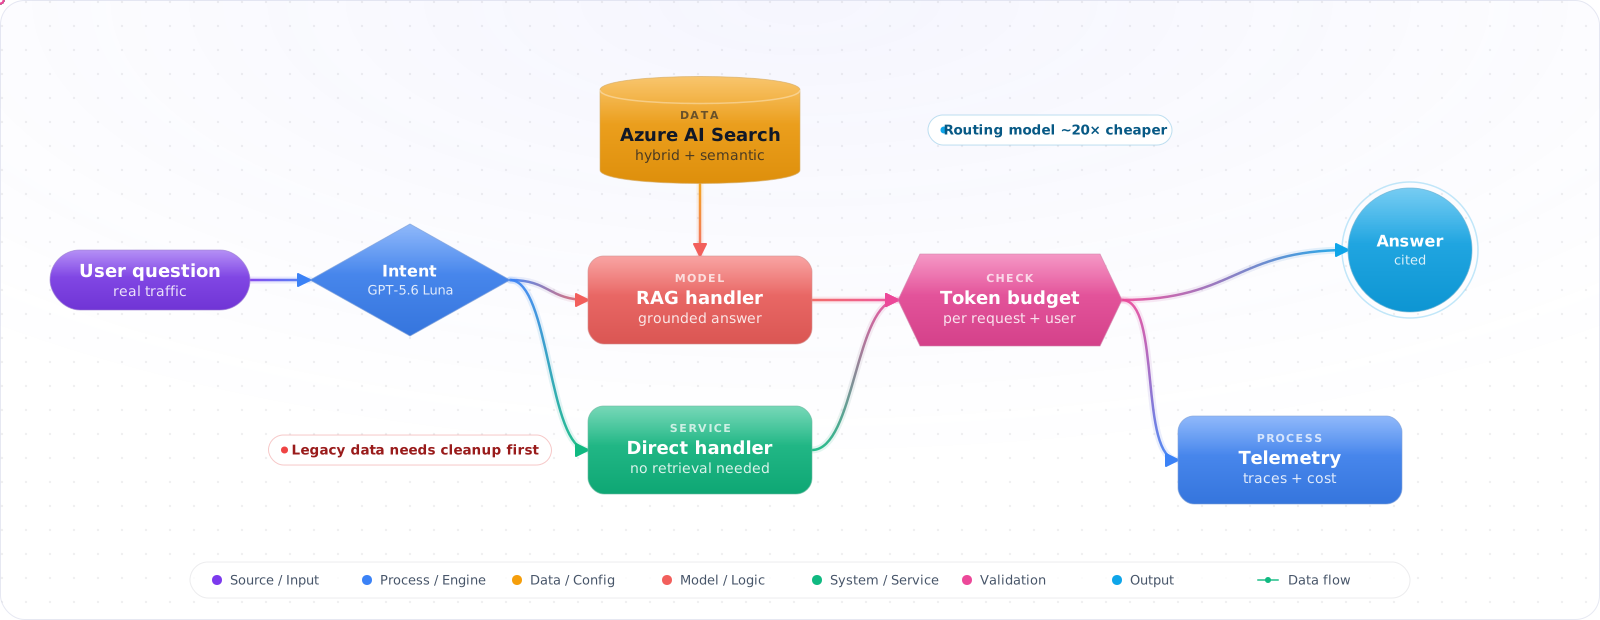
A production AI system on Azure: an orchestrator classifies intent with a cheap model, routes to RAG over Azure AI Search with hybrid retrieval or to direct handlers, enforces token budgets, and traces every step.A production AI system on Azure: an orchestrator classifies intent with a cheap model, routes to RAG over Azure AI Search with hybrid retrieval or to direct handlers, enforces token budgets, and traces every step.

How to Build a Production-Ready AI System (Azure OpenAI + AI Search — Real Architecture)

AdvancedPRO

Azure OpenAI + AI Search + embeddings — real-world architecture for production AI systems, including legacy data, orchestration, hybrid retrieval, cost control, and failure modes.

Updated 15 min
Read →
AI Engineering
TicketsTicket routerCategory guideTuned small modelHeld-out test set

When to Fine-Tune vs Few-Shot vs RAG

Intermediate

A decision framework for choosing between fine-tuning, few-shot prompting, and RAG for production LLM applications.
Updated 10 min
Read →
AI Engineering
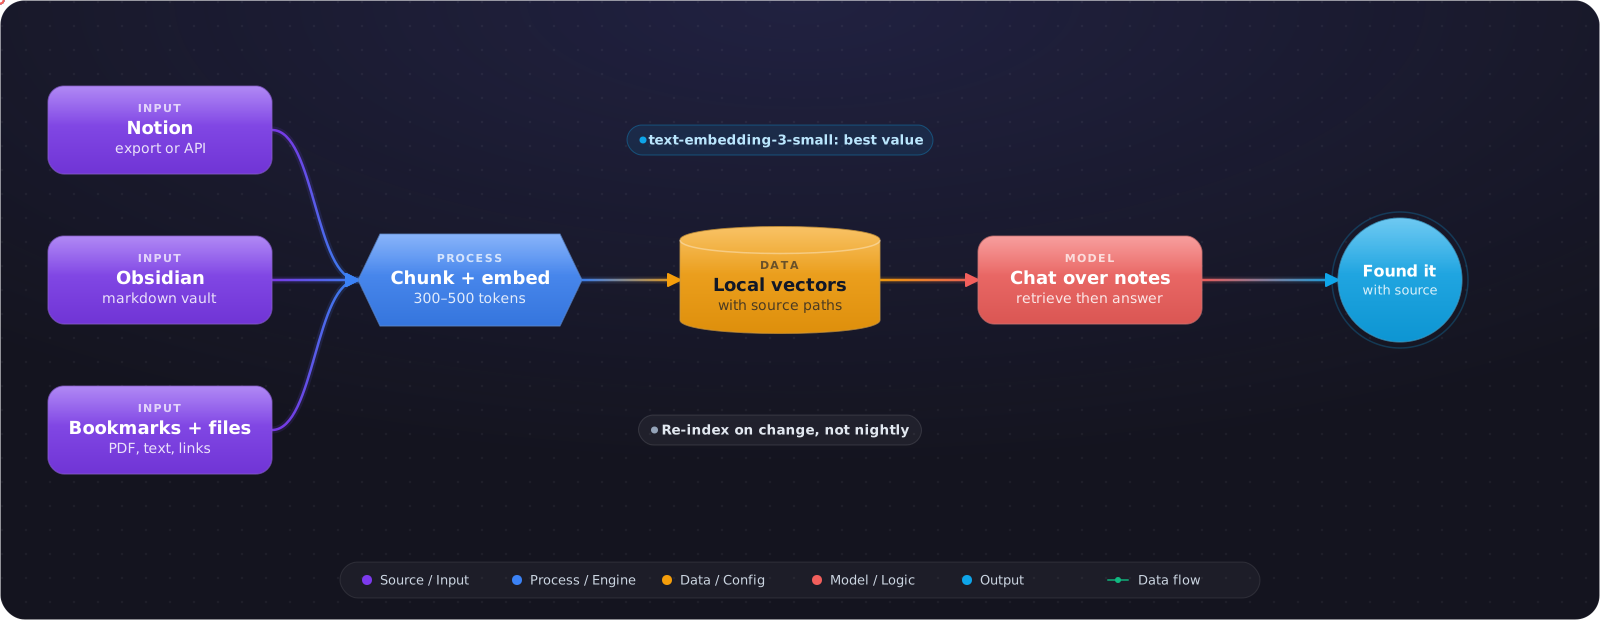
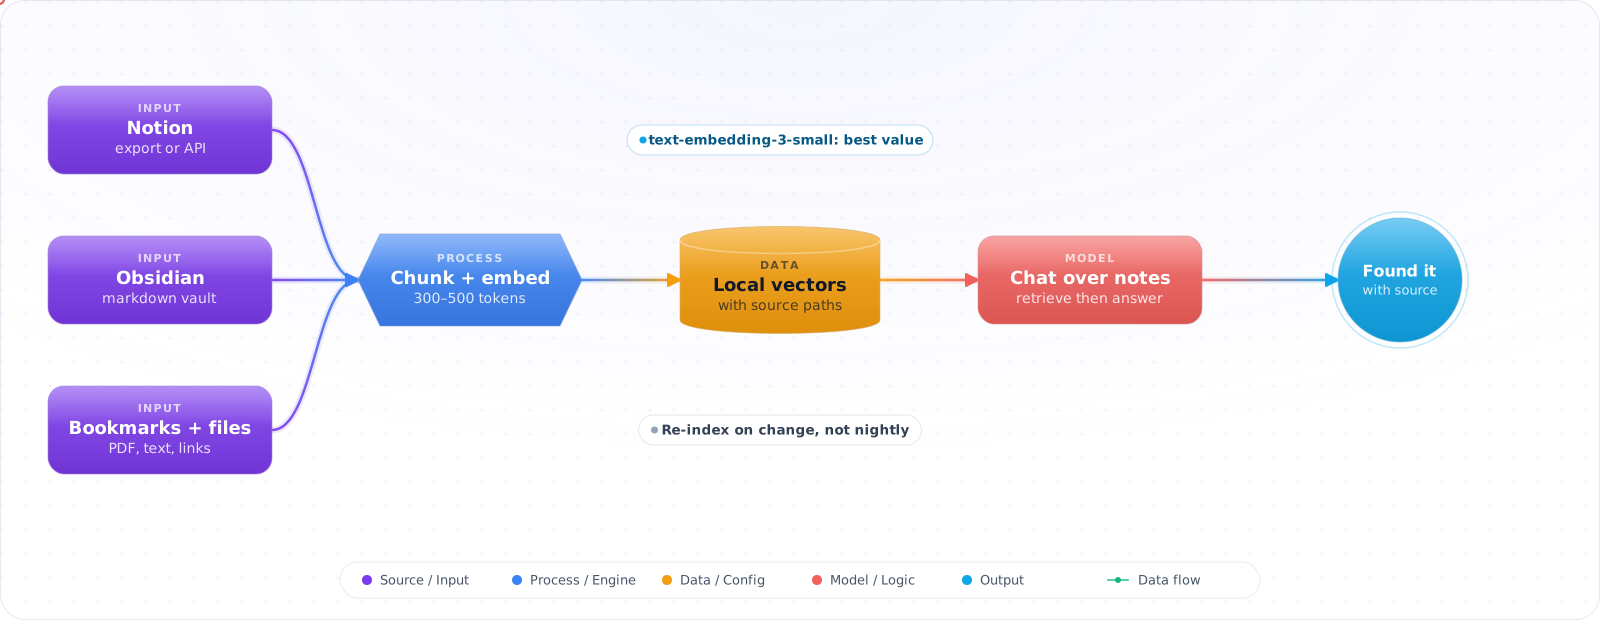
A personal knowledge base: notes from Notion, Obsidian, OneNote and files are chunked at 300 to 500 tokens, embedded with text-embedding-3-small into a local vector store, and queried through a chat interface with sources.A personal knowledge base: notes from Notion, Obsidian, OneNote and files are chunked at 300 to 500 tokens, embedded with text-embedding-3-small into a local vector store, and queried through a chat interface with sources.

Building a Personal AI Knowledge Base

How to build a personal RAG system over your notes, bookmarks, and documents — using embeddings, vector search, and a conversational interface.

Updated 11 min
Read →
Databases
ShoppersStore APIPostgresEmbedding columnHNSW indexFull-text searchDedicated vector DB

pgvector 0.8/0.9: HNSW, halfvec, and RAG on Postgres

AdvancedPRO

pgvector 0.8 (Oct 2024) iterative scans + halfvec, 0.9 sparse vectors, HNSW vs IVFFlat, EF Core + Pgvector.EntityFrameworkCore, halfvec/bit quantization, hybrid search with tsvector, maintenance_work_mem for builds.

Updated 14 min
Read →
Databases
CustomersHelp-centre appYour databaseServerless indexTenant A namespaceTenant B namespaceReranker

Pinecone Serverless: Namespaces, Hybrid Search, and Reranking

Intermediate

Pinecone serverless GA (2024), namespaces for multitenancy, sparse-dense hybrid, .NET PineconeClient, batch upserts, metadata filtering, built-in rerankers (BGE/Cohere), tenant offboarding via DeleteAll.

Updated 13 min
Read →
Databases
Support agentsSearch appWeaviateKeyword scoreVector scoreLabelled queries

Weaviate 1.27+: Multi-Tenancy, Dynamic Indexes, and Generative Search

AdvancedPRO

Weaviate 1.27/1.28 multi-tenancy, dynamic indexes (flat → HNSW), text2vec/generative modules, gRPC v4 clients, hybrid alpha, generative-openai for RAG-in-one-call, tenant offboarding.

Updated 14 min
Read →
AI Engineering
UsersSearchEmbedding modelVector indexNew index

Embeddings: From Theory to Production Choice

Intermediate

Convert text, images, and code into dense vectors that capture semantic meaning — the foundational primitive of modern AI systems, and the choice that dominates RAG quality.

Updated 11 min
Read →
LLM Model Landscape
Test questionsAssistantClaim checkerSourcesMetricsLive answers

Hallucination Testing: Measuring What the Model Makes Up

Intermediate

The three kinds of hallucination, a test set that includes questions with no answer, claim-by-claim faithfulness scoring, and what lowers the rate.

Updated 11 min
Read →